Data Selection Through Iterative Self-Filtering:它和通用视觉自监督的关系在于:让 CLIP 在训练过程中自举选择 clean + diverse 数据,是视觉语言预训练数据闭环的实用方向
高相关;详见方法、贡献和实验边界。
Data Selection Through Iterative Self-Filtering for Vision-Language Settings arXiv 新增 · CLIP data filtering / bootstrapped pretraining 原文链接
编号2606.23611优先级P1类别arXiv 新增 · CLIP data filtering / bootstrapped pretraining会议arXiv 新增 · CLIP data filtering / bootstrapped pretraining方法让 CLIP 在训练过程中自举选择 clean + diverse 数据,是视觉语言预训练数据闭环的实用方向来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:让 CLIP 在训练过程中自举选择 clean + diverse 数据,是视觉语言预训练数据闭环的实用方向。 高相关;详见方法、贡献和实验边界。
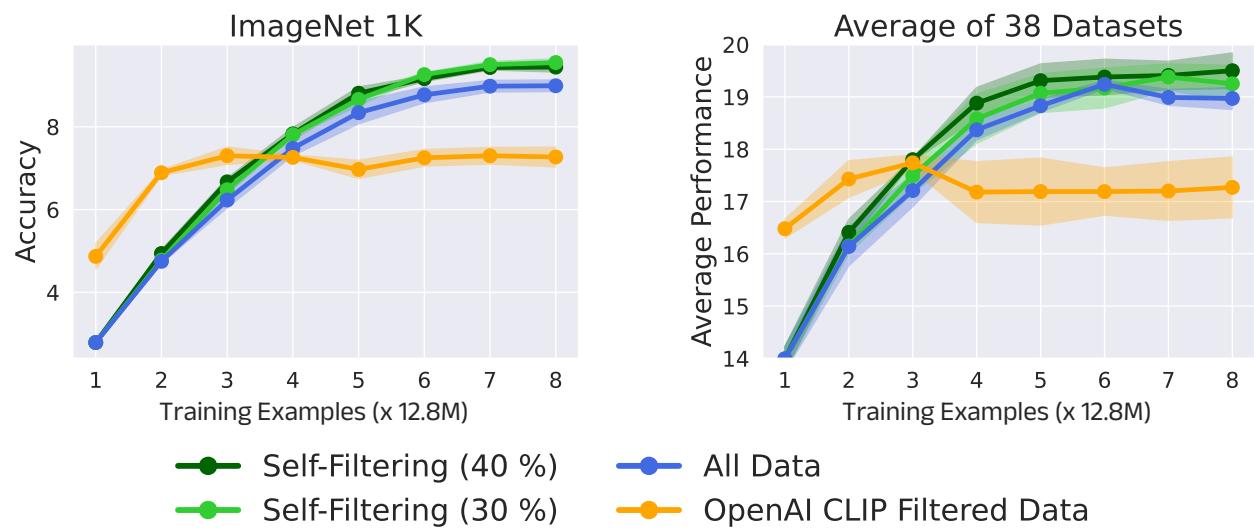
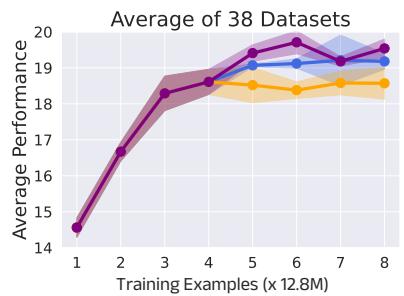
Figureure 1 · : Datacomp small experiments trained to pass over $8 \times 12.8M$ exaFigure 1: Datacomp small experiments trained to pass over $8 \times 12.8M$ examples (using 11.49M unique samples). We compare models trained by Self-Filtering (with mix of $30\%$ or $40\%$ selected samples) to models trained on either all data, or trained on data selected by OpenAI's CLIP. The proposed Self-Filtering approach leads to improved results. We show the average and $\pm 1$ standard deviation of 3 seeds.这张图/表用于判断 Data Selection Through Iterative Self-Filtering 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。All Data OpenAI CLIP Filtered Data Fix Data Mix: OpenAI CLIP Filtered + All Figure 3: CompAll Data OpenAI CLIP Filtered Data Fix Data Mix: OpenAI CLIP Filtered + All Figure 3: Comparison of CLIP models trained on different data subsets: the entire data, exclusively the data filtered by OpenAI's CLIP, or a mix of all and the same filtered data. In the second and third panel the models are initialized from the same checkpoint from steps corresponding to 12.8 M and $4 \times 12.8$ M examples seen, respectively. For a small number of training steps, using exclusively filtered data is best, but overall, the mixing strategy achieves the best results. Unlike before, we use a constant learning rate here.这张图/表用于判断 Data Selection Through Iterative Self-Filtering 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:让 CLIP 在训练过程中自举选择 clean + diverse 数据,是视觉语言预训练数据闭环的实用方向。
方法拆解
让 CLIP 在训练过程中自举选择 clean + diverse 数据,是视觉语言预训练数据闭环的实用方向