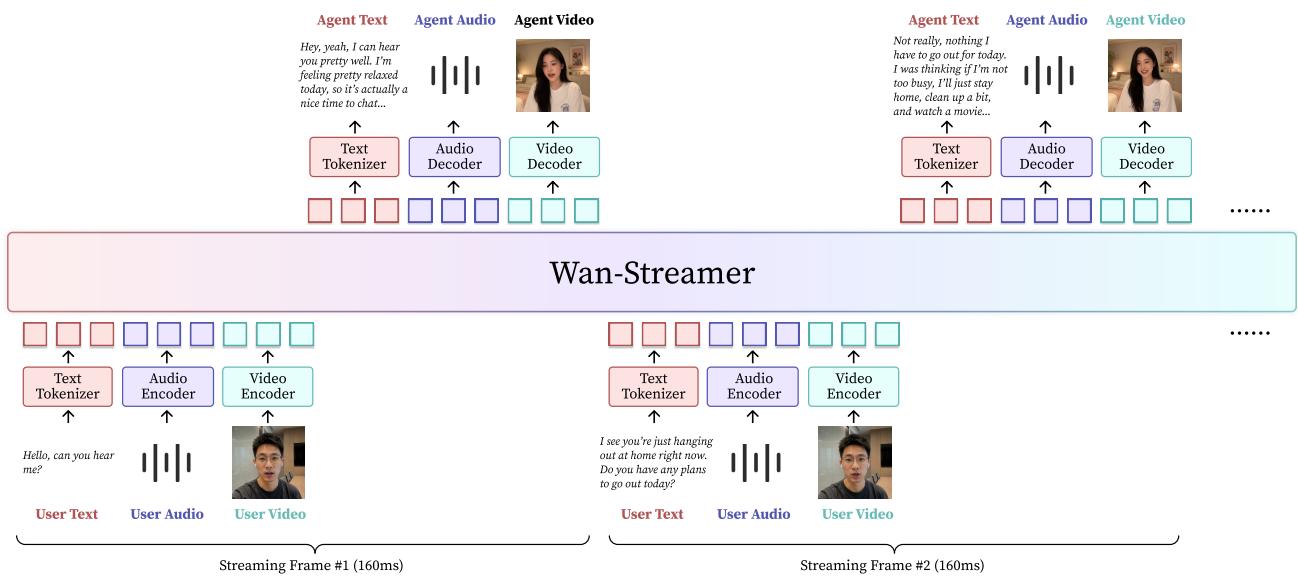
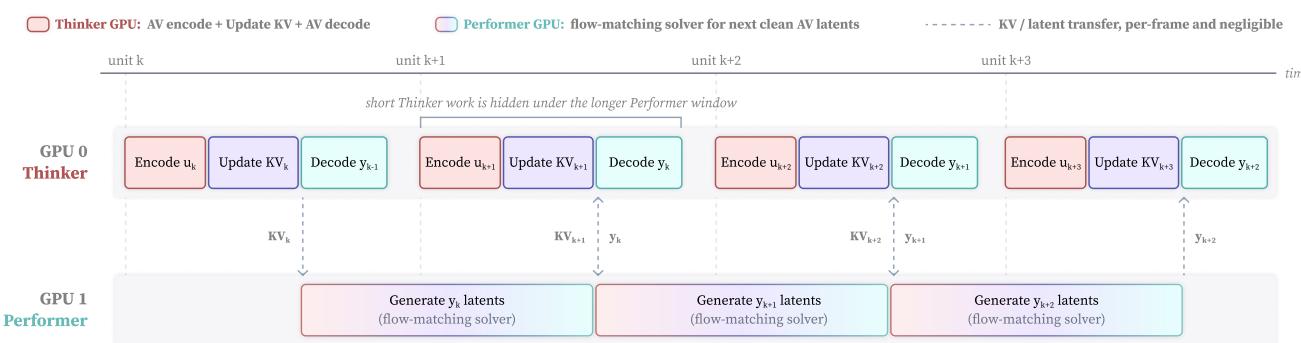
Figureure 1 · Overview of Wan-StreamerFigure 1 Overview of Wan-Streamer. It models language, audio, and video as both input and output within a single Transformer, using block-causal attention for incremental streaming generation.这张图概括 Wan-Streamer v0.1 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · Thinker-performer overlap during streaming inferenceFigure 2 Thinker-performer overlap during streaming inference. At unit k, the thinker encodes the current user observations u<sub>k</sub>, updates the KV cache, and decodes the previous response latents y<sub>k−1</sub> for immediate emission. The performer receives the current KV slice and runs only the flow-matching solver to generate the next clean audio-visual latents y<sub>k</sub>, which are returned to the thinker at the following unit. For clarity, performer windows are drawn as one full 160 ms streaming unit; in practice, real-time throughput only requires the performer time plus KV/latent communication to be below this unit duration.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Wan-Streamer v0.1 的方法或实验,请结合正文精读段落一起看。