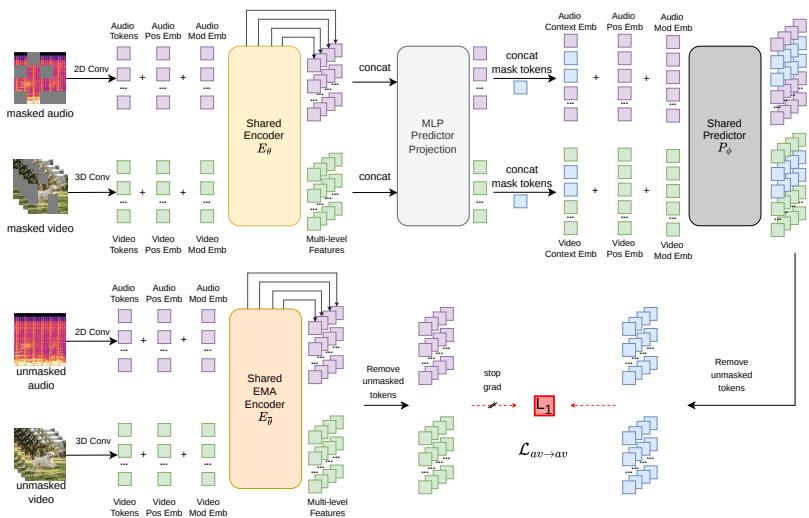
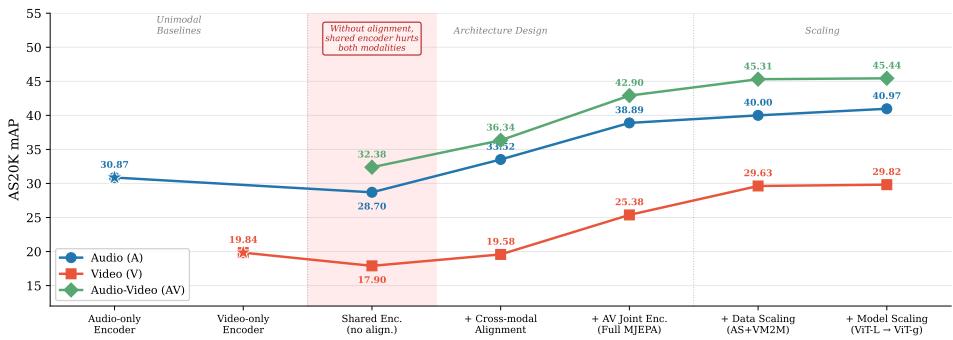
Figureure 4 · : Detailed architecture of MJEPA, illustrated for the joint audio-videFig. 4: Detailed architecture of MJEPA, illustrated for the joint audio-video intramodal prediction $( \mathcal { L } _ { a v a v } )$ . The audio-only $\left( \mathcal { L } _ { a \to a } \right)$ and video-only $( \mathcal { L } _ { v v } )$ cases follow the same pipeline with a single modality branch. Top-left: Masked audio and video inputs are tokenized by modality-specific projection layers (2D Conv for audio, 3D Conv for video), and augmented with modality-specific positional and modality embeddings before being fed to the shared context encoder $E _ { \theta }$ . Top-middle: Multi-level features from intermediate encoder layers are concatenated along the embedding dimension and projected back to the model dimension via a MLP. Top-right: The projected context tokens are concatenated with learnable mask tokens, added with predictorspecific modality embeddings and positional embeddings, and processed by the shared predictor $P _ { \phi }$ to produce multi-level predictions for the masked positions. Bottom: The target branch processes the full, unmasked inputs through the EMA encoder $E _ { \bar { \theta } }$ and extracts multi-level features at the masked positions. The $L _ { 1 }$ loss is computed between the predicted and target representations with a stop-gradient on the target. Cross-modal predictors are not shown; they operate on pooled last-layer features as described in Sec. 4.3 of the main paper.这张图概括 MJEPA 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 3 · : Progressive ablation of architecture and scaling on AS20KFig. 3: Progressive ablation of architecture and scaling on AS20K. Starting from unimodal baselines, we first incrementally add components of our architecture (left), then show the efects of data and model scaling (right). A shared encoder without cross-modal alignment (shaded) degrades both modalities below their unimodal baselines. Cross-modal alignment, joint audio-video encoding, and scaling are each critical for learning high-quality, generalizable multimodal representations.这张图概括 MJEPA 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。