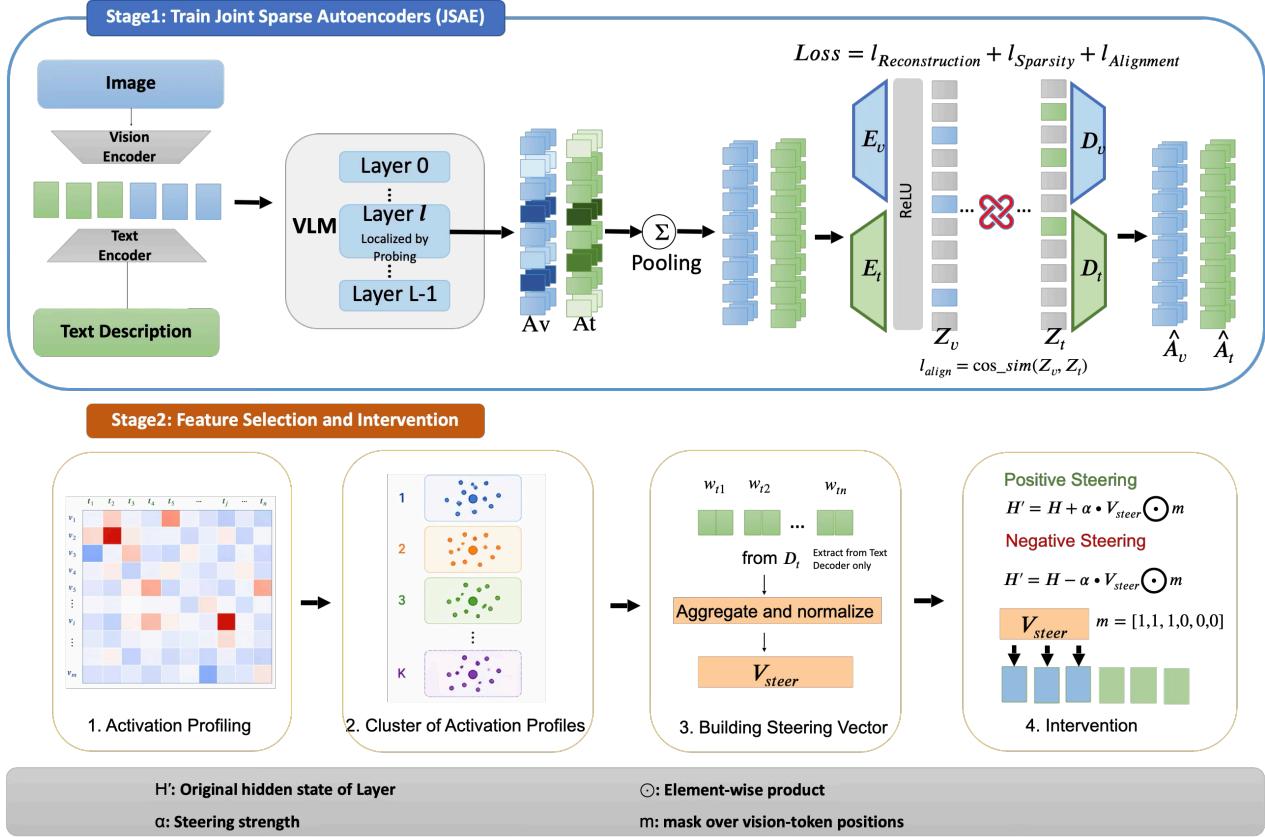
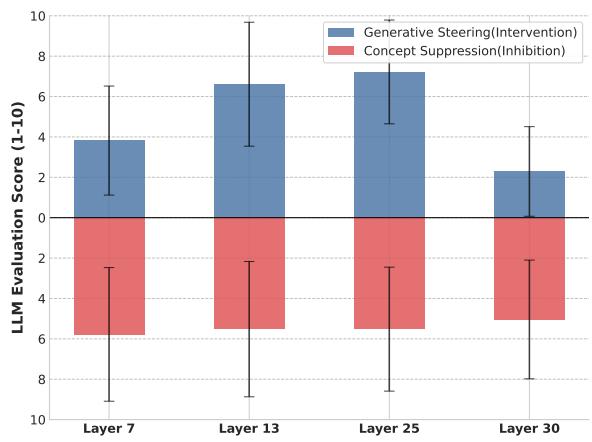
Figureure 1 · : Overview of the JSAE FrameworkFigure 1: Overview of the JSAE Framework. Stage 1 (Training): Vision and text activations are factorized into a shared overcomplete latent space, with a cosine-similarity constraint $( l _ { a l i g n } )$ aligning their decoder directions. Stage 2 (Intervention): Aligned semantic directions are extracted from the Text Decoder and additively injected onto image-token positions (mask m) during the forward pass, steering visual processing and subsequent generation.这张图概括 Steering Vision-Language Models with Joint 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · : Asymmetric Intervention DynamicsFigure 2: Asymmetric Intervention Dynamics. Upper (blue): additive steering Accuracy peaks at Layer 25 (≈ 7.22). Lower (red): suppression scores stay in a narrow range (≈ 5.5) across depths. Additive controllability is layer-specific, while suppression effects appear across all probed layers.这张图/表用于判断 Steering Vision-Language Models with Joint 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。