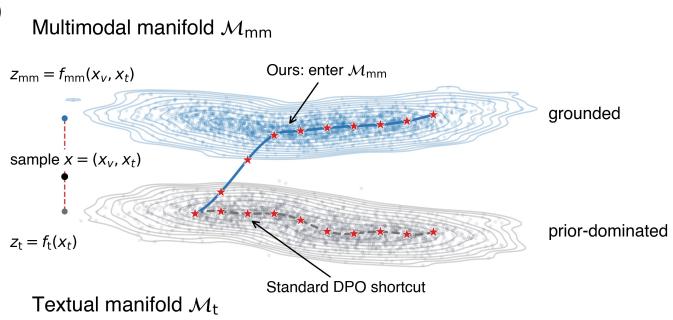
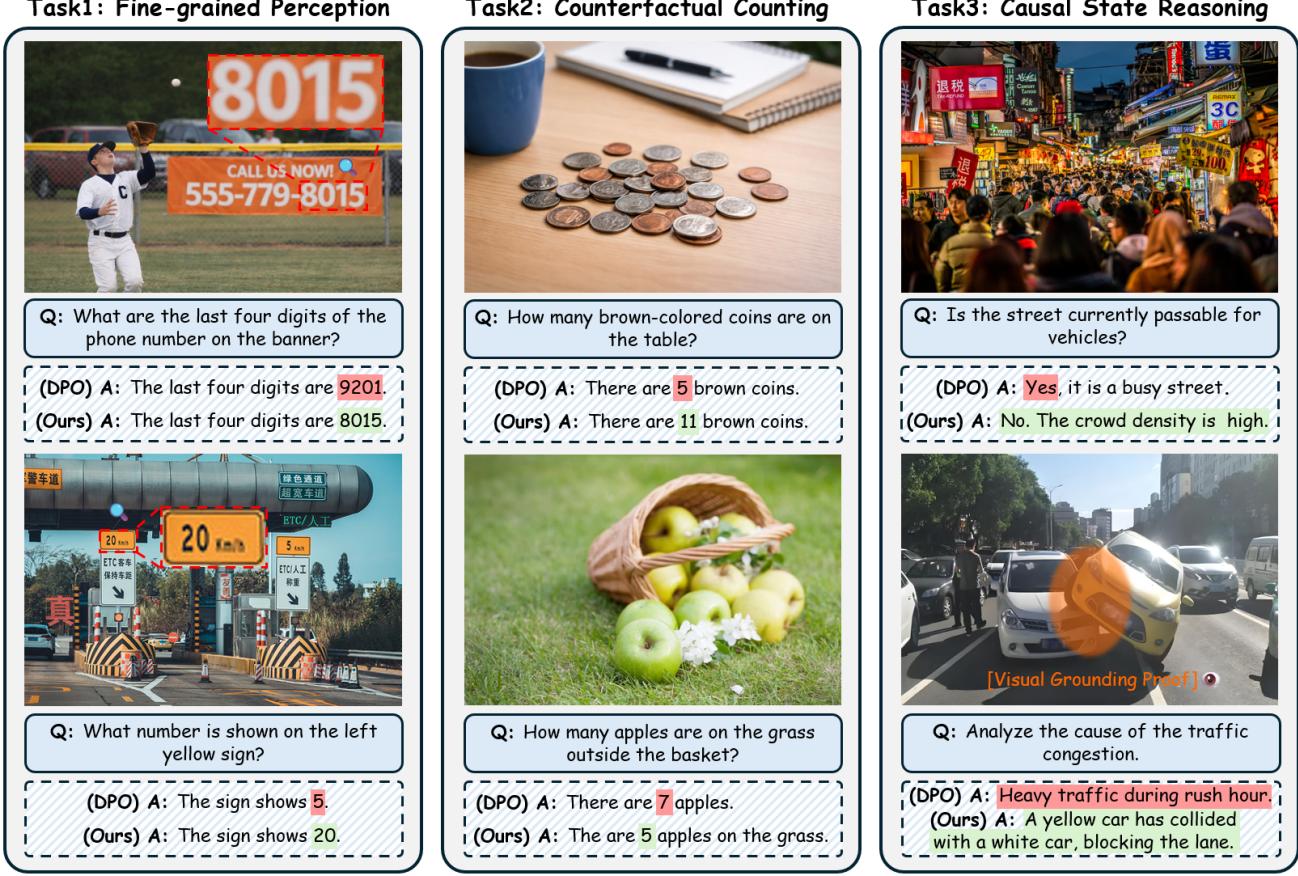
Figureure 2 · Visual laziness in MLLMsFigure 2 Visual laziness in MLLMs. (a) Degenerate posterior and vanishing visual gain. When predictions are dominated by language priors $P ( \boldsymbol { y } | \boldsymbol { x } _ { \mathrm { t } } )$ , the multimodal posterior $P ( y | x _ { \mathrm { v } } , x _ { \mathrm { t } } )$ collapses toward the vision-blind prior $P ( y | x _ { \mathrm { v } } ^ { \mathcal { D } } , x _ { \mathrm { t } } )$ , yielding a diminished visual information gain (VIG). (b) Optimization geometry of visual shortcuts. A geometric view illustrates an optimization shortcut that stays on the textual manifold $\mathcal { M } _ { \mathrm { t } }$ and converges to a priordominated region, instead of entering the multimodal manifold ${ \mathcal { M } } _ { \mathrm { m m } }$ for grounded reasoning, motivating our VIGIL framework. Refer to [14–18] for the definition of manifold.这张图概括 Staying VIGILant 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Task3: Causal State Reasoning Figure 5 Qualitative Comparison of Visual GroundingTask3: Causal State Reasoning Figure 5 Qualitative Comparison of Visual Grounding. MLLMs often exhibit visual laziness by relying on language priors, resulting in plausible but factually incorrect hallucinations (red). In contrast, VIGIL anchors reasoning to visual evidence x (green). Task 1 (Left): In fine-grained perception, VIGIL accurately identifies the digits 8015 as verified by the visual grounding box, whereas the DPO baseline hallucinates 9201. Task 2 (Middle): In counterfactual counting, the DPO baseline defaults to generic numbers based on priors, while VIGIL correctly identifies 11 coins and 5 apples. Task 3 (Right): In causal reasoning, instead of providing generic descriptions, VIGIL identifies specific physical states, such as vehicle collisions, to derive correct logical conclusions.这张图/表用于判断 Staying VIGILant 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。