通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-06-27 图像表征 · VFM · JEPA · 视频预训练
arXiv new; ECCV 2026; visual tokenizer · P0 · 2026-06-27

ViQ:它和通用视觉自监督的关系在于:任意分辨率视觉输入被压成 text-aligned discrete representation,直接影响统一多模态模型的视觉 token 接口

高相关;详见方法、贡献和实验边界。

编号2606.27313 优先级P0 类别arXiv new; ECCV 2026; visual tokenizer 会议arXiv new; ECCV 2026; visual tokenizer 方法任意分辨率视觉输入被压成 text-aligned discrete representation,直接影响统一多模态模型的视觉 token 接口 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:任意分辨率视觉输入被压成 text-aligned discrete representation,直接影响统一多模态模型的视觉 token 接口。 高相关;详见方法、贡献和实验边界。
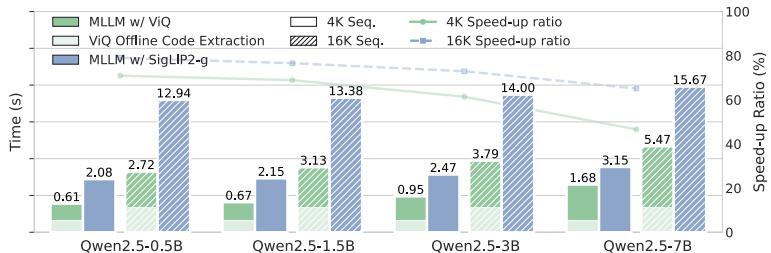
(a) Comparison of Forward Time of MLLMs with Diferent Visual Encoders
(a) Comparison of Forward Time of MLLMs with Diferent Visual Encoders(a) Comparison of Forward Time of MLLMs with Diferent Visual Encoders这张图/表用于判断 ViQ 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
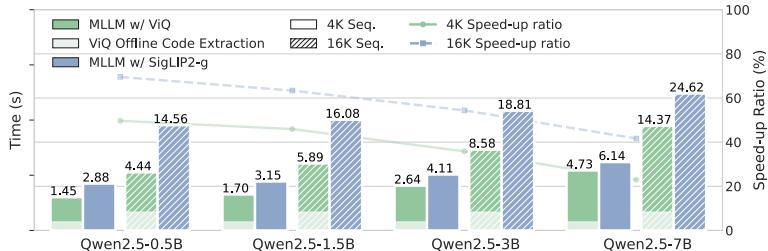
(b) Comparison of Step Time of MLLMs with Diferent Visual Encoders Fig
(b) Comparison of Step Time of MLLMs with Diferent Visual Encoders Fig(b) Comparison of Step Time of MLLMs with Diferent Visual Encoders Fig. 3: Comparisons on Training Efficiency Across Different Visual Encoders. We conduct the experiments to compare the efficiency of ViQ and SigLIP2-g on the 4k and 16k training.这张图/表用于判断 ViQ 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。

核心问题

它和通用视觉自监督的关系在于:任意分辨率视觉输入被压成 text-aligned discrete representation,直接影响统一多模态模型的视觉 token 接口。

方法拆解

任意分辨率视觉输入被压成 text-aligned discrete representation,直接影响统一多模态模型的视觉 token 接口

主要贡献

高相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。