Beyond the Hard Budget:它和通用视觉自监督的关系在于:目标是解释 vision foundation model activations,适合作为 VFM 表征诊断工具背景
中相关;详见方法、贡献和实验边界。
Beyond the Hard Budget: Sparsity Regularizers for More Interpretable Top-k Sparse Autoencoders arXiv new; SAE/VFM interpretability 原文链接
编号2606.27321优先级P3类别arXiv new; SAE/VFM interpretability会议arXiv new; SAE/VFM interpretability方法目标是解释 vision foundation model activations,适合作为 VFM 表征诊断工具背景来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:目标是解释 vision foundation model activations,适合作为 VFM 表征诊断工具背景。 中相关;详见方法、贡献和实验边界。
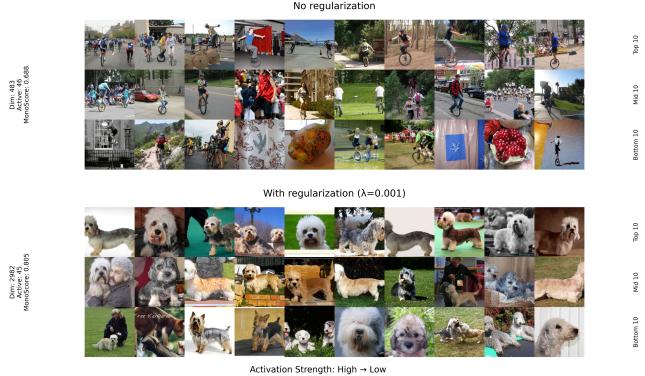
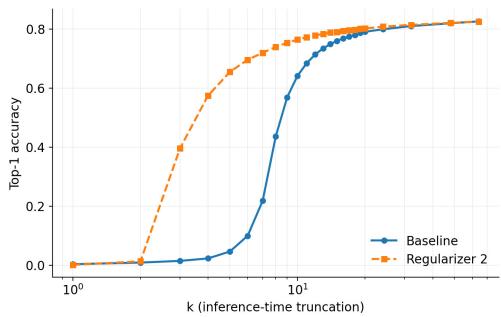
Figureure 2 · : Qualitative comparison at matched monosemanticity rank (ViT-L/16, k Figure 2: Qualitative comparison at matched monosemanticity rank (ViT-L/16, k = 32). Top: a baseline latent (unit 483, monosemanticity 0.688); bottom: the Regularizer 1 (of-support $\ell _ { 1 } )$ latent at the same monosemanticity rank (unit 2982, monosemanticity 0.805)—two distinct units occupying the same rank. In each block, rows show the Top-10, Mid-10, and Bottom-10 activating images. Each row is ordered by decreasing activation strength (high → low).这张图/表用于判断 Beyond the Hard Budget 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 5 · : Two consequences of the concentration induced by Regularizer $2 ( \eFigure 5: Two consequences of the concentration induced by Regularizer $2 ( \ell _ { 1 } / \ell _ { 2 } \mathrm { r a t i o } )$ , on ImageNet-1K with CLIP ViT-L/14. (left) Robustness to the inference-time number of retained units: each panel is a model trained at a fixed k (left to right: $k = 3 2 , 6 4$ , 128; dotted line) and evaluated while varying $k _ { \mathrm { i n f } }$ at inference; both axes are logarithmic. (right) Probing under activation truncation at $k = 6 4 \colon$ a linear probe is trained on codes truncated to their $k ^ { \prime }$ largest activations, and top-1 test accuracy is plotted against $k ^ { \prime }$ (log scale).这张图/表用于判断 Beyond the Hard Budget 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:目标是解释 vision foundation model activations,适合作为 VFM 表征诊断工具背景。
方法拆解
目标是解释 vision foundation model activations,适合作为 VFM 表征诊断工具背景