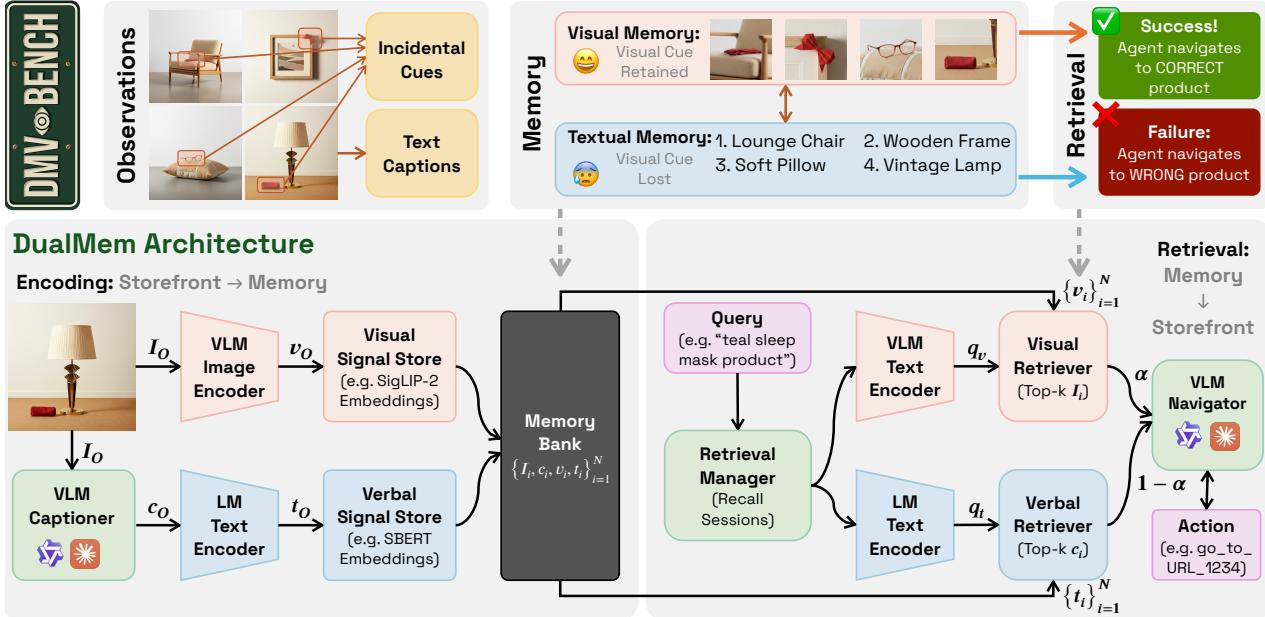
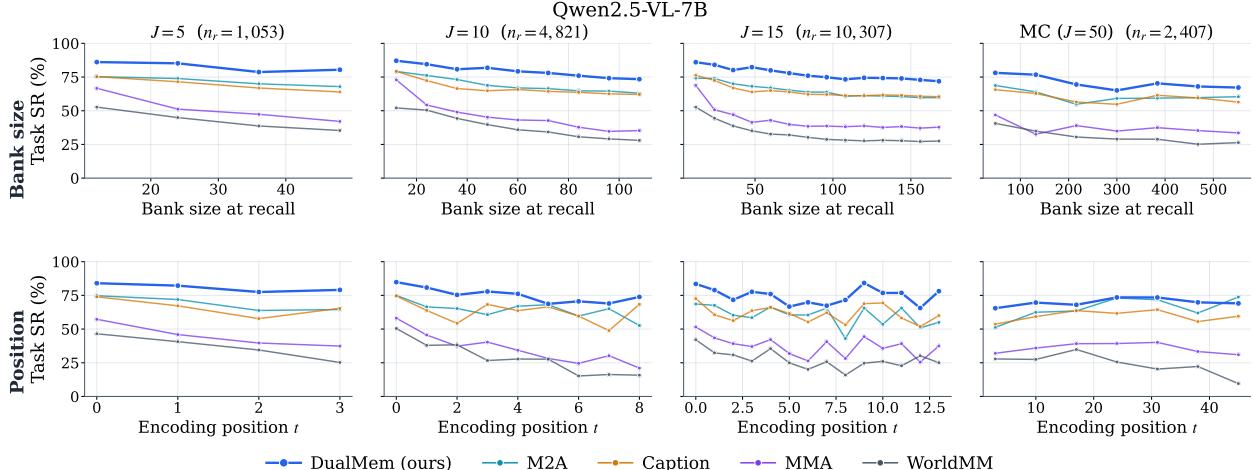
Figureure 2 · : (a) DMV-BenchFigure 2: (a) DMV-Bench. Each visited product carries a unique incidental cue baked into its image and barred from every text channel by the L2-leakage contract. (b) DualMem Architecture. Each observation is dual-coded into a visual embedding and a verbal embedding, stored as four channels in one bank; at retrieval, visual and verbal top-k scores are fused with a tunable weight α before the VLM agent emits an action.这张图概括 DMV-Bench 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。DualMem (ours) M2A Caption MMA WorldMM Figure 5: Two confound checks, all five memory archDualMem (ours) M2A Caption MMA WorldMM Figure 5: Two confound checks, all five memory architectures, Qwen2.5-VL-7B. Top: TSR vs. memory-bank size at recall. Bottom: TSR by encoding position t. DualMem (blue) stays roughly flat across both axes at every J; baselines degrade as the bank grows and exhibit weak position drifts.这张图概括 DMV-Bench 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。