arXiv new; video/world model representation learning · P0 · 2026-06-30
ReWorld:它和通用视觉自监督的关系在于:ReWorld 直接优化 world action model 的中间表征,和视频预训练、JEPA/world-model 线高度相关
高相关;详见方法、贡献和实验边界。
ReWorld: Learning Better Representations for World Action Models arXiv new; video/world model representation learning 原文链接
编号2606.27504优先级P0类别arXiv new; video/world model representation learning会议arXiv new; video/world model representation learning方法ReWorld 直接优化 world action model 的中间表征,和视频预训练、JEPA/world-model 线高度相关来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:ReWorld 直接优化 world action model 的中间表征,和视频预训练、JEPA/world-model 线高度相关。 高相关;详见方法、贡献和实验边界。
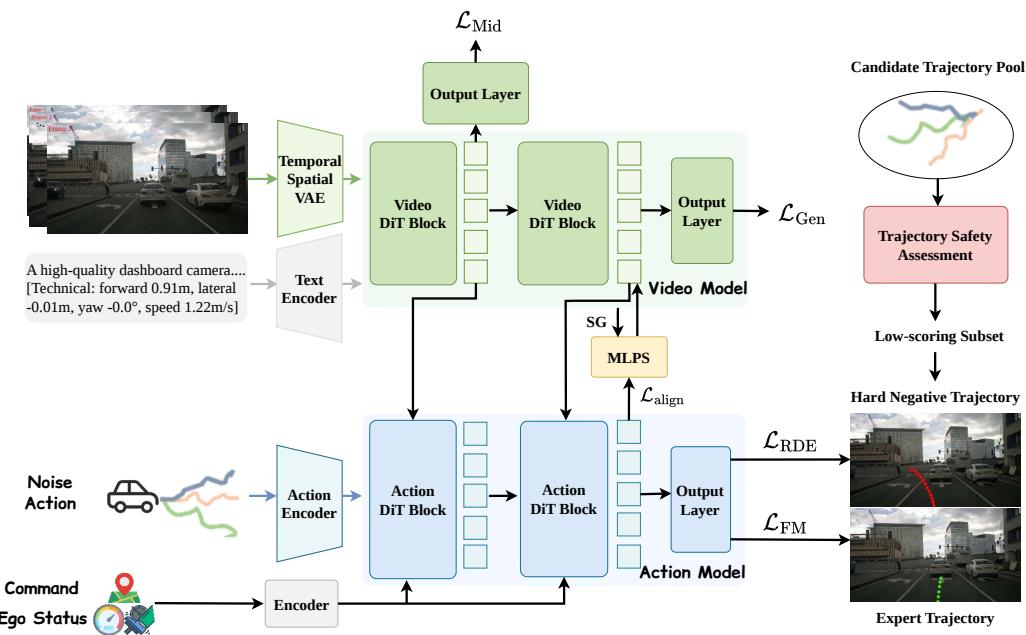
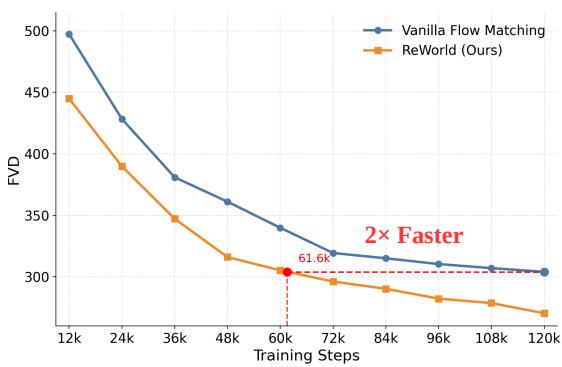
Figureure 1 · : Overview of the ReWorld frameworkFigure 1: Overview of the ReWorld framework. ReWorld trains a chained world-action model through three stages. Stage 1 trains the Video DiT with the generation loss and an intermediateguidance loss, which supervises auxiliary heads on selected blocks to predict the flow-matching velocity target, making intermediate representations future-predictive. Stage 2 freezes the Video DiT and trains the Action DiT with trajectory flow matching and a world-alignment loss, aligning each post-cross-attention action state to its attended video readout via cosine similarity; stop-gradient (SG) is applied to the readout to prevent this loss from perturbing the video branch. Stage 3 jointly fine-tunes both DiTs with trajectory flow matching and RDE, which repels the predicted trajectory from geometrically close yet low-scoring hard negatives drawn from an offline candidate pool evaluated by the PDM simulator.这张图概括 ReWorld 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。(b) Figure 2: Intermediate-supervised inference and accelerated convergence of ReWorld(b) Figure 2: Intermediate-supervised inference and accelerated convergence of ReWorld. (a) During sampling, ReWorld exploits the discrepancy between the intermediate prediction $v _ { i }$ and the final prediction $v _ { f }$ to form a corrected velocity $v _ { w } ,$ which is used by the scheduler to advance the denoising trajectory. (b) ReWorld achieves faster convergence than Vanilla Flow Matching by approximately $2 \times$ without using any external models or supervision.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 ReWorld 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:ReWorld 直接优化 world action model 的中间表征,和视频预训练、JEPA/world-model 线高度相关。
方法拆解
ReWorld 直接优化 world action model 的中间表征,和视频预训练、JEPA/world-model 线高度相关