Large Language Model Teaches Visual:它和通用视觉自监督的关系在于:用语言-only LLM 产生细粒度概念监督来蒸馏 vision-only student,直接对应视觉表征蒸馏与弱多模态监督
高相关;详见方法、贡献和实验边界。
Large Language Model Teaches Visual Students: Cross-Modality Transfer of Fine-Grained Conceptual Knowledge arXiv new; ICML 2026; language-to-vision distillation 原文链接
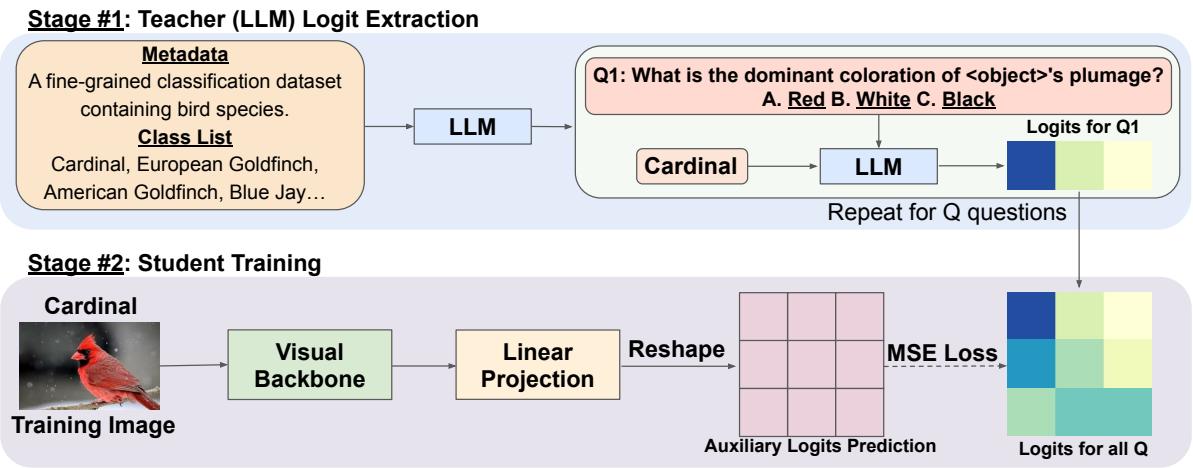
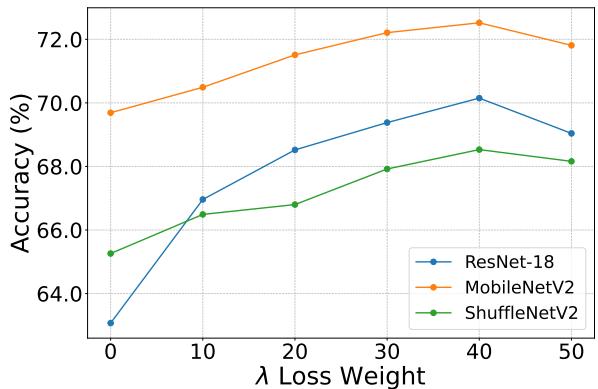
Figureure 1 · Overview of LaViDFigure 1. Overview of LaViD. Stage #1: The LLM is prompted with class metadata and names to generate diverse multiple-choice questions (MCQs) that capture high-level semantic differences. These are instantiated with each class to extract soft label distributions over answer options, forming a conceptual signature per class. Stage #2: The student processes an image through a visual backbone and auxiliary head to predict logits aligned with the LLM’s question space. It is trained with a standard classification loss (not shown) and an auxiliary MSE loss against the LLM-derived targets.这张图概括 Large Language Model Teaches Visual 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figure AFigure A. Effect of loss weight λ on student accuracy for ResNet-18, MobileNetV2, and ShuffleNetV2 on the CUB dataset.这张图/表用于判断 Large Language Model Teaches Visual 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。