arXiv new; equivariant ViT architecture · P2 · 2026-06-30
A Unified Framework for Vision:它和通用视觉自监督的关系在于:给 ViT 加 O(2) 离散子群等变性,在数据稀缺视觉表征学习中可能减少对数据增强的依赖
中相关;详见方法、贡献和实验边界。
A Unified Framework for Vision Transformers Equivariant to Discrete Subgroups of $\mathrm{O}(2)$ arXiv new; equivariant ViT architecture 原文链接
编号2606.27864优先级P2类别arXiv new; equivariant ViT architecture会议arXiv new; equivariant ViT architecture方法给 ViT 加 O(2) 离散子群等变性,在数据稀缺视觉表征学习中可能减少对数据增强的依赖来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:给 ViT 加 O(2) 离散子群等变性,在数据稀缺视觉表征学习中可能减少对数据增强的依赖。 中相关;详见方法、贡献和实验边界。
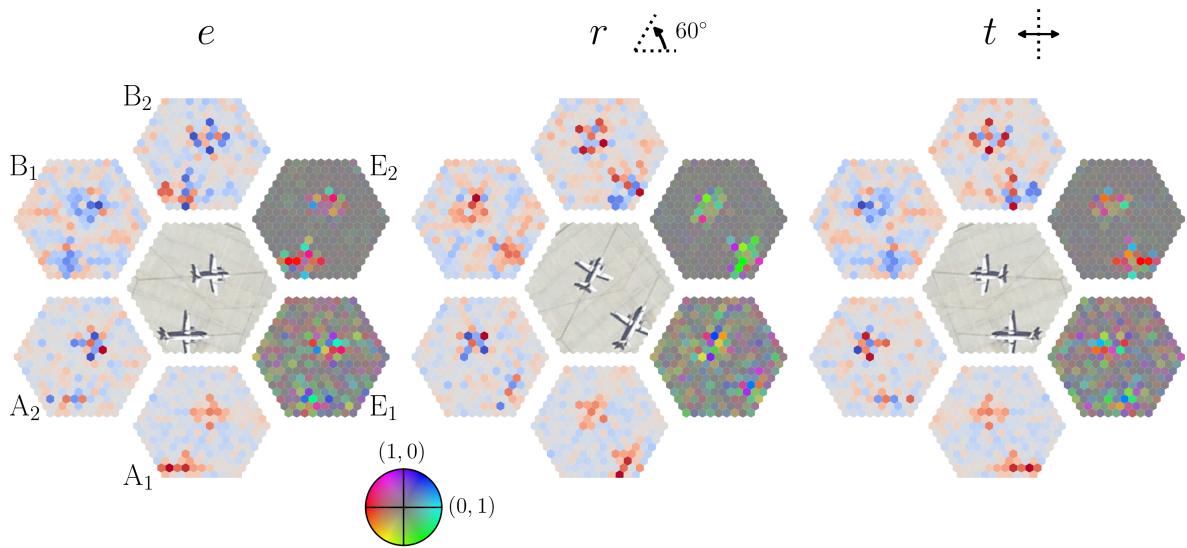
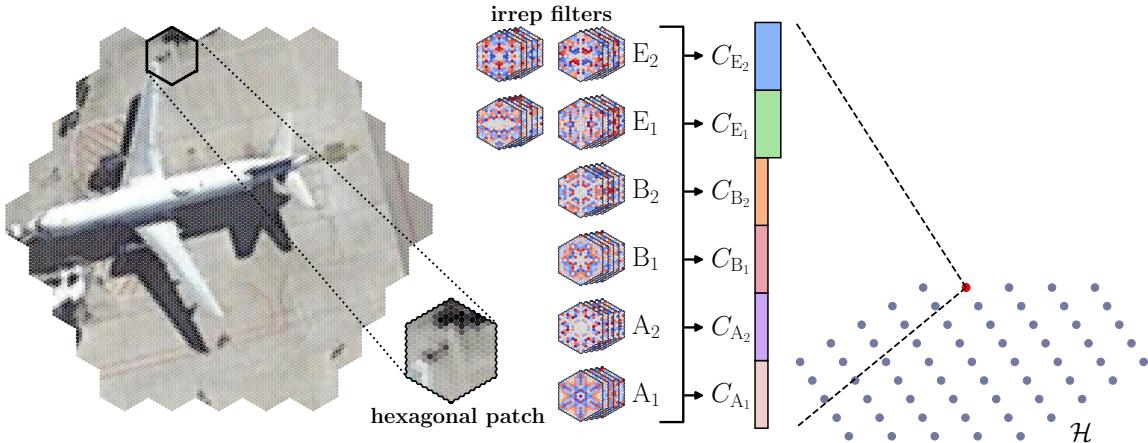
Figureure 1 · : Feature maps of a $D _ { 6 }$ -equivariant vision transformer after Figure 1: Feature maps of a $D _ { 6 }$ -equivariant vision transformer after four transformer blocks in a trained classification model. For each irrep $\rho \in \widehat { D _ { 6 } } .$ , we select a single channel from the irrep component $x ^ { \rho } \in$ $\mathbb { R } ^ { \mathcal { H } } \otimes \mathbb { R } ^ { C _ { \rho } } \otimes V _ { \rho } .$ The features in the two-dimensional irreps $\mathrm { E } _ { 1 }$ and $\mathrm { E } _ { 2 }$ are represented by encoding the polar angle and length of a vector in $\mathbb { R } ^ { 2 }$ using the hue and a combination of saturation and brightness respectively (see the color wheel for reference). For the one-dimensional irreps $( \mathbf { A } _ { 1 } , \mathbf { A } _ { 2 } , \mathbf { B } _ { 1 } , \mathbf { B } _ { 2 } )$ , red and blue indicate positive and negative values respectively, with gray representing zero.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 A Unified Framework for Vision 的方法或实验,请结合正文精读段落一起看。Figureure 2 · : Illustration of the equivariant patch embedding layer with $G = D _ Figure 2: Illustration of the equivariant patch embedding layer with $G = D _ { 6 }$这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 A Unified Framework for Vision 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:给 ViT 加 O(2) 离散子群等变性,在数据稀缺视觉表征学习中可能减少对数据增强的依赖。