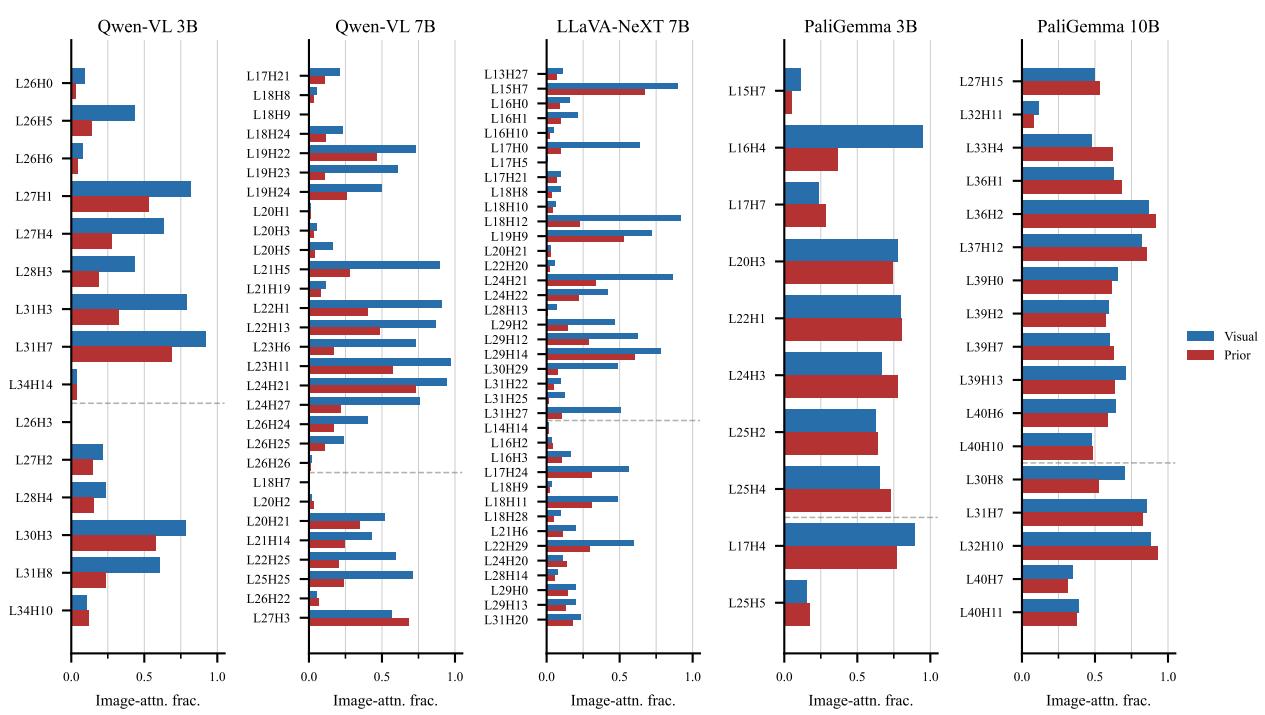
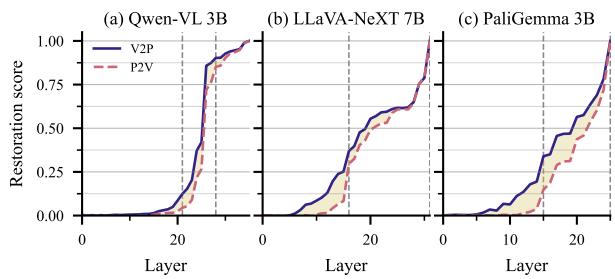
Figureure 10 · : Image-attention fraction for all classified heads across five modelsFigure 10: Image-attention fraction for all classified heads across five models, under Visual (blue) and Prior (red) grounding. Promoting and suppressing heads are separated by the dashed line within each panel. Qwen-VL and LLaVA-NeXT show large visual–prior gaps (attention routing); PaliGemma maintains high image-attention under both conditions (representation-routing).这张可视化用来解释 Vision-Default, Prior-Override 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。Figureure 2 · : Residual stream restoration scores $R_{d}(\ell)$ by layer for three Figure 2: Residual stream restoration scores $R_{d}(\ell)$ by layer for three representative models. P2V (dashed) and V2P (solid) patching directions are shown; the shaded region highlights the V2P–P2V asymmetry, and vertical dashed lines mark the critical window boundaries. Across models, V2P restoration rises earlier and more strongly than P2V, indicating that visual information is established before prior knowledge. Different architectures exhibit distinct transition dynamics, ranging from sharp late-layer shifts to gradual multi-layer accumulation. See Appendix B, Figure 6 for all five models.这张图概括 Vision-Default, Prior-Override 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。