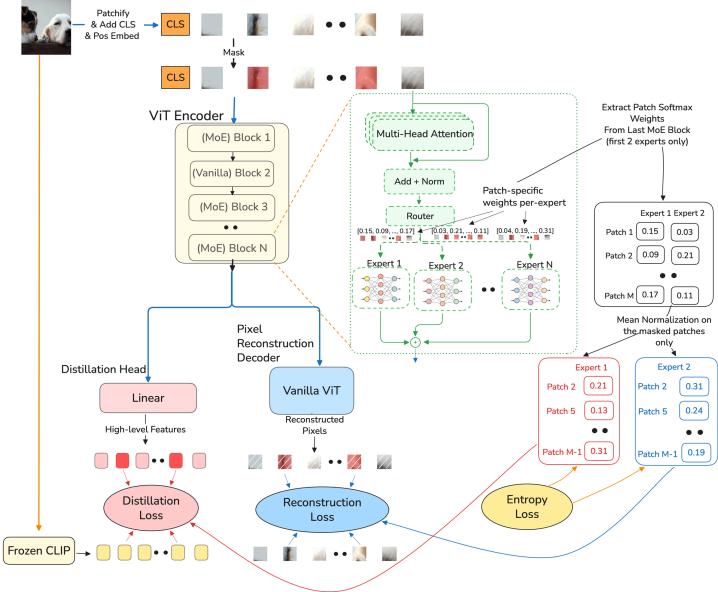
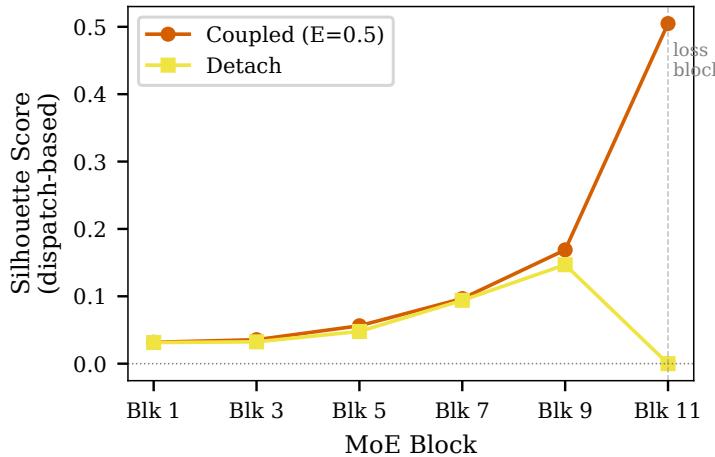
Figureure 2 · : ExPLoRe Framework OverviewFig. 2: ExPLoRe Framework Overview. Soft Mixture of Experts (Soft-MoE) is integrated into the student encoder for patch-level adaptive loss weighting. The student encoder (ViT-Base with alternating MoE blocks at layers {1,3,5,7,9,11}) processes patches while a frozen CLIP teacher provides semantic targets. Soft-MoE dispatch weights D serve as per-patch loss coeficients: each expert weights a diferent training objective. The two routing weight types play distinct roles: dispatch weights D (normalized over patches per expert) form the loss-coupling pathway that carries loss gradients back to the router, whereas combine weights C (normalized over experts per patch) only mix expert outputs in the forward pass. Loss-coupling, where loss gradients flow through D to the router, is the key mechanism enabling learned specialization.这张图概括 ExPLoRe 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。FigFig. A2: Silhouette coeficient across MoE blocks. Dispatch-based cluster assignments on 200 ImageNet validation images (50K tokens subsampled). The coupled model develops strong expert specialization at Block 11 (the loss block), while the detach ablation collapses to zero specialization at this block. Early blocks show similar routing structure in both models.这张图/表用于判断 ExPLoRe 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。