Delta-JEPA:它和通用视觉自监督的关系在于:针对 JEPA 式 world model 的 action-insensitive collapse,直接在 latent displacement 上加动作监督
高相关;详见方法、贡献和实验边界。
Delta-JEPA: Learning Action-Sensitive World Models via Latent Difference Decoding arXiv new; JEPA/world model 原文链接
编号2606.31232优先级P0类别arXiv new; JEPA/world model会议arXiv new; JEPA/world model方法针对 JEPA 式 world model 的 action-insensitive collapse,直接在 latent displacement 上加动作监督来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:针对 JEPA 式 world model 的 action-insensitive collapse,直接在 latent displacement 上加动作监督。 高相关;详见方法、贡献和实验边界。
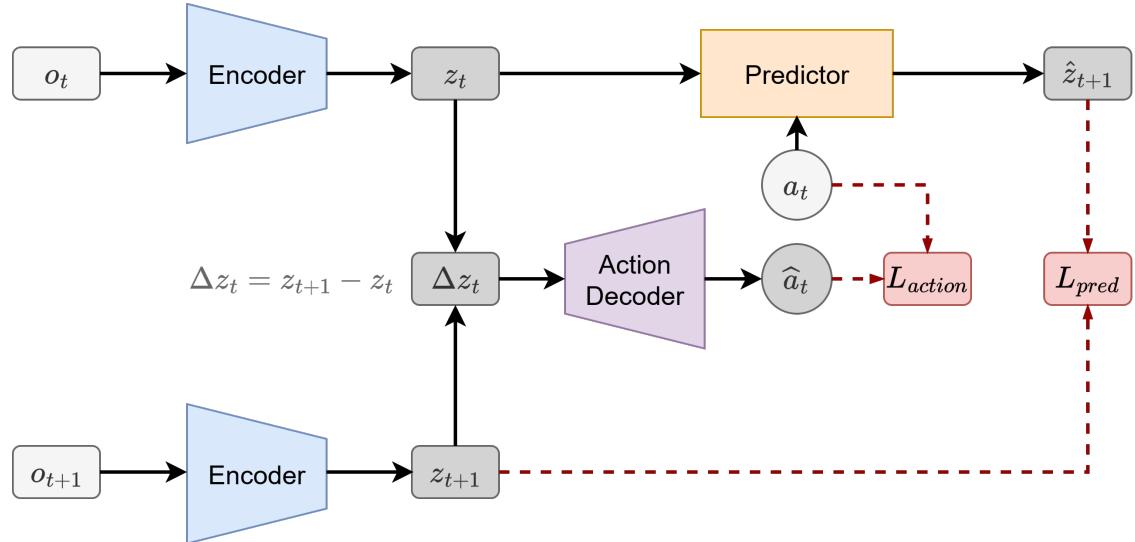
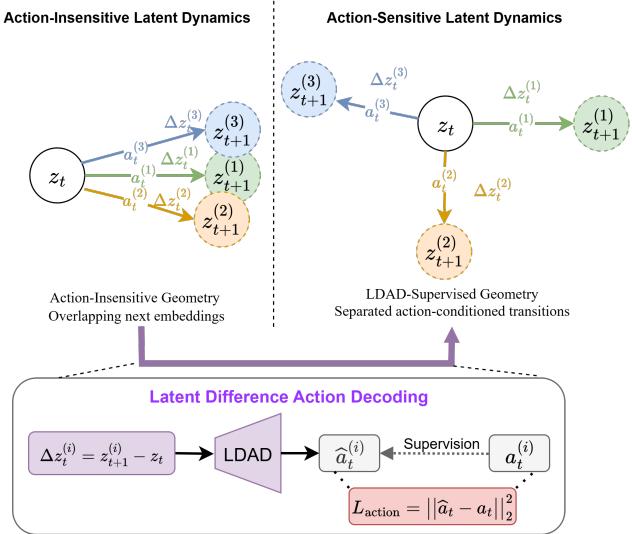
Figureure 1 · : Overview of Delta-JEPA frameworkFigure 1: Overview of Delta-JEPA framework. Raw observations $o _ { t }$ and $o _ { t + 1 }$ are mapped to latent representations $z _ { t }$ and $z _ { t + 1 }$ via a shared encoder. In the forward path, the dynamics predictor forecasts the subsequent representation $\hat { z } _ { t + 1 }$ from $z _ { t }$ and the action ${ { a } _ { t } } ,$ guided by the prediction loss ${ \mathcal { L } } _ { \mathrm { p r e d } } .$ . Concurrently, the Latent Difference Action Decoder receives the latent displacement $\Delta z _ { t }$ to reconstruct the action $\hat { a } _ { t } .$ , supervised by the action loss $\mathcal { L } _ { \mathrm { a c t i o n } }$ . This displacement-based action supervision encourages action-induced latent differences to be distinguishable, and the entire framework is optimized end-toend via $\mathcal { L } = \mathcal { L } _ { \mathrm { p r e d } } + \lambda \mathcal { L } _ { \mathrm { a c t i o n } }$这张图概括 Delta-JEPA 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · : Illustration of LDAD-induced action-sensitive latent geometryFigure 2: Illustration of LDAD-induced action-sensitive latent geometry. Without displacement-level action supervision (top left), different actions from the same latent state $z _ { t }$ may produce similar next embeddings. LDAD computes each displacement $\Delta z _ { t } ^ { ( i ) } = z _ { t + 1 } ^ { ( i ) } - z _ { t } .$ , decodes the action $\hat { a } _ { t } ^ { ( i ) }$ , and supervises it with $\mathcal { L } _ { \mathrm { a c t i o n } } = \| \hat { \boldsymbol { a } } _ { t } - \boldsymbol { a } _ { t } \| _ { 2 } ^ { 2 }$ (bottom). This encourages action-conditioned transitions to occupy distinguishable directions and endpoints in latent space (top right).这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Delta-JEPA 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:针对 JEPA 式 world model 的 action-insensitive collapse,直接在 latent displacement 上加动作监督。
方法拆解
针对 JEPA 式 world model 的 action-insensitive collapse,直接在 latent displacement 上加动作监督