通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-07-01 图像表征 · VFM · JEPA · 视频预训练
arXiv new; visual resampling for MLLMs · P1 · 2026-07-01

MS-Resampler:它和通用视觉自监督的关系在于:MS-Resampler 直接处理 dense visual features 到短 visual token sequence 的信息保留问题

中高相关;详见方法、贡献和实验边界。

编号2606.31383 优先级P1 类别arXiv new; visual resampling for MLLMs 会议arXiv new; visual resampling for MLLMs 方法MS-Resampler 直接处理 dense visual features 到短 visual token sequence 的信息保留问题 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:MS-Resampler 直接处理 dense visual features 到短 visual token sequence 的信息保留问题。 中高相关;详见方法、贡献和实验边界。
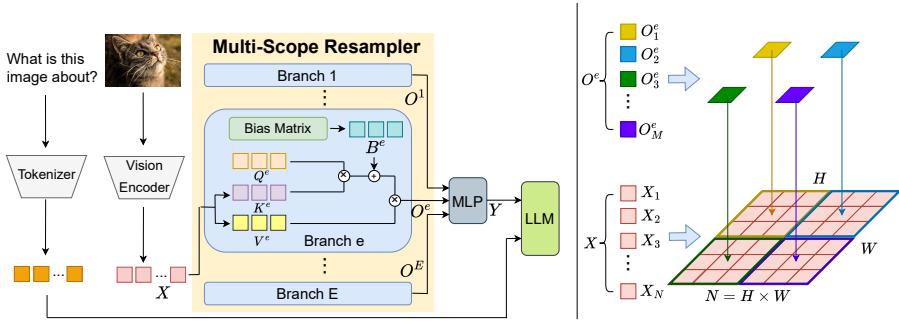
Figureure 2 · : Overview of MS-Resampler
Figureure 2 · : Overview of MS-ResamplerFig. 2: Overview of MS-Resampler. Dense visual tokens extracted by the vision encoder are processed by multiple scoped resampling branches, each operating with a diferent spatial aggregation scope. The outputs from these branches are fused to produce the final compact visual tokens for the language model.这张图概括 MS-Resampler 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
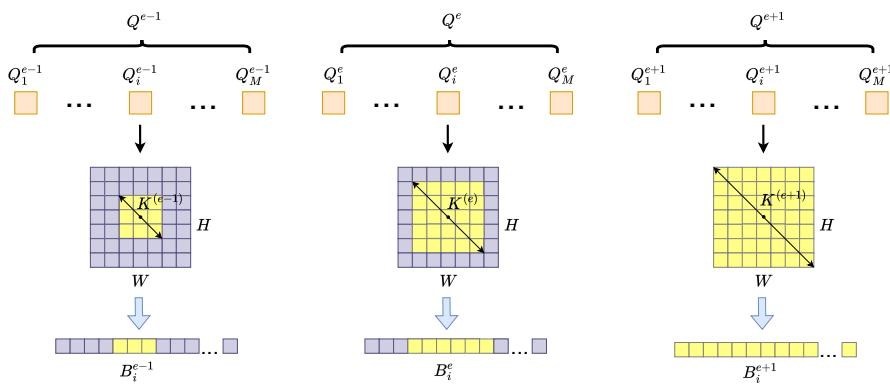
Figureure 3 · : Illustration of spatial attention bias construction for scoped resam
Figureure 3 · : Illustration of spatial attention bias construction for scoped resamFig. 3: Illustration of spatial attention bias construction for scoped resampling. Each query corresponds to an anchor position on the visual token grid. For branch $e ,$ a window of size $k ^ { ( e ) }$ defines its preferred spatial scope.这张可视化用来解释 MS-Resampler 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。

核心问题

它和通用视觉自监督的关系在于:MS-Resampler 直接处理 dense visual features 到短 visual token sequence 的信息保留问题。

方法拆解

MS-Resampler 直接处理 dense visual features 到短 visual token sequence 的信息保留问题

主要贡献

中高相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。