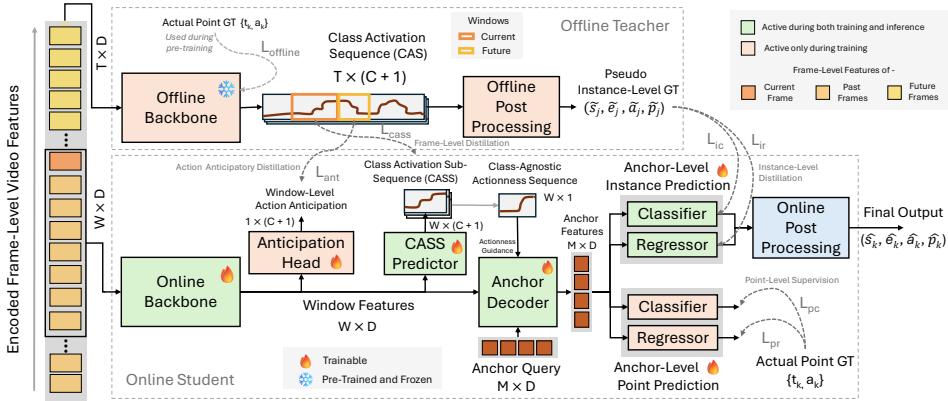
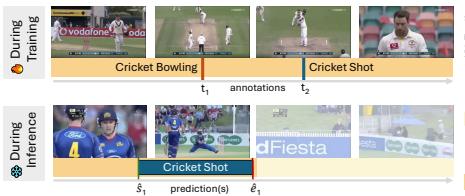
Figureure 3 · : An overview of our proposed OnPoint framework for POTAL taskFig. 3: An overview of our proposed OnPoint framework for POTAL task. The ofline teacher model, pre-trained with point-level annotations, is frozen during training. We distill knowledge into the online student model using pseudo ground truth, frame-wise class activations, and window-level action anticipation objectives. Additionally, original point annotations are directly leveraged to supervise the online model.这张图概括 OnPoint 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · : POTAL taskFig. 2: POTAL task. Training uses one etimestamp per action instance. At test in<sup>g</sup> <sub>n</sub>in<sup>g</sup> u<sup>r</sup>i er<sup>e</sup>time, the model outputs action class and <sup>D Tr</sup>boundaries online, emitting each segment immediately when the action ends (no future frames).这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 OnPoint 的方法或实验,请结合正文精读段落一起看。