arXiv new; foundation video world-model adaptation · P2 · 2026-07-03
RetailSMV:它和通用视觉自监督的关系在于:零售场景偏垂直,但比较 ego/exo 视角对 Cosmos3-Nano 视频 world model 适配的贡献,值得借鉴数据视角
中相关;详见方法、贡献和实验边界。
RetailSMV: Exocentric vs. Egocentric Adaptation of Foundation Video World Models in Retail arXiv new; foundation video world-model adaptation 原文链接
编号2607.00310优先级P2类别arXiv new; foundation video world-model adaptation会议arXiv new; foundation video world-model adaptation方法零售场景偏垂直,但比较 ego/exo 视角对 Cosmos3-Nano 视频 world model 适配的贡献,值得借鉴数据视角来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:零售场景偏垂直,但比较 ego/exo 视角对 Cosmos3-Nano 视频 world model 适配的贡献,值得借鉴数据视角。 中相关;详见方法、贡献和实验边界。
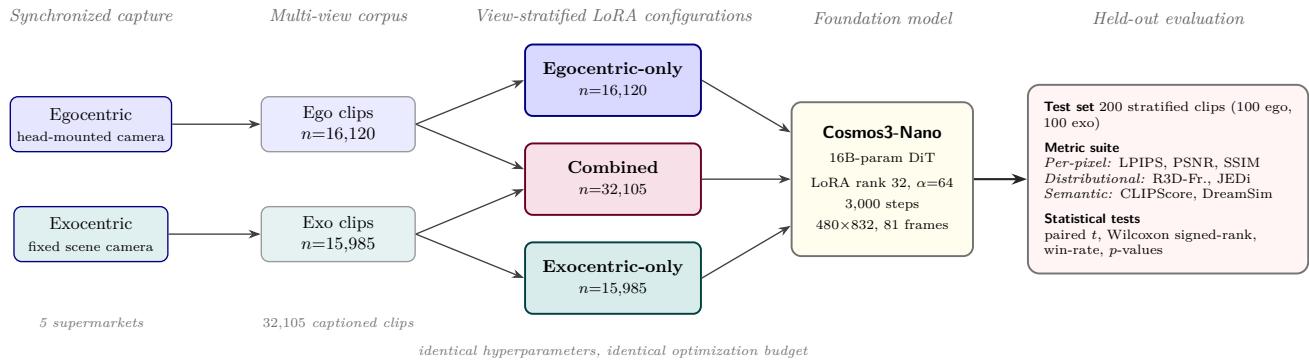
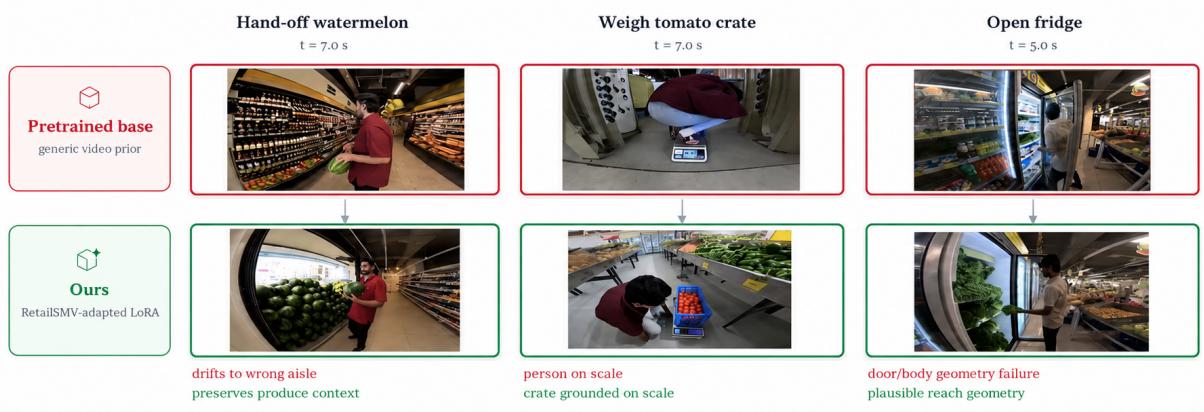
Figureure 2 · Pipeline overviewFigure 2 Pipeline overview. The RetailSMV corpus (section 3.1) provides synchronized egocentric and exocentric video across five real-world supermarkets, yielding 16,120 ego and 15,985 exo clips. Three matched LoRA configurations of the pretrained Cosmos3-Nano foundation video model NVIDIA (2025) (egocentric-only, exocentric-only, and combined) are trained under identical hyperparameters and optimization budget, isolating training-data viewpoint as the variable of interest. Every configuration is evaluated on the same 200-clip stratified held-out test set under a paired statistical protocol.这张图概括 RetailSMV 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Base vsBase vs. RetailSMV-adapted video world model The same retail prompts are continued by a pretrained foundation model and by our adapted model. RetailSMV adaptation preserves scene layout, object permanence, and action grounding where the pretrained model drifts. Figure 1 Base vs. RetailSMV-adapted video world model. The same retail prompts are continued by the pretrained Cosmos3-Nano foundation model (top, red) and by our RetailSMV-adapted LoRA (bottom, green) under identical inference settings. RetailSMV adaptation preserves scene layout (hand-of watermelon), action grounding (weigh tomato crate), and physical geometry (open fridge) where the pretrained baseline drifts.这张可视化用来解释 RetailSMV 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。
核心问题
它和通用视觉自监督的关系在于:零售场景偏垂直,但比较 ego/exo 视角对 Cosmos3-Nano 视频 world model 适配的贡献,值得借鉴数据视角。
方法拆解
零售场景偏垂直,但比较 ego/exo 视角对 Cosmos3-Nano 视频 world model 适配的贡献,值得借鉴数据视角