通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-07-02 图像表征 · VFM · JEPA · 视频预训练
arXiv new/cross; ECCV 2026; visual AR representation alignment · P0 · 2026-07-02

MEPA:它和通用视觉自监督的关系在于:针对 visual autoregressive 模型的多尺度表征冲突,用自监督特征对齐和 MoE 路由修补早期语义

高相关;详见方法、贡献和实验边界。

编号2607.00371 优先级P0 类别arXiv new/cross; ECCV 2026; visual AR representation alignment 会议arXiv new/cross; ECCV 2026; visual AR representation alignment 方法针对 visual autoregressive 模型的多尺度表征冲突,用自监督特征对齐和 MoE 路由修补早期语义 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:针对 visual autoregressive 模型的多尺度表征冲突,用自监督特征对齐和 MoE 路由修补早期语义。 高相关;详见方法、贡献和实验边界。

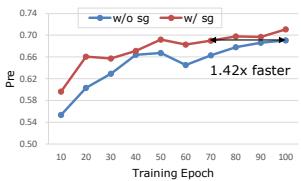
Figureure 5 · : Comparison of VAR with/without semantic guidance
Figureure 5 · : Comparison of VAR with/without semantic guidanceFig. 5: Comparison of VAR with/without semantic guidance. We conduct a comprehensive evaluation of generation performance for models trained with and without semantic guidance. All the models are dense transformers without MoE layers.这张图/表用于判断 MEPA 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
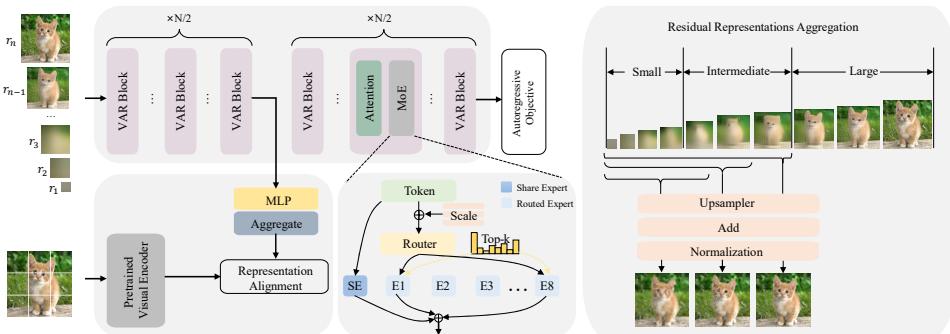
Figureure 2 · : An overview of our proposed MEPA framework
Figureure 2 · : An overview of our proposed MEPA frameworkFig. 2: An overview of our proposed MEPA framework. We follow the next-scale prediction paradigm of VAR [49], and introduce MoE layers to route tokens across scales, allowing them to adaptively select experts. During training, the outputs of the middle block in small and intermediate scales are aggregated to align with a pretrained visual encoder’s features.这张图概括 MEPA 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
核心问题

它和通用视觉自监督的关系在于:针对 visual autoregressive 模型的多尺度表征冲突,用自监督特征对齐和 MoE 路由修补早期语义。

方法拆解

针对 visual autoregressive 模型的多尺度表征冲突,用自监督特征对齐和 MoE 路由修补早期语义

主要贡献

高相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。