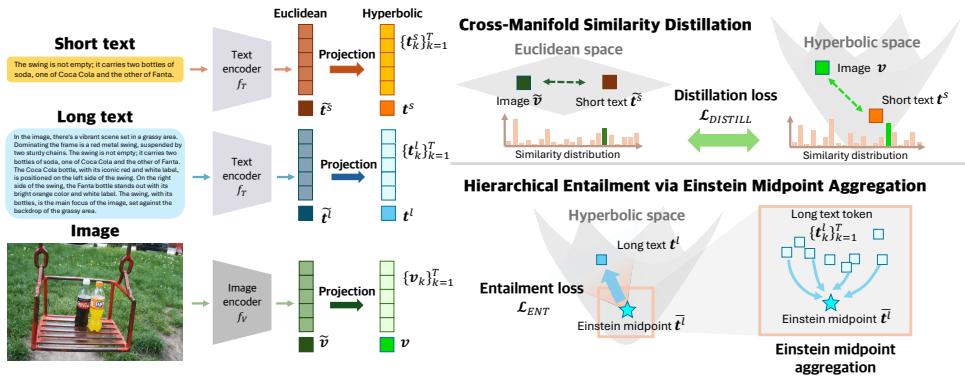
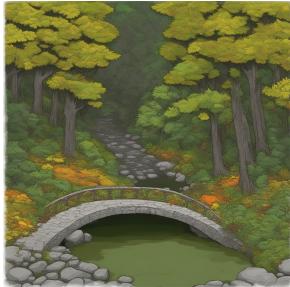
Figureure 2 · : Overview of our HyFL-CLIP frameworkFig. 2: Overview of our HyFL-CLIP framework. Our $_ \mathrm { H y F L - C L I P }$ transfers Euclidean text–image alignment into hyperbolic space via a short-text guided crossmanifold similarity distillation. Hierarchical entailment with Einstein midpoint aggregation abstracts token-wise information within each modality and aligns it with a global representation. Hyperbolic geodesic contrastive loss aligns both long texts and their semantic components with the corresponding image, while an entropy regularizer stabilizes the embedding distribution.这张图概括 HyFL-CLIP 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。HyFL-CLIP (Ours) FigHyFL-CLIP (Ours) Fig. S10: Comparison of images generated from Long-DCI [52] captions using HyFL-CLIP (Ours) integrated SDXL and baselines. Images generated with our model preserve finer visual details and exhibit higher fidelity to the given captions compared to the baseline methods. This demonstrates that HyFL-CLIP provides more precise semantic guidance for text-to-image generation.这张图/表用于判断 HyFL-CLIP 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。