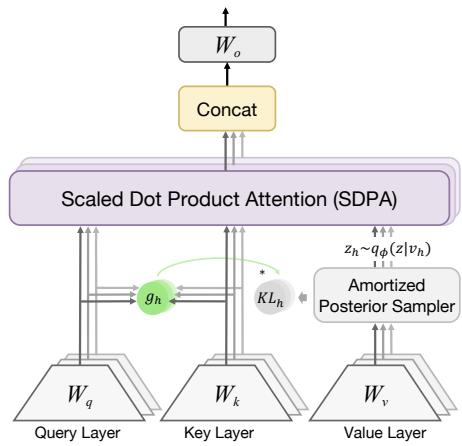
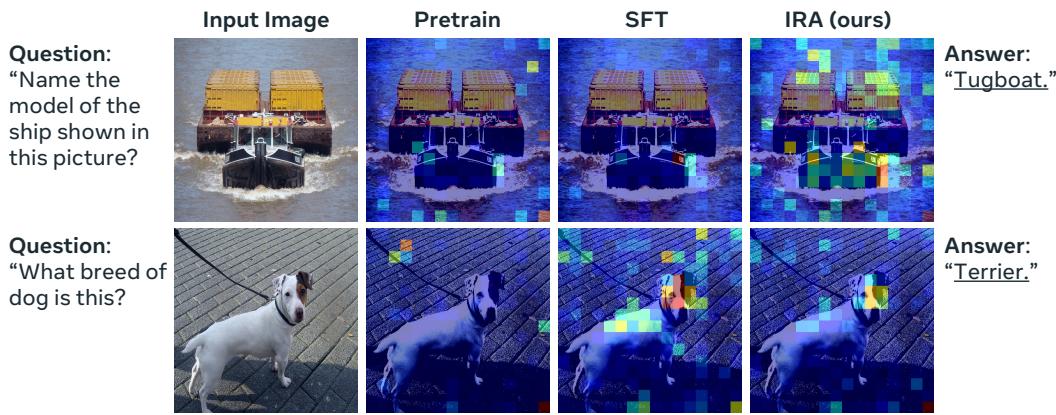
Figureure 2 · Architecture of the proposed Information-Regularized Attention (IRA)Figure 2 Architecture of the proposed Information-Regularized Attention (IRA). We introduce a lightweight posterior sampler that incorporates stochastic representations prior to the attention computation.这张图概括 Information-Regularized Attention for Visual-Centric Reasoning 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 1 · Cross-attention of a VLMFigure 1 Cross-attention of a VLM. We look at the normalized attention, i.e., Attn(answer → visual tokens) of the last layer. The model indicates a bad visual dependency without visual instruction tuning. SFT improves alignment between visual cues and output text, but biased information is introduced due to unregularized visual embedding. IRA restricts biased knowledge and only encodes necessary information.这张可视化用来解释 Information-Regularized Attention for Visual-Centric Reasoning 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。