arXiv new; ViT spatial representation · P1 · 2026-07-02
Active Spatial Guidance:它和通用视觉自监督的关系在于:讨论 ViT 是否必须注入 positional mechanism,直接关系到自监督 backbone 的空间归纳偏置
中高相关;详见方法、贡献和实验边界。
Active Spatial Guidance: Eliminating Injected Positional Mechanisms in Vision Transformers arXiv new; ViT spatial representation 原文链接
编号2607.00580优先级P1类别arXiv new; ViT spatial representation会议arXiv new; ViT spatial representation方法讨论 ViT 是否必须注入 positional mechanism,直接关系到自监督 backbone 的空间归纳偏置来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:讨论 ViT 是否必须注入 positional mechanism,直接关系到自监督 backbone 的空间归纳偏置。 中高相关;详见方法、贡献和实验边界。
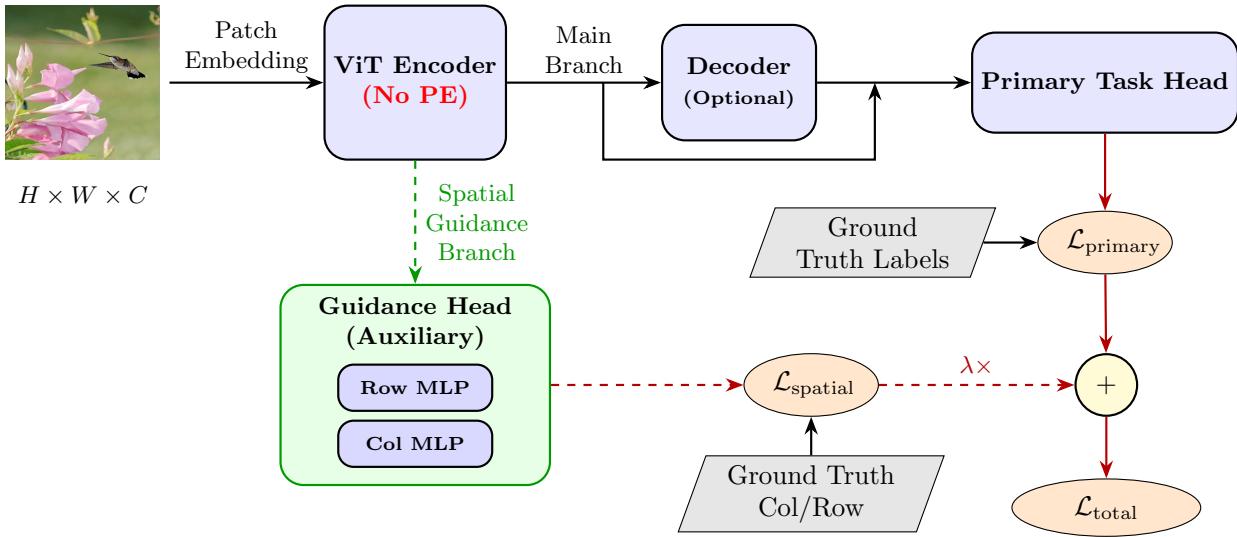
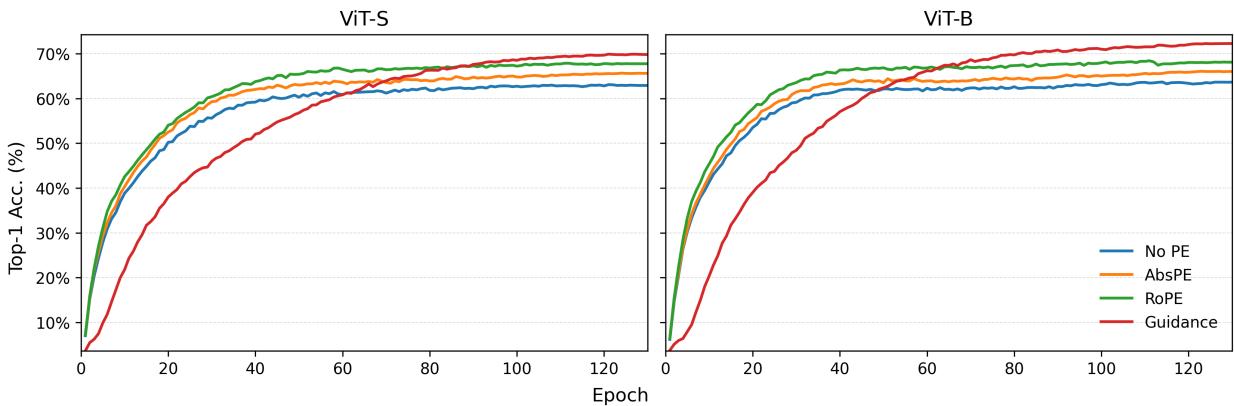
Figureure 2 · : Overview of Active Spatial GuidanceFigure 2: Overview of Active Spatial Guidance. The ViT encoder is trained with positional injection omitted (No-PE). During training, an auxiliary guidance head attached to the final-layer patch tokens regresses normalized 2D patch-grid coordinates and provides additional spatial supervision, which is combined with the primary task loss via a scalar weight ??. The auxiliary branch is discarded after training; inference uses only the PE-free encoder and the primary task head (and an optional decoder for dense prediction).这张图概括 Active Spatial Guidance 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 1 · : Training dynamics on ImageNet-100 with DINOv3 ViT-S and ViT-B traineFigure 1: Training dynamics on ImageNet-100 with DINOv3 ViT-S and ViT-B trained from scratch for 130 epochs at 224 × 224. Curves show validation Top-1 accuracy for a PE-free baseline (No-PE ), learned absolute positional embeddings (AbsPE ), rotary embeddings (RoPE ), and Active Spatial Guidance (Guidance). All settings share the same optimization and augmentation protocol; only the positional strategy difers.这张图/表用于判断 Active Spatial Guidance 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:讨论 ViT 是否必须注入 positional mechanism,直接关系到自监督 backbone 的空间归纳偏置。
方法拆解
讨论 ViT 是否必须注入 positional mechanism,直接关系到自监督 backbone 的空间归纳偏置