arXiv new; ACM MM 2025; video representation for RL pretraining · P2 · 2026-07-02
From Pixels to Temporal Correlations:它和通用视觉自监督的关系在于:从 action-free internet videos 学表示,虽然落点是 RL,但核心是视频自监督如何避免只保留静态像素
中相关;详见方法、贡献和实验边界。
From Pixels to Temporal Correlations: Learning Informative Representations for Reinforcement Learning Pre-training arXiv new; ACM MM 2025; video representation for RL pretraining 原文链接
编号2607.00811优先级P2类别arXiv new; ACM MM 2025; video representation for RL pretraining会议arXiv new; ACM MM 2025; video representation for RL pretraining方法从 action-free internet videos 学表示,虽然落点是 RL,但核心是视频自监督如何避免只保留静态像素来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:从 action-free internet videos 学表示,虽然落点是 RL,但核心是视频自监督如何避免只保留静态像素。 中相关;详见方法、贡献和实验边界。
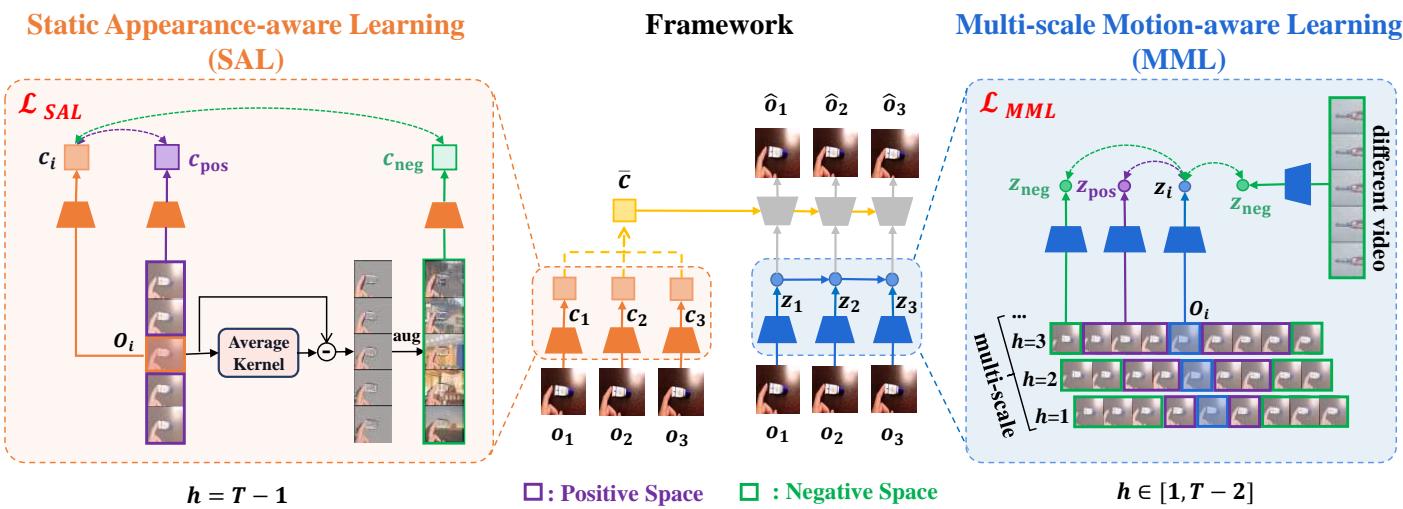
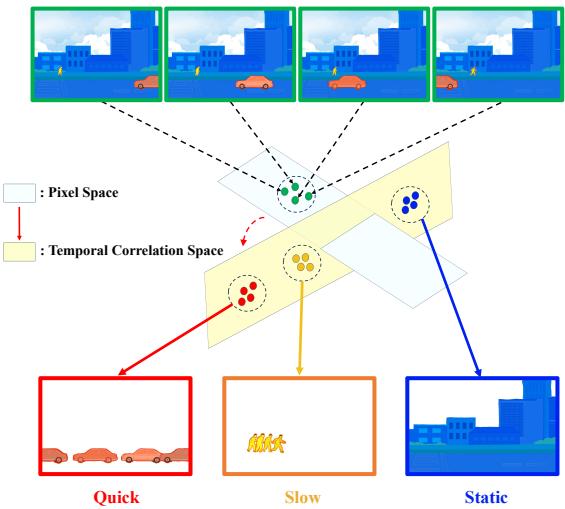
Figureure 2 · : Overview of our modelFigure 2: Overview of our model. Building on an action-free world model framework, we independently model multi-scale temporal correlations in videos. Our method is composed of Multi-scale Motion-aware Learning (MML) and Static Appearanceaware Learning (SAL). The MML objective is applied to the observation encoder and the SAL objective is applied to the context encoder. Average pooling is applied to the context variable <sup>??</sup> over the sequence dimension to enhance the decoder.这张图概括 From Pixels to Temporal Correlations 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 1 · : Illustration of our methodFigure 1: Illustration of our method. We convert videos from the pixel space to the temporal correlation space where elements are inherently separable. By equally attending to diferent elements, we learn more informative representations that efectively support various downstream tasks.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 From Pixels to Temporal Correlations 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:从 action-free internet videos 学表示,虽然落点是 RL,但核心是视频自监督如何避免只保留静态像素。
方法拆解
从 action-free internet videos 学表示,虽然落点是 RL,但核心是视频自监督如何避免只保留静态像素