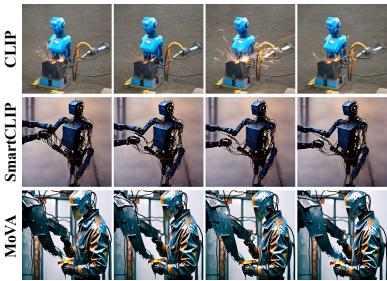
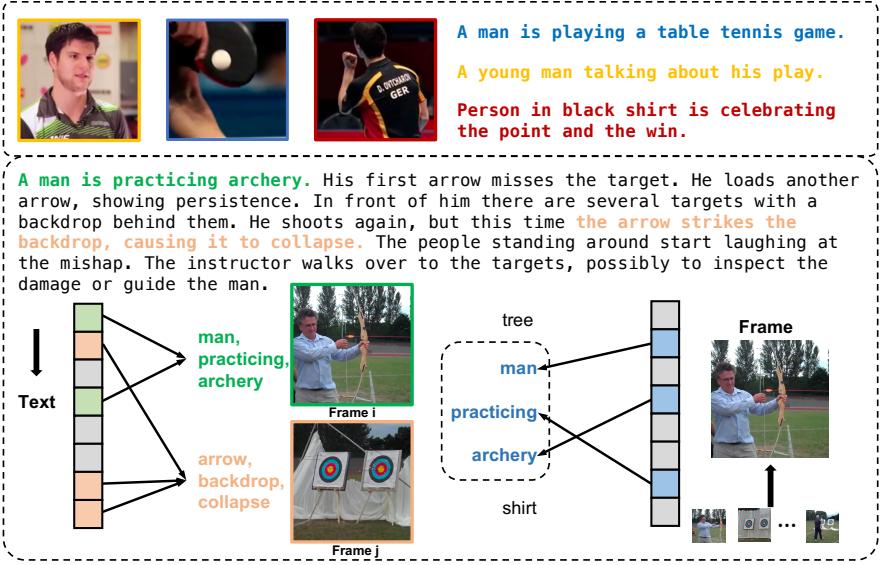
Figureure 8 · : Additional Comparison Examples of Long-text-to-video generationFig. 8: Additional Comparison Examples of Long-text-to-video generation. These examples further demonstrate MoVA’s capability in handling complex descriptive prompts. Top: The model accurately captures the stylized aesthetic, rendering the patchworked coat and the specific motion of swaying while singing. Bottom: MoVA successfully generates the fine-grained details of the rusted welding mask and the glowing material within an industrial atmosphere.这张图/表用于判断 MoVA 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 1 · : Illustration of two key challenges for video–language alignmentFig. 1: Illustration of two key challenges for video–language alignment. (1) Temporal Misalignment: Video captions are inherently temporally misaligned with the underlying visual content. Multiple paired captions emphasize diferent moments along the video timeline—the first frame focuses on the man talking, while the second centers on the table tennis game. A single caption may describe an action occurring within only a short temporal window, leaving other frames potentially text-irrelevant. (2) Semantic Asymmetry: Regardless of caption length, only a sparse subset of the caption is relevant to any given frame. Text induces selective relevance, influencing each frame’s attention toward diferent textual components, whereas each frame preserves richer yet underdetermined information toward the correlated text, forming an inherent bidirectional asymmetry between the two modalities.这张图/表用于判断 MoVA 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。