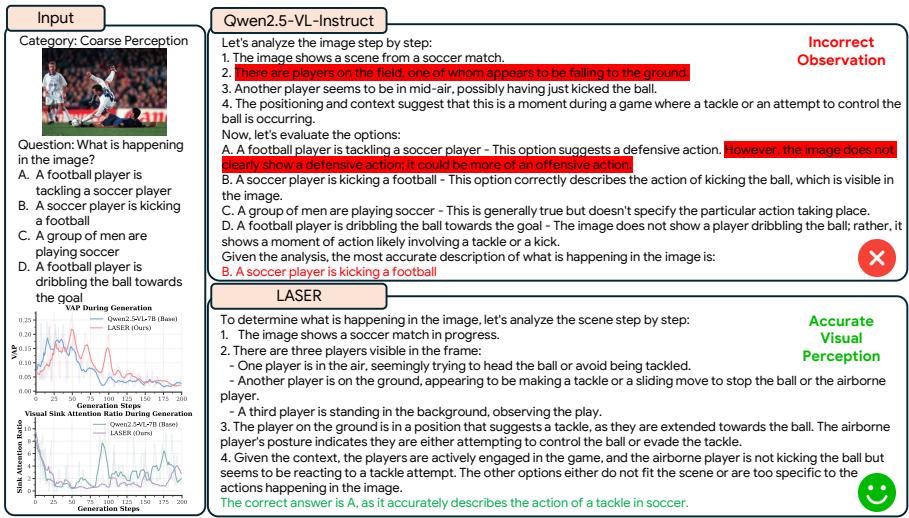
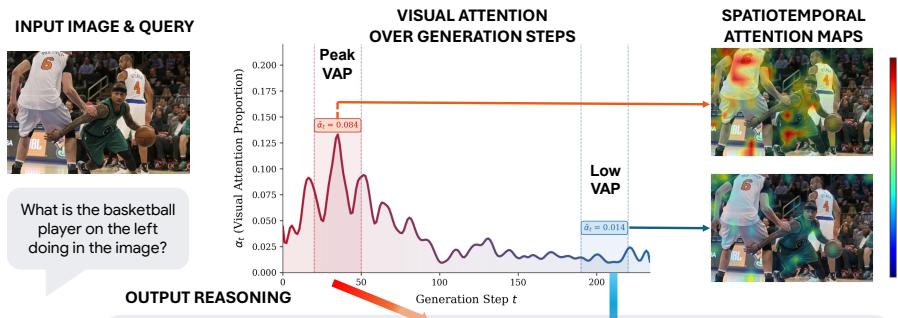
Figureure 8 · : A qualitative comparison between Qwen2.5-VL-Instruct and <sup>LASER<Fig. 8: A qualitative comparison between Qwen2.5-VL-Instruct and <sup>LASER</sup> on a visual perception task. Premature visual disengagement in the base model leads to an erroneous inference, while <sup>LASER</sup> maintains visual attention and answers correctly.这张图/表用于判断 LASER 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Let's analyze the image step by step: 1Let's analyze the image step by step: 1. The image shows two basketball players in action during a game. 2. The player on the left is wearing white and has jersey number 6. 4. The player in green is actively dribbling the basketball between his feet…… Therefore, based on the visual evidence, the most accurate description of what the basketball player on the left is doing is "Dribbling the ball." Fig. 1: Illustration of visual forgetting during long-horizon reasoning in LVLMs. Left: an input image and the corresponding question. Middle: the Visual Attention Proportion (VAP) over generation steps shows that attention to visual tokens peaks early and progressively decays during reasoning. Right: diference in attention maps reveals that later decoding stages could attend less to task relevant visual regions.这张可视化用来解释 LASER 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。