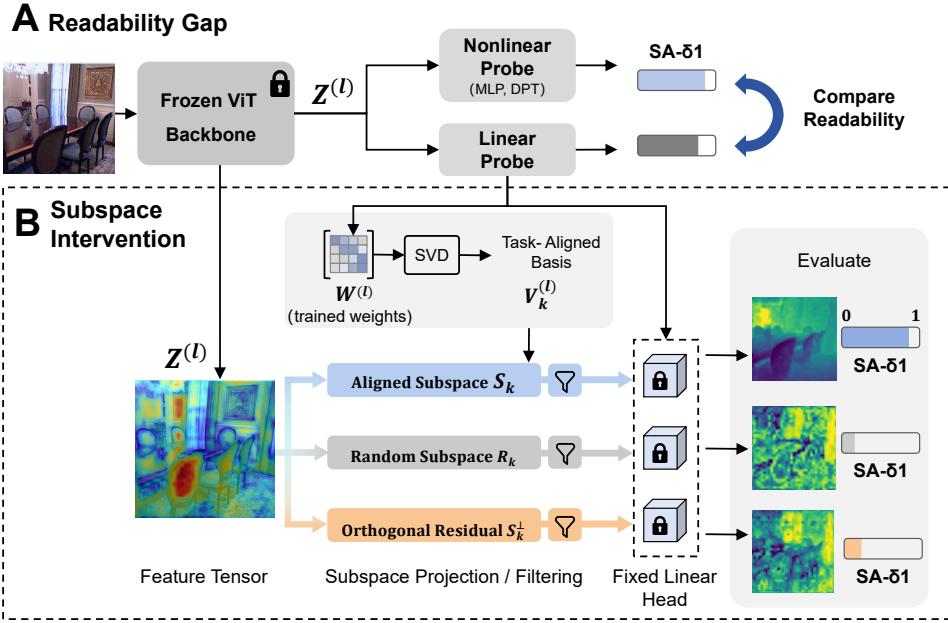
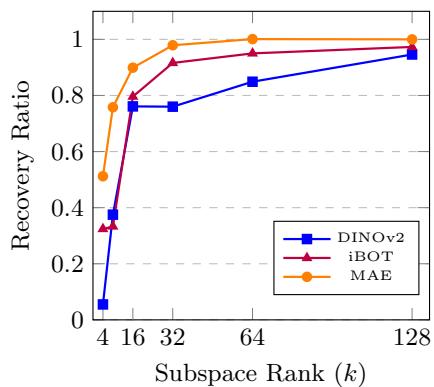
Figureure 1 · : Overview of the controlled subspace intervention analysis frameworkFig. 1: Overview of the controlled subspace intervention analysis framework. (A) We evaluate frozen backbone features Z using three-tier probes (Linear, MLP, and DPT) to decouple local non-linear entanglement from global spatial fragmentation, thereby obtaining the readability gap of geometric features. (B) Without additional training, we perform SVD on the converged linear weights W to extract a task-aligned basis ${ \bf V } _ { k } .$ . The feature tensor is then projected onto the aligned subspace $( S _ { k } )$ , a random subspace $\left( \mathcal { R } _ { k } \right)$ , and the orthogonal residual $( S _ { k } ^ { \perp } )$ . The projected features are evaluated through the fixed linear head to isolate the geometric signal.这张图概括 Understanding Geometric Representations in Self-Supervised 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。(b) Fig(b) Fig. 2: (a) Absolute Recovery: Solid colored lines depict the performance of the task-aligned subspace $( \mathbf { V } _ { k } \mathbf { V } _ { k } ^ { \top } )$ . The gray shaded area denotes the noise floor $( \mathrm { S A } – \delta _ { 1 } < 0 . 1 8 )$ , accounting for both the residual subspace and the random orthogonal baselines under the frozen probe. This gap indicates substantial representational redundancy, suggesting that explicitly decodable geometric information can be compressed into a low-rank subspace without significant loss. (b) Recovery Eficiency: Normalized against each model’s full-rank linear baseline, MAE (Orange) exhibits the fastest relative saturation, recovering > 98% of its linear potential by $k = 3 2$ . iBOT (Purple) tracks closely with MAE, while DINOv2 (Blue) shows slower convergence. This indicates that DINOv2 linearly encodes richer, fine-grained geometric details that require slightly more dimensions to fully resolve.这张图/表用于判断 Understanding Geometric Representations in Self-Supervised 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:用子空间干预解释 DINOv2、MAE 等 SSL ViT 如何编码 dense geometry,直接服务 backbone/decoder 设计。
方法拆解
用子空间干预解释 DINOv2、MAE 等 SSL ViT 如何编码 dense geometry,直接服务 backbone/decoder 设计