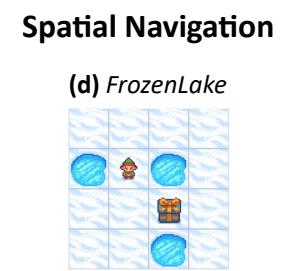
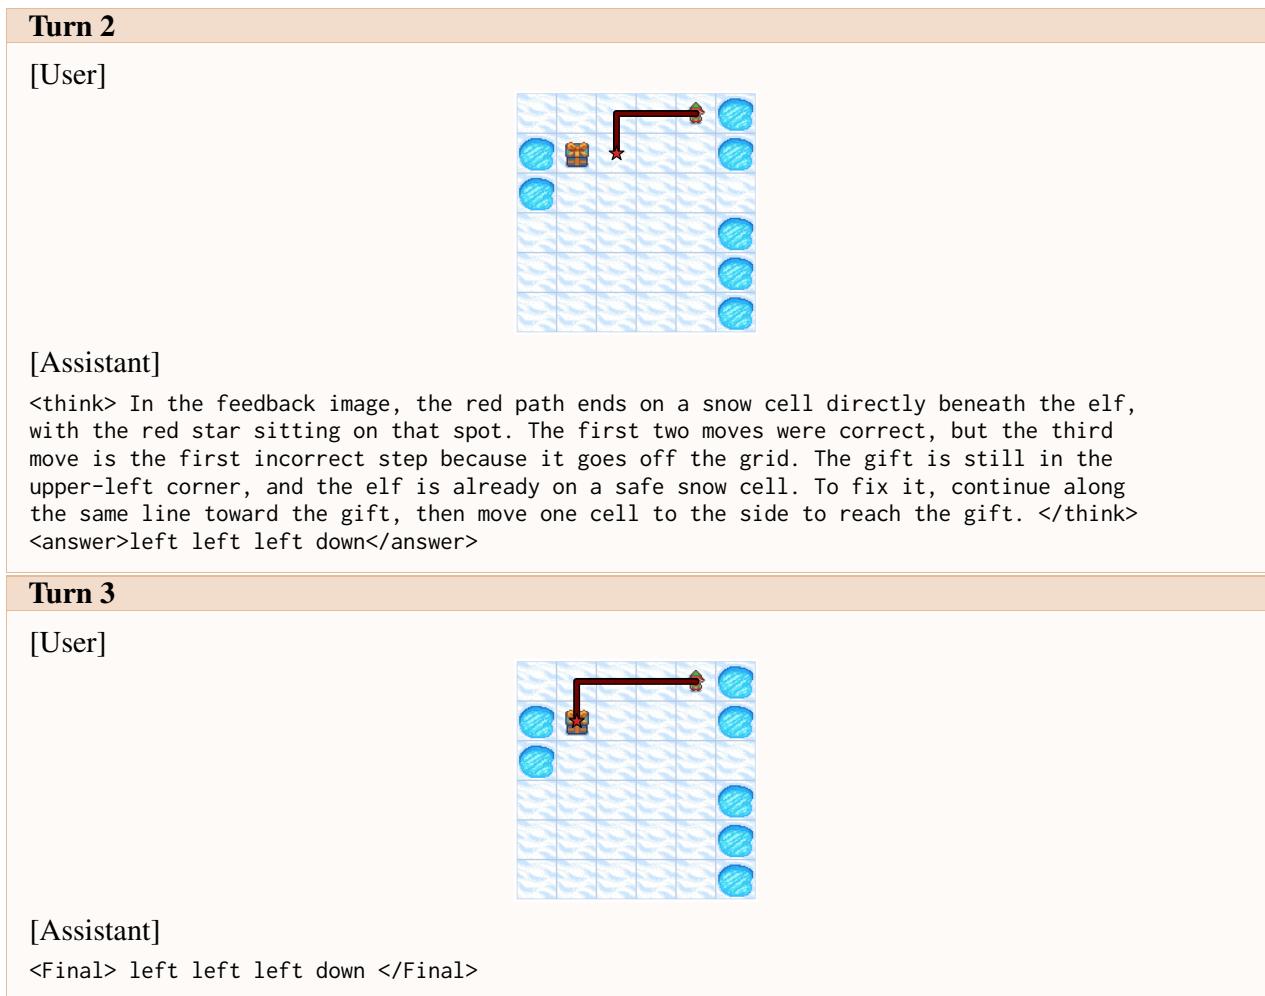
Q: Find the shortest path from the sprite to the chest without falling into holesQ: Find the shortest path from the sprite to the chest without falling into holes. Figure 3: Evaluation tasks for visually grounded self-reflection. (1) Visual Grounding. models are trained to localize headers of synthetic small tables. OOD tasks include generalization to larger tables (Large Table) queries of inner cell values rather than headers (Cell Query), and queries about bar charts (b), and scatter plots (c). (2) Spatial Navigation. The model is given a maze-style map and needs to find the shortest path from the start to the goal without running into obstacles. We train models on smaller maps and evaluate on larger maps as OOD tests.这张图/表用于判断 Visually Grounded Self-Reflection for Vision-Language 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 11 · : Figure 10 continuation.Figure 11: Figure 10 continuation.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Visually Grounded Self-Reflection for Vision-Language 的方法或实验,请结合正文精读段落一起看。