通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-07-04 图像表征 · VFM · JEPA · 视频预训练
arXiv new/cross; ECCV 2026; CLIP mechanistic interpretability · P1 · 2026-07-04

Towards Robustness against Typographic Attack:它和通用视觉自监督的关系在于:定位 CLIP/LVLM 视觉编码器被图中文字劫持的注意力/电路机制,对通用视觉-语言表征可靠性重要

中高相关;详见方法、贡献和实验边界。

编号2607.02494 优先级P1 类别arXiv new/cross; ECCV 2026; CLIP mechanistic interpretability 会议arXiv new/cross; ECCV 2026; CLIP mechanistic interpretability 方法定位 CLIP/LVLM 视觉编码器被图中文字劫持的注意力/电路机制,对通用视觉-语言表征可靠性重要 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:定位 CLIP/LVLM 视觉编码器被图中文字劫持的注意力/电路机制,对通用视觉-语言表征可靠性重要。 中高相关;详见方法、贡献和实验边界。

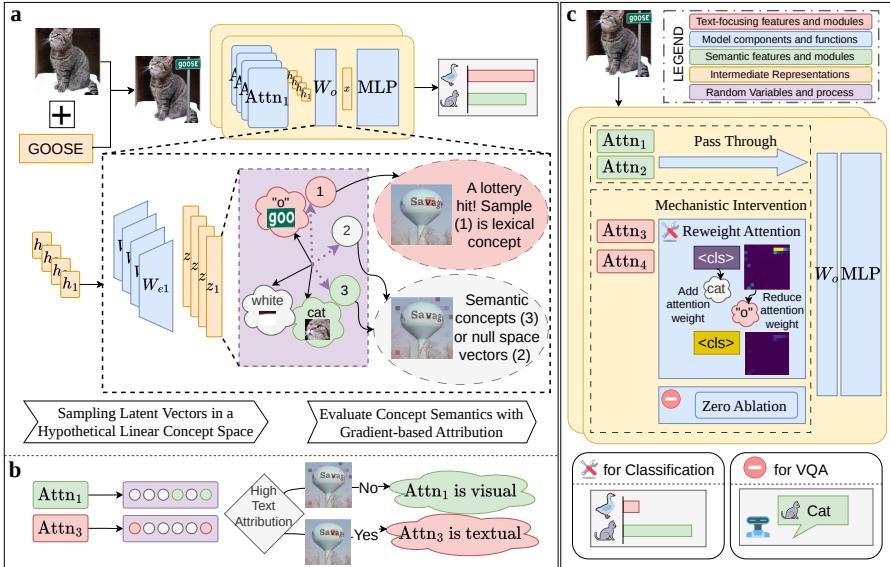
Figureure 1 · : An overview of the proposed method
Figureure 1 · : An overview of the proposed methodFig. 1: An overview of the proposed method. a) shows the sampling-based mechanistic interpretability (the Stochastic Lottery) for lexical circuit mining. Latent samples (denoted by purple dashed arrows) on the hypothesized concept basis reveal distinct attribution patterns. b) illustrates the overall sampling and circuit-mining process using gradient-based attribution. c) shows the mechanistic intervention process. To improve TA robustness, we intervene in vulnerable attention modules via attention reweighting or zero-ablation.这张图概括 Towards Robustness against Typographic Attack 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
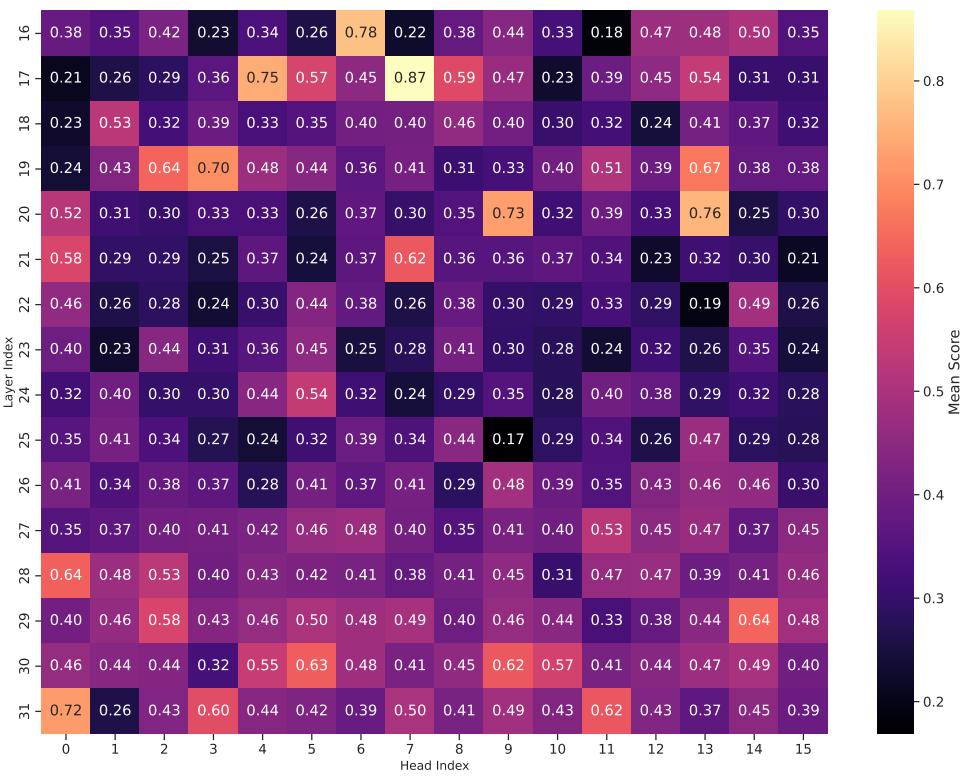
Figureure 8 · : Mean nTAS of Attention Heads across ViT layers.
Figureure 8 · : Mean nTAS of Attention Heads across ViT layers.Fig. 8: Mean nTAS of Attention Heads across ViT layers.这张可视化用来解释 Towards Robustness against Typographic Attack 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。
核心问题

它和通用视觉自监督的关系在于:定位 CLIP/LVLM 视觉编码器被图中文字劫持的注意力/电路机制,对通用视觉-语言表征可靠性重要。

方法拆解

定位 CLIP/LVLM 视觉编码器被图中文字劫持的注意力/电路机制,对通用视觉-语言表征可靠性重要

主要贡献

中高相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。