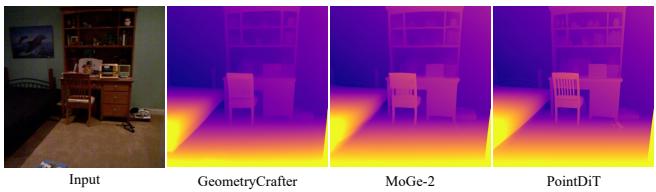
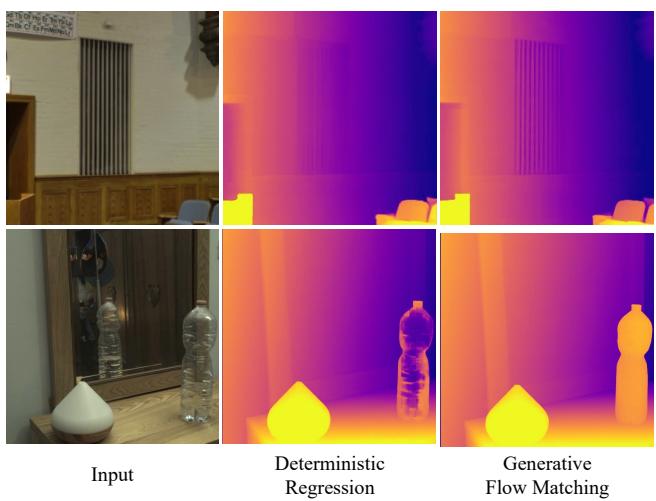
(a) Point VAE reconstruction(a) Point VAE reconstruction. Even without diffusion, the VAEreconstructed point cloud exhibits substantial noise, which fundamentally limits the quality attainable by latent diffusion models. (b) Structural details. PointDiT recovers intricate, thin structures such as the chair more faithfully than GeometryCrafter (latent diffusion) and MoGe-2 (deterministic regression). Here we visualize the z-depth from the predicted 3D point maps. Figure 2. Comparison with latent diffusion and regression. The two dominant paradigms each have an inherent limitation: (a) the VAE in latent diffusion models introduces reconstruction noise that caps the attainable quality, while (b) deterministic regression over-smooths fine geometric structures. PointDiT avoids both.这张图/表用于判断 PointDiT 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。(b) Structural details and transparent objects(b) Structural details and transparent objects. Figure 5. Generative flow matching vs. deterministic regression. (a) The deterministic regressor converges faster at first but soon overfits, while the generative model trains stably and reaches lower error. (b) The generative model recovers sharper boundaries, thin structures, and transparent objects than the deterministic regressor. Overall, the generative formulation improves the boundary metric BF1 from 10.90 to 13.92 under this controlled comparison.这张图/表用于判断 PointDiT 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。