VLRC:它和通用视觉自监督的关系在于:用 frozen vision-language representations 作为多视角一致性信号,为无 3D 标注的 feed-forward 3D 预训练提供可扩展监督
高相关;详见方法、贡献和实验边界。
VLRC: Vision-Language Reprojection Consistency as a scalable signal for better feed-forward 3D pretraining arXiv new; V-L feature reprojection; 3D pretraining 原文链接
编号2607.02707优先级P1类别arXiv new; V-L feature reprojection; 3D pretraining会议arXiv new; V-L feature reprojection; 3D pretraining方法用 frozen vision-language representations 作为多视角一致性信号,为无 3D 标注的 feed-forward 3D 预训练提供可扩展监督来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:用 frozen vision-language representations 作为多视角一致性信号,为无 3D 标注的 feed-forward 3D 预训练提供可扩展监督。 高相关;详见方法、贡献和实验边界。
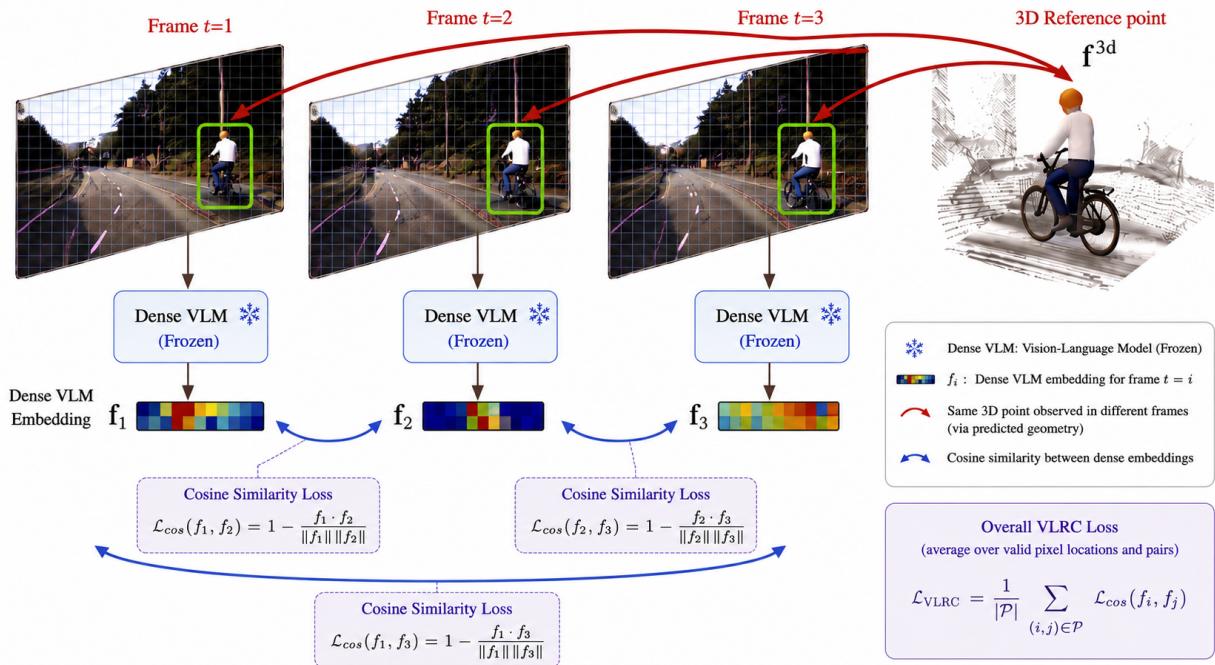
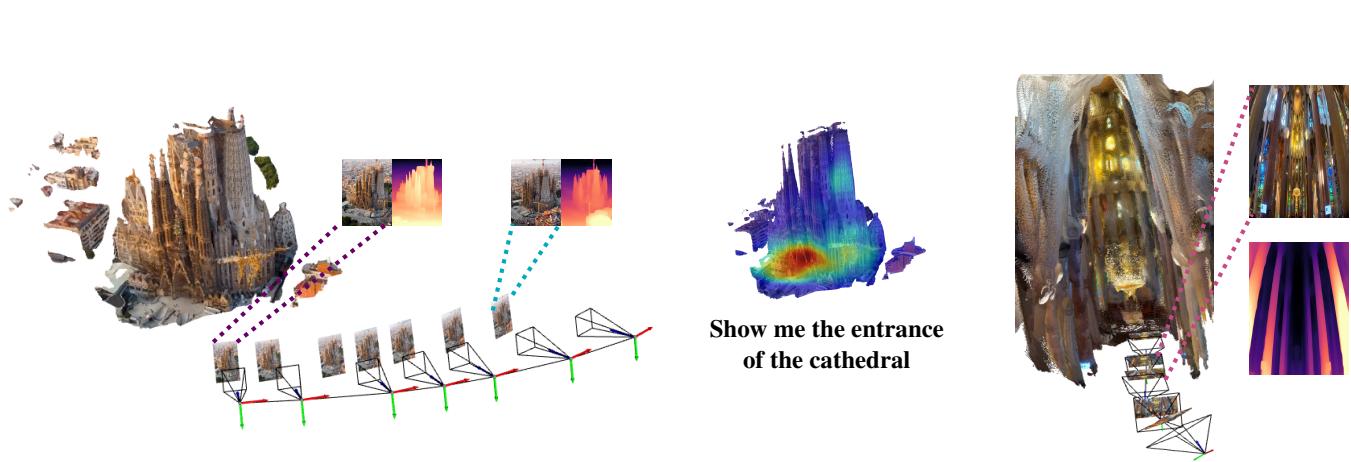
Figureure 2 · Reprojection of a point $p \in \mathbb { R } ^ { 3 } \colon$ : the heaFigure 2. Reprojection of a point $p \in \mathbb { R } ^ { 3 } \colon$ : the head of a cyclist - The 3d point centered on the head of the cyclist is reprojected on the successive frames and the corresponding Dense VLM features are extracted with a frozen encoder and compared across the reprojected correspondences using a cosine dissimilarity loss. VLRC encourages the predicted geometry to align multi-view language-grounded features consistently across views. P denotes the set of target-source frame pairs used for reprojection.这张可视化用来解释 VLRC 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。Figureure 1 · SS3D+VLRC trained on YouTube8M web videos reconstructs both the exteriFigure 1. SS3D+VLRC trained on YouTube8M web videos reconstructs both the exterior (left) and interior (right) of the Sagrada Familia from two casual videos: one recorded outside and one inside. It accurately localizes the entrance in 3D using the prompt (“Show me the entrance of the cathedral”). The reconstruction uses self-supervised estimates of depth, camera pose, and intrinsics. Depth maps and camera trajectories are visualized, each camera being shown along with its corresponding viewpoint. Point clouds are rendered with Open3D.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 VLRC 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:用 frozen vision-language representations 作为多视角一致性信号,为无 3D 标注的 feed-forward 3D 预训练提供可扩展监督。
方法拆解
用 frozen vision-language representations 作为多视角一致性信号,为无 3D 标注的 feed-forward 3D 预训练提供可扩展监督