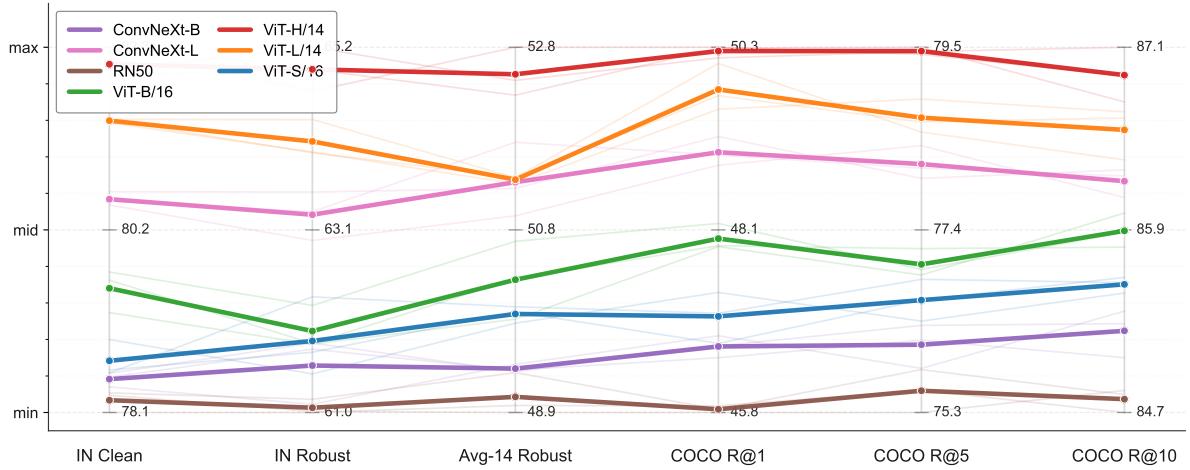
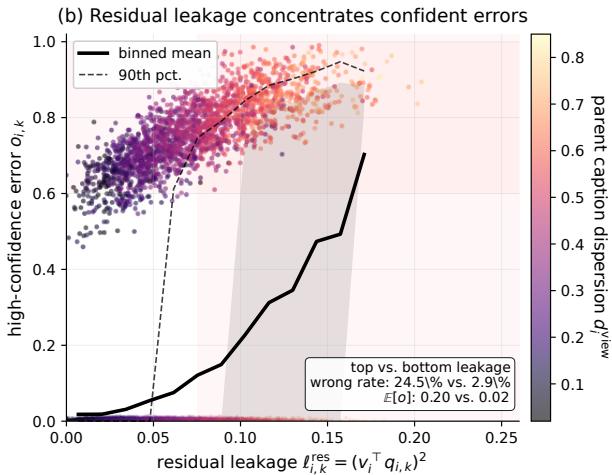
Figureure 9 · : Gain vsFigure 9: Gain vs. text-only solvability. Each point is an equal-count bin (hundreds of bins per dataset); colors indicate datasets. The trend line is a smoothed running mean over bins (same color per dataset) and an overall trend (black). Higher gain at lower solvability indicates TPC is most beneficial when text is a weak/underspecified constraint. Figure 10: Cross-backbone robustness and retrieval. Parallel coordinates over multiple metrics (each axis is min-max normalized for readability). Each backbone is shown with three seed runs (faint) and the mean (bold). Consistent trends across architectures indicate TPC does not rely on a particular backbone family.这张图概括 Text as Partial Constraint 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · : Frozen VLM failure under partial captionsFigure 2: Frozen VLM failure under partial captions. Left: larger caption-view dispersion leads to higher rank volatility and stronger hard-negative confusion. Right: residual leakage concentrates confident retrieval errors. All statistics are computed with frozen embeddings; no proposed module or training loss is used.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Text as Partial Constraint 的方法或实验,请结合正文精读段落一起看。