通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-07-08 图像表征 · VFM · JEPA · 视频预训练
arXiv new/cross; VLM mechanistic analysis · P2 · 2026-07-08

Pathways of Visual Information Flow:它和通用视觉自监督的关系在于:通过 causal patching 区分 direct visual pathway 与 text-mediated pathway,有助于判断 VLM 是否真正读出视觉 token

中高相关;详见方法、贡献和实验边界。

编号2607.03358 优先级P2 类别arXiv new/cross; VLM mechanistic analysis 会议arXiv new/cross; VLM mechanistic analysis 方法通过 causal patching 区分 direct visual pathway 与 text-mediated pathway,有助于判断 VLM 是否真正读出视觉 token 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:通过 causal patching 区分 direct visual pathway 与 text-mediated pathway,有助于判断 VLM 是否真正读出视觉 token。 中高相关;详见方法、贡献和实验边界。

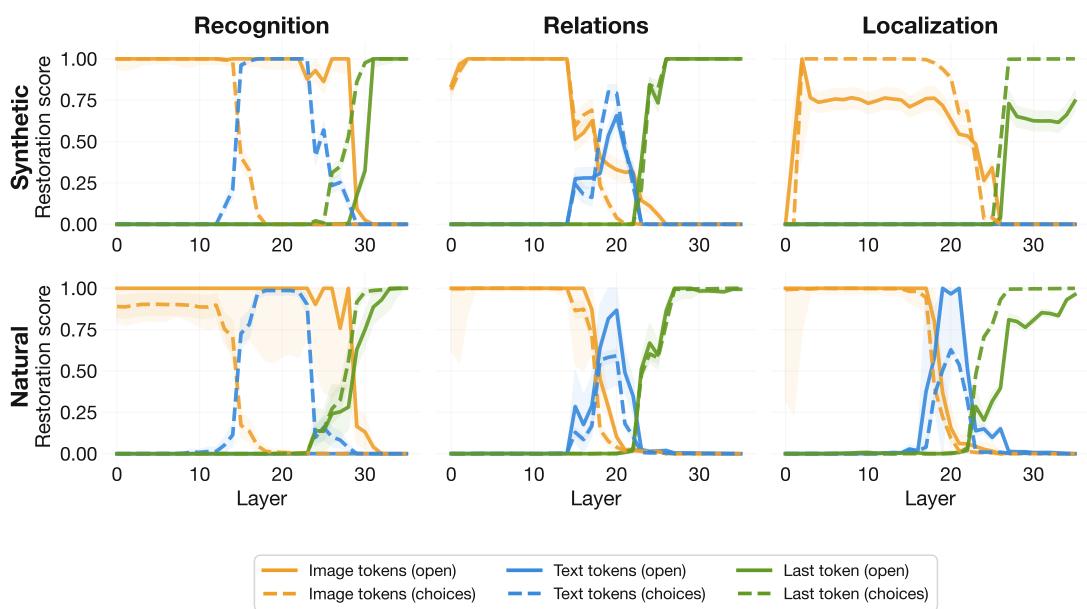
Figureure 14 · : Prompt-format modulation across tasks (Qwen3-VL-4B)
Figureure 14 · : Prompt-format modulation across tasks (Qwen3-VL-4B)Figure 14: Prompt-format modulation across tasks (Qwen3-VL-4B). Layer-wise restoration under the open (solid) and choices (dashed) protocols, organized by task and data domain. Recognition is the only task where prompt format flips the dominant pathway; for relations and localization, prompt format modulates the magnitude of restoration but does not change which pathway dominates.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Pathways of Visual Information Flow 的方法或实验,请结合正文精读段落一起看。
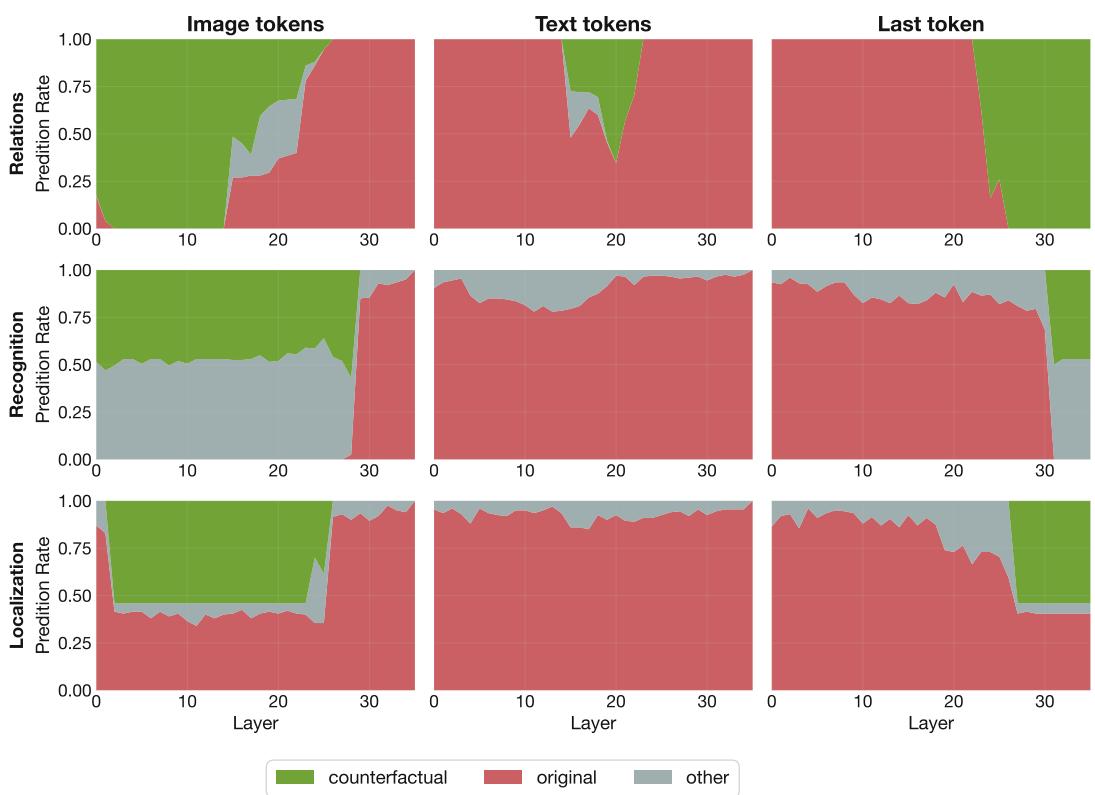
Figureure 12 · : Argmax outcomes under patching for open prompts
Figureure 12 · : Argmax outcomes under patching for open promptsFigure 12: Argmax outcomes under patching for open prompts. For each layer and patched group, we report the fraction of samples whose top-1 prediction matches the original answer $y_{x}$ , the counterfactual answer $y_{\tilde{x}}$ , or another token. In the open-generation setting, patched runs predominantly preserve either the original or counterfactual prediction, with a small fraction of out-of-vocabulary or paraphrased outputs.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Pathways of Visual Information Flow 的方法或实验,请结合正文精读段落一起看。
核心问题

它和通用视觉自监督的关系在于:通过 causal patching 区分 direct visual pathway 与 text-mediated pathway,有助于判断 VLM 是否真正读出视觉 token。

方法拆解

通过 causal patching 区分 direct visual pathway 与 text-mediated pathway,有助于判断 VLM 是否真正读出视觉 token

主要贡献

中高相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。