通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-07-09 图像表征 · VFM · JEPA · 视频预训练
arXiv new/cross; ICML 2026 Mechanistic Interpretability Workshop Spotlight; VLM localization analysis · P2 · 2026-07-09

Analysis-by-Proxy:它和通用视觉自监督的关系在于:诊断 VLM 作为 condition encoder 时空间信号是否真正被读出,有助于理解视觉表征在生成编辑管线中的丢失

中高相关;详见方法、贡献和实验边界。

编号2607.06445 优先级P2 类别arXiv new/cross; ICML 2026 Mechanistic Interpretability Workshop Spotlight; VLM localization analysis 会议arXiv new/cross; ICML 2026 Mechanistic Interpretability Workshop Spotlight; VLM localization analysis 方法诊断 VLM 作为 condition encoder 时空间信号是否真正被读出,有助于理解视觉表征在生成编辑管线中的丢失 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:诊断 VLM 作为 condition encoder 时空间信号是否真正被读出,有助于理解视觉表征在生成编辑管线中的丢失。 中高相关;详见方法、贡献和实验边界。

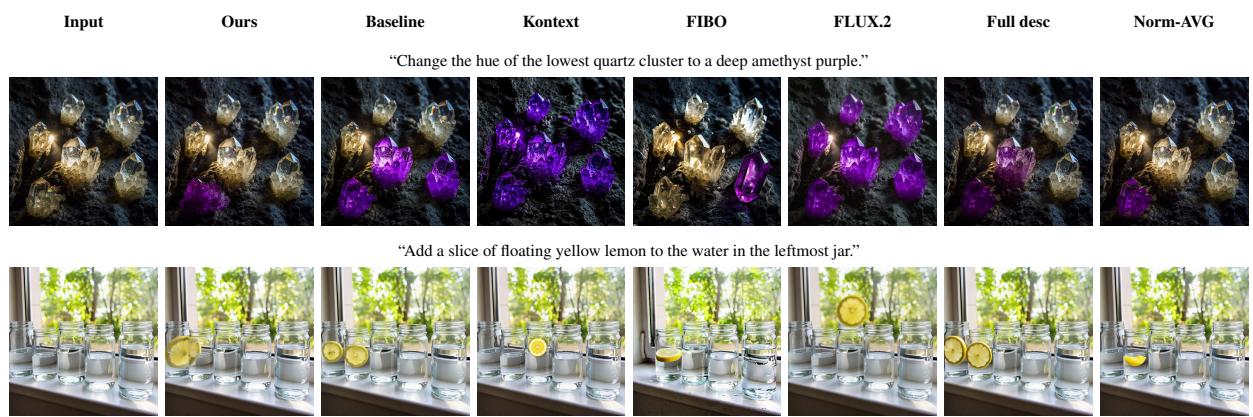
Figureure 8 · Qualitative comparison of image editing results
Figureure 8 · Qualitative comparison of image editing resultsFigure 8. Qualitative comparison of image editing results. While existing methods frequently modify incorrect objects or apply changes broadly across the scene, our method successfully localizes the edit to the intended target. This demonstrates that providing explicit spatial conditioning enables more precise and reliable edit localization. Additional qualitative comparisons are provided in Figure 11.这张图/表用于判断 Analysis-by-Proxy 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
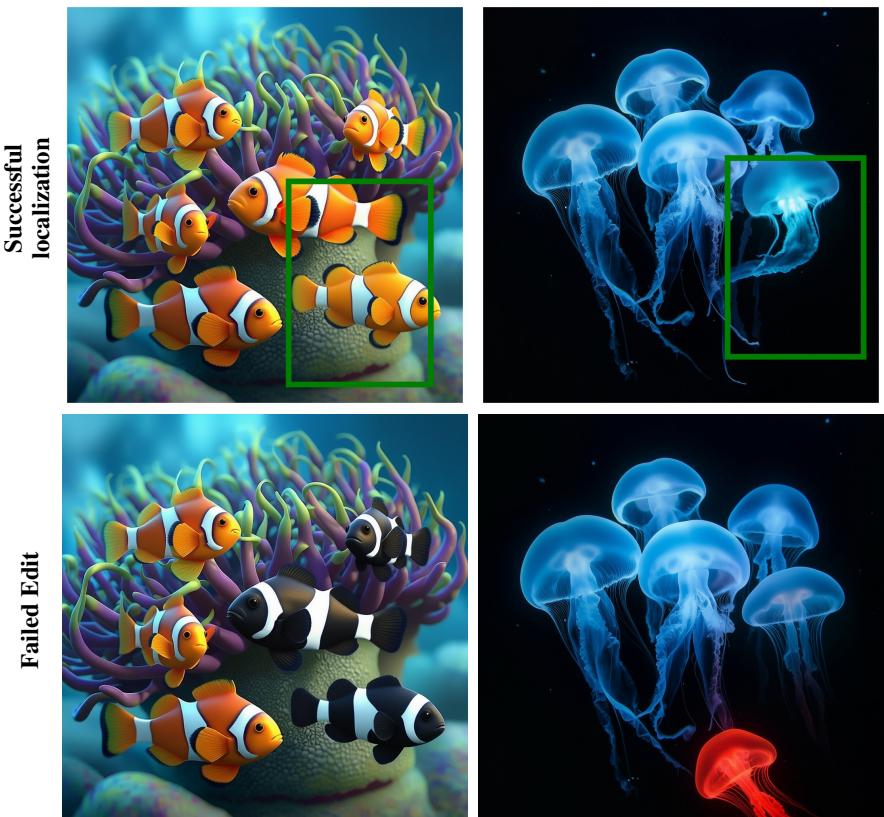
“Recolour the bottom right clownfish to be black and white” “Make the bottom jellyfish glo
“Recolour the bottom right clownfish to be black and white” “Make the bottom jellyfish glo“Recolour the bottom right clownfish to be black and white” “Make the bottom jellyfish glow red” Figure 10. Green: the explicit bounding box prediction generated by the trained Q-Former proxy, which isolates the target region to guide the downstream localized edit. The bottom row shows the corresponding failures of the original Qwen-Image-Edit pipeline on the same inputs.这张图概括 Analysis-by-Proxy 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
核心问题

它和通用视觉自监督的关系在于:诊断 VLM 作为 condition encoder 时空间信号是否真正被读出,有助于理解视觉表征在生成编辑管线中的丢失。

方法拆解

诊断 VLM 作为 condition encoder 时空间信号是否真正被读出,有助于理解视觉表征在生成编辑管线中的丢失

主要贡献

中高相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。