arXiv new; unified multimodal vision foundation model · P1 · 2026-07-09
Vision as Unified Multimodal Generation:它和通用视觉自监督的关系在于:把多种视觉任务统一成文本/图像生成接口,展示通用 VFM 可以不靠专用 head 覆盖 dense 与 symbolic tasks
中高相关;详见方法、贡献和实验边界。
Vision as Unified Multimodal Generation arXiv new; unified multimodal vision foundation model 原文链接
编号2607.06560优先级P1类别arXiv new; unified multimodal vision foundation model会议arXiv new; unified multimodal vision foundation model方法把多种视觉任务统一成文本/图像生成接口,展示通用 VFM 可以不靠专用 head 覆盖 dense 与 symbolic tasks来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:把多种视觉任务统一成文本/图像生成接口,展示通用 VFM 可以不靠专用 head 覆盖 dense 与 symbolic tasks。 中高相关;详见方法、贡献和实验边界。
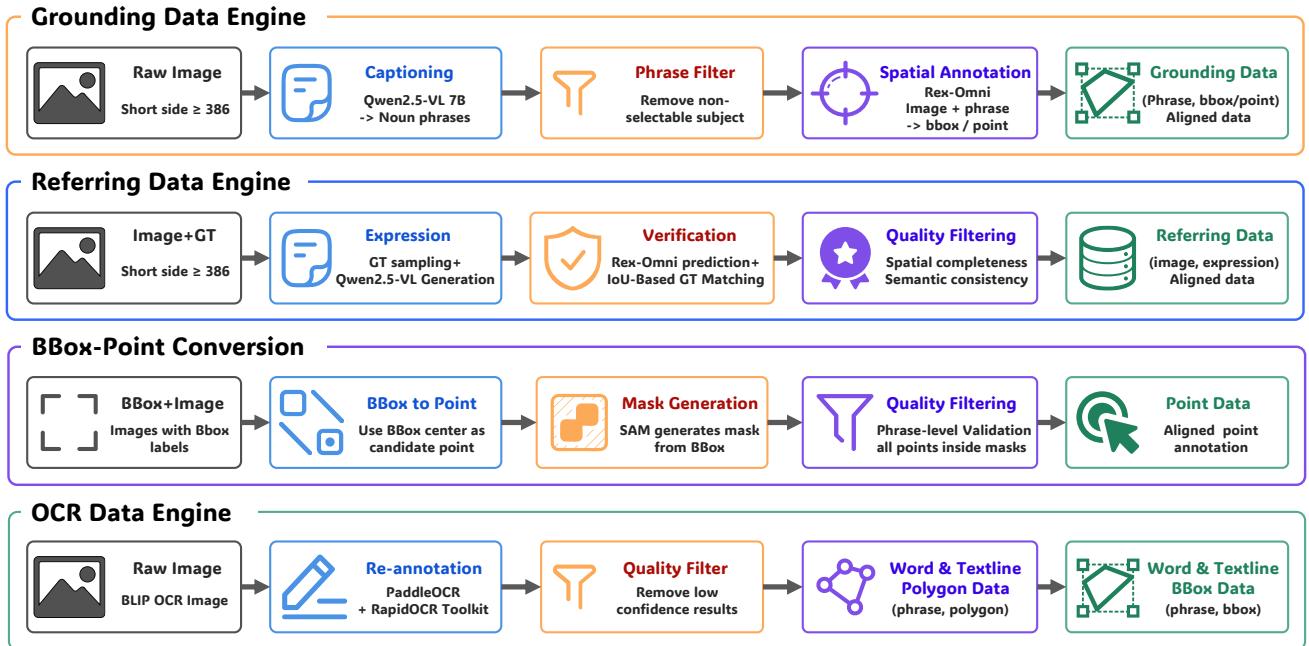
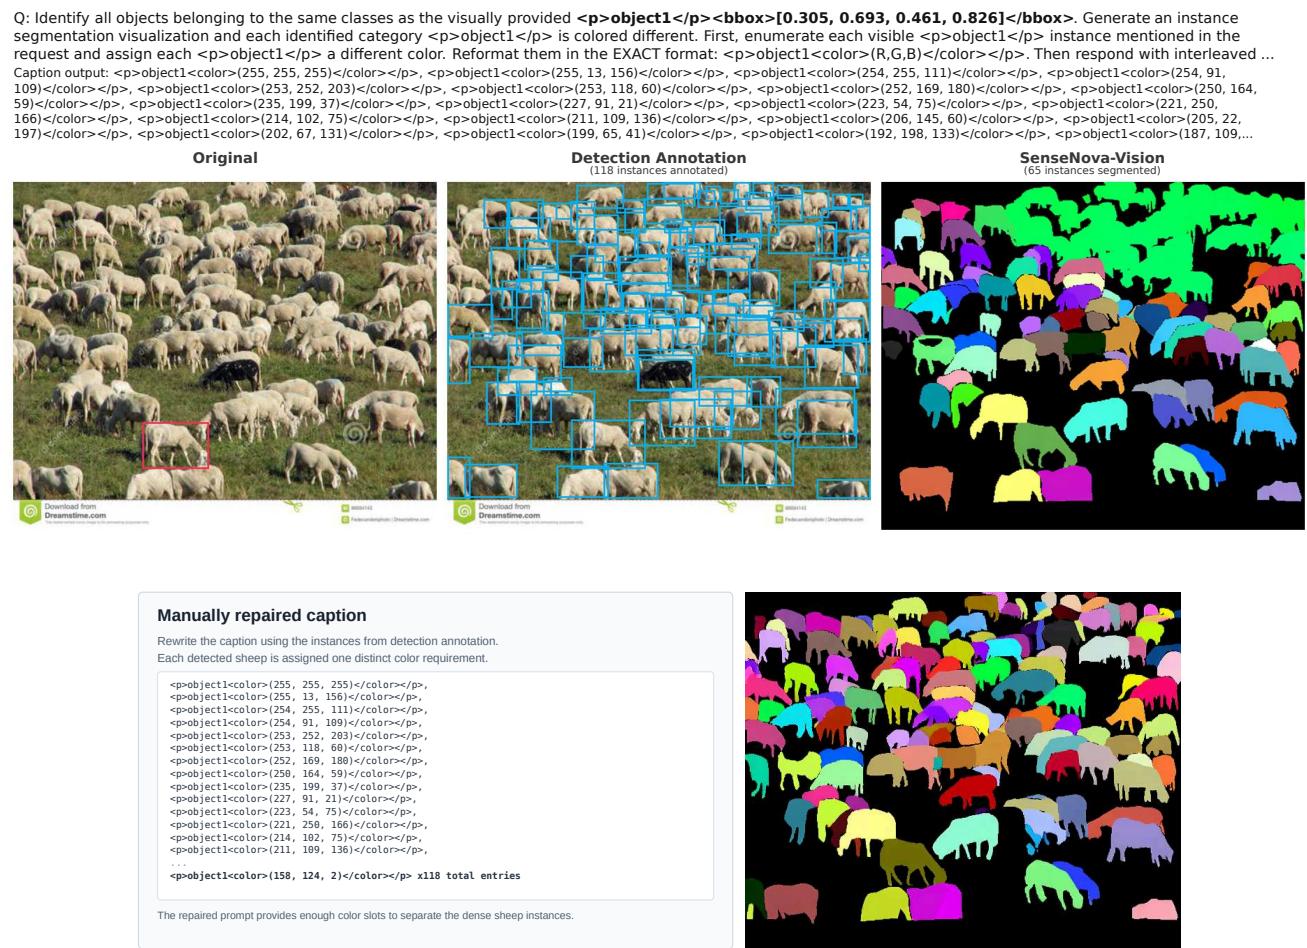
Figureure 13 · Overview of the proposed data construction pipelines, including the grFigure 13 Overview of the proposed data construction pipelines, including the grounding data engine, referring grounding data engine, BBox-to-Point data conversion and OCR data engine for generating large-scale, high-quality spatial annotations.这张图概括 Vision as Unified Multimodal Generation 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 21 · Qualitative results of Visual Grounded (VGD) segmentationFigure 21 Qualitative results of Visual Grounded (VGD) segmentation. The visual prompt specifies the target category, and the model is expected to segment all same-category instances. When the generated caption provides too few instance color slots, dense objects may be merged in the mask output; manually repairing the caption with sufficient color entries improves instance-level separation.这张图/表用于判断 Vision as Unified Multimodal Generation 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:把多种视觉任务统一成文本/图像生成接口,展示通用 VFM 可以不靠专用 head 覆盖 dense 与 symbolic tasks。
方法拆解
把多种视觉任务统一成文本/图像生成接口,展示通用 VFM 可以不靠专用 head 覆盖 dense 与 symbolic tasks