arXiv new/cross; 3D foundation model; cross-modal semantic anchoring · P2 · 2026-07-09
ELSA3D:它和通用视觉自监督的关系在于:通过 scale-aware 3D tokenizer 和 anchor tokens 组织文本-3D 对齐,适合作为 3D VFM/VLM 接口参考
中高相关;详见方法、贡献和实验边界。
ELSA3D: Elastic Semantic Anchoring for Unified 3D Understanding and Generation arXiv new/cross; 3D foundation model; cross-modal semantic anchoring 原文链接
编号2607.06565优先级P2类别arXiv new/cross; 3D foundation model; cross-modal semantic anchoring会议arXiv new/cross; 3D foundation model; cross-modal semantic anchoring方法通过 scale-aware 3D tokenizer 和 anchor tokens 组织文本-3D 对齐,适合作为 3D VFM/VLM 接口参考来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:通过 scale-aware 3D tokenizer 和 anchor tokens 组织文本-3D 对齐,适合作为 3D VFM/VLM 接口参考。 中高相关;详见方法、贡献和实验边界。
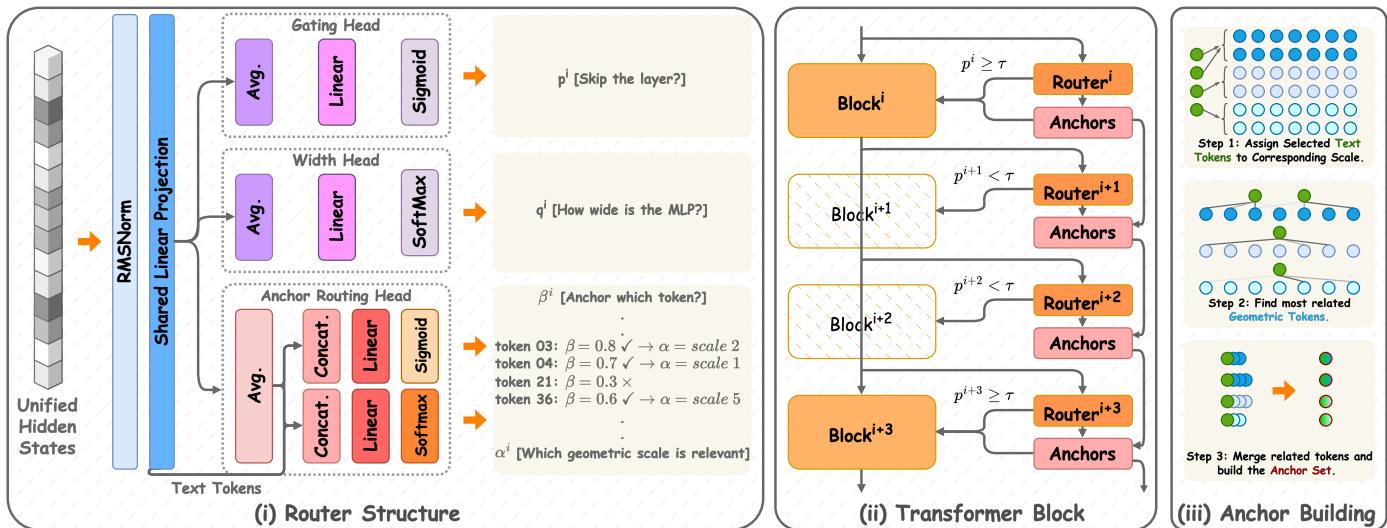
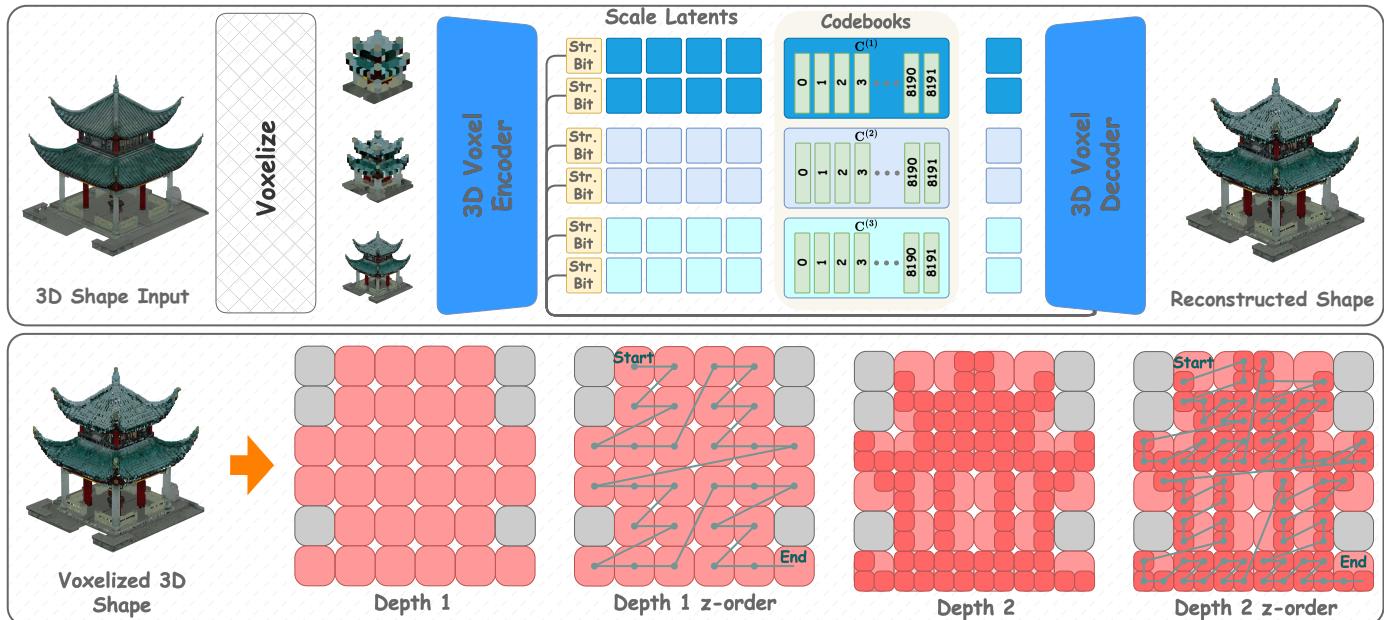
Figureure 1 · : ELSA3D overviewFigure 1: ELSA3D overview. ELSA3D is built around elastic semantic anchoring, where routing jointly controls computation and semantic–geometric grounding. (i) The router has three heads: a Gating Head $( \boldsymbol { p } ^ { i }$ skip or run), a Width Head $( \boldsymbol q ^ { i }$ , MLP width), and an Anchor Routing Head $( { \boldsymbol { \beta } } ^ { i } , { \boldsymbol { \alpha } } ^ { i }$ , which text tokens become anchors and at which scale). (ii) Blocks with $p ^ { i } \geq \tau$ execute at the selected width; others are skipped. (iii) Selected text tokens are routed to their preferred scale, cross-attended to the 3D tokens at that scale, and fused into the anchor set.这张图概括 ELSA3D 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · : Scale-aware octree tokenizationFigure 2: Scale-aware octree tokenization. Top: ELSA3D’s octree VQ-VAE encodes a voxelized 3D shape into multiscale structural bits and scale-specific content codes, then decodes them to reconstruct the shape. Bottom: nodes are organized by octree depth and serialized with Morton/Z-order to preserve spatial locality within each scale.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 ELSA3D 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:通过 scale-aware 3D tokenizer 和 anchor tokens 组织文本-3D 对齐,适合作为 3D VFM/VLM 接口参考。
方法拆解
通过 scale-aware 3D tokenizer 和 anchor tokens 组织文本-3D 对齐,适合作为 3D VFM/VLM 接口参考