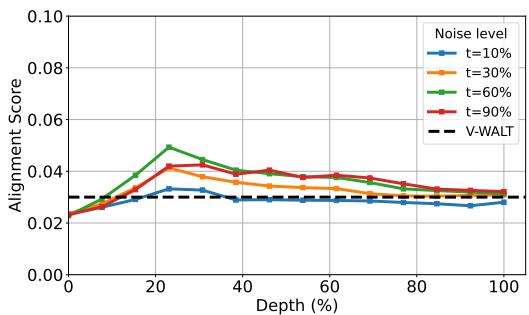
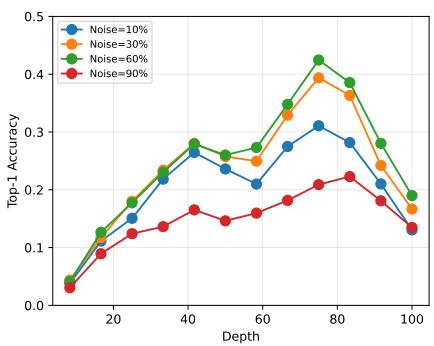
Figureure 3 · : Mutual-kNN zero-shot video-text alignment for Veo3 (left) and Wan 2.Figure 3: Mutual-kNN zero-shot video-text alignment for Veo3 (left) and Wan 2.2 (right) against Gemma-2-9b-it, compared to the best alignment obtained with V-WALT [Vélez et al., 2025] for reference. Note that as video generation models become more capable, their internal representations align more strongly with the underlying text captions (not provided to the models). See main text for a detailed discussion.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Gen4U 的方法或实验,请结合正文精读段落一起看。Figureure 4 · : Alignment between diffusion and discriminative representations usingFigure 4: Alignment between diffusion and discriminative representations using mutual k-NN metric. Remarkably, the intermediate activations of a strong model like Veo3 align not only with underlying semantics (captions) but also with the features of strong image and video models, suggesting their broad applicability.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Gen4U 的方法或实验,请结合正文精读段落一起看。