arXiv Thu batch; MoE video foundation pretraining · P1 · 2026-07-11
Scaling Mixture-of-Experts Video Pretraining for:它和通用视觉自监督的关系在于:虽然面向 embodied intelligence,但训练的是开源 MoE 视频基础模型,数据和架构对通用视频预训练有参考价值
中高相关;详见方法、贡献和实验边界。
Scaling Mixture-of-Experts Video Pretraining for Embodied Intelligence arXiv Thu batch; MoE video foundation pretraining 原文链接
编号2607.07675优先级P1类别arXiv Thu batch; MoE video foundation pretraining会议arXiv Thu batch; MoE video foundation pretraining方法虽然面向 embodied intelligence,但训练的是开源 MoE 视频基础模型,数据和架构对通用视频预训练有参考价值来源arXiv / OpenReview
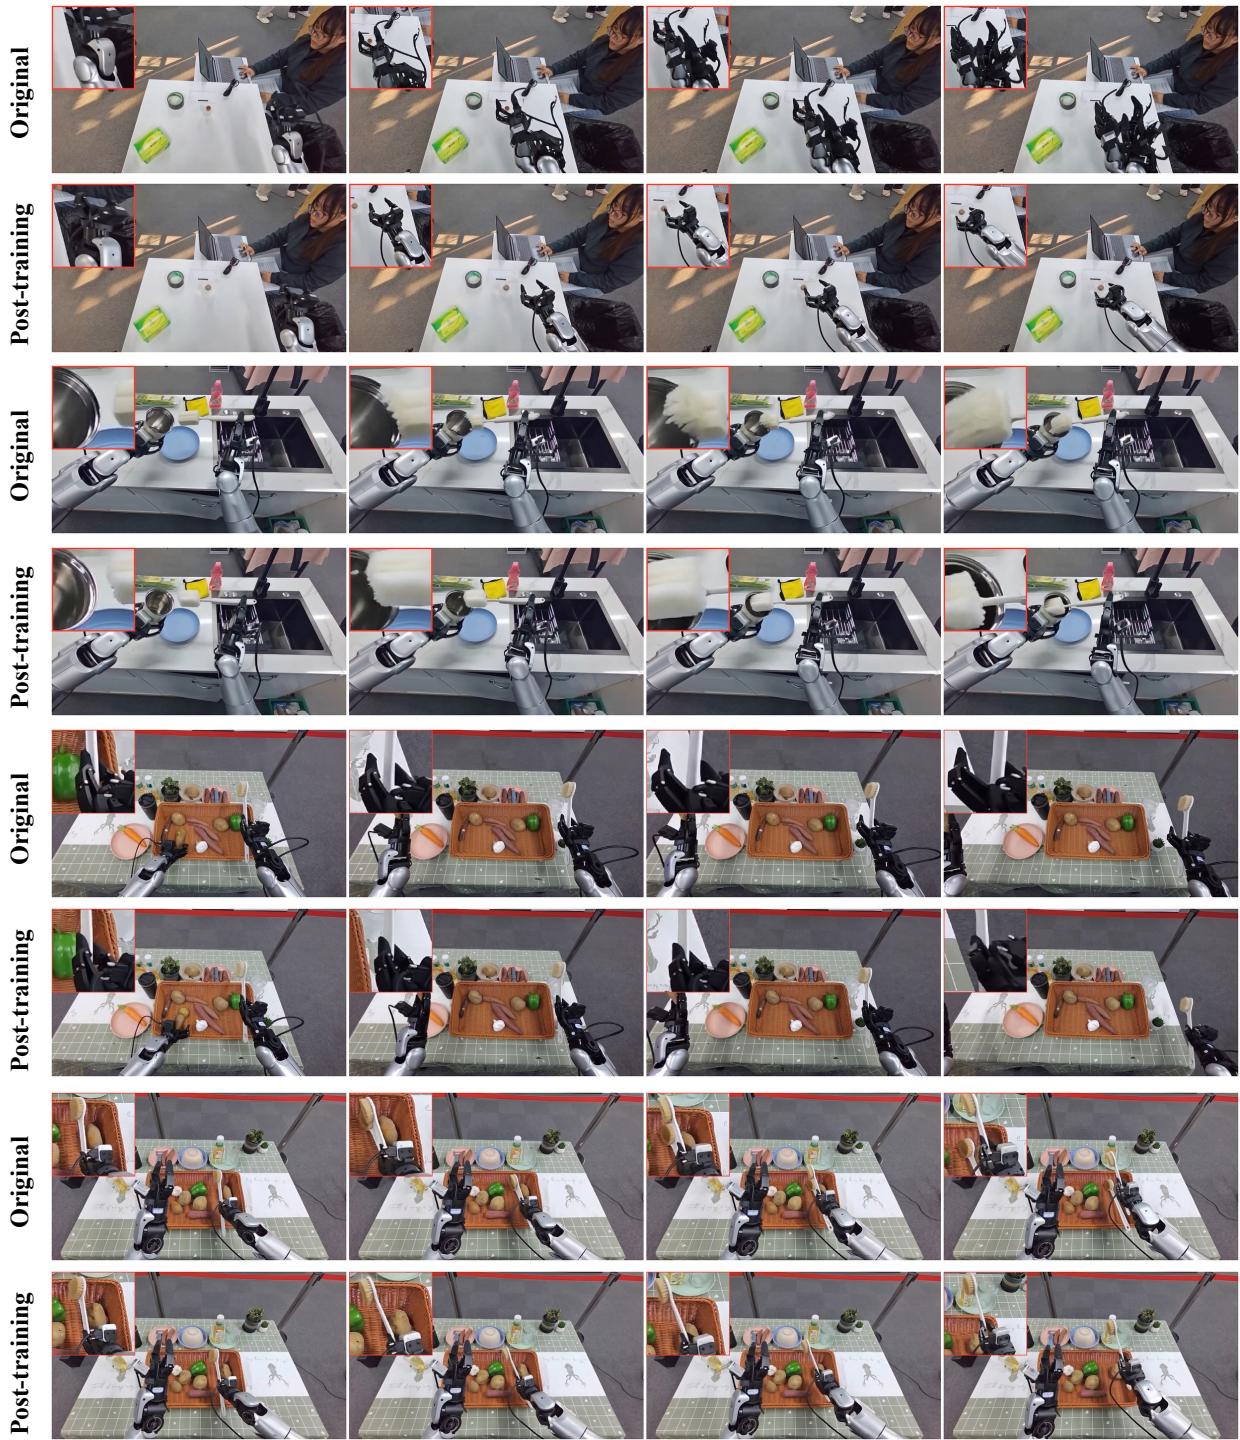
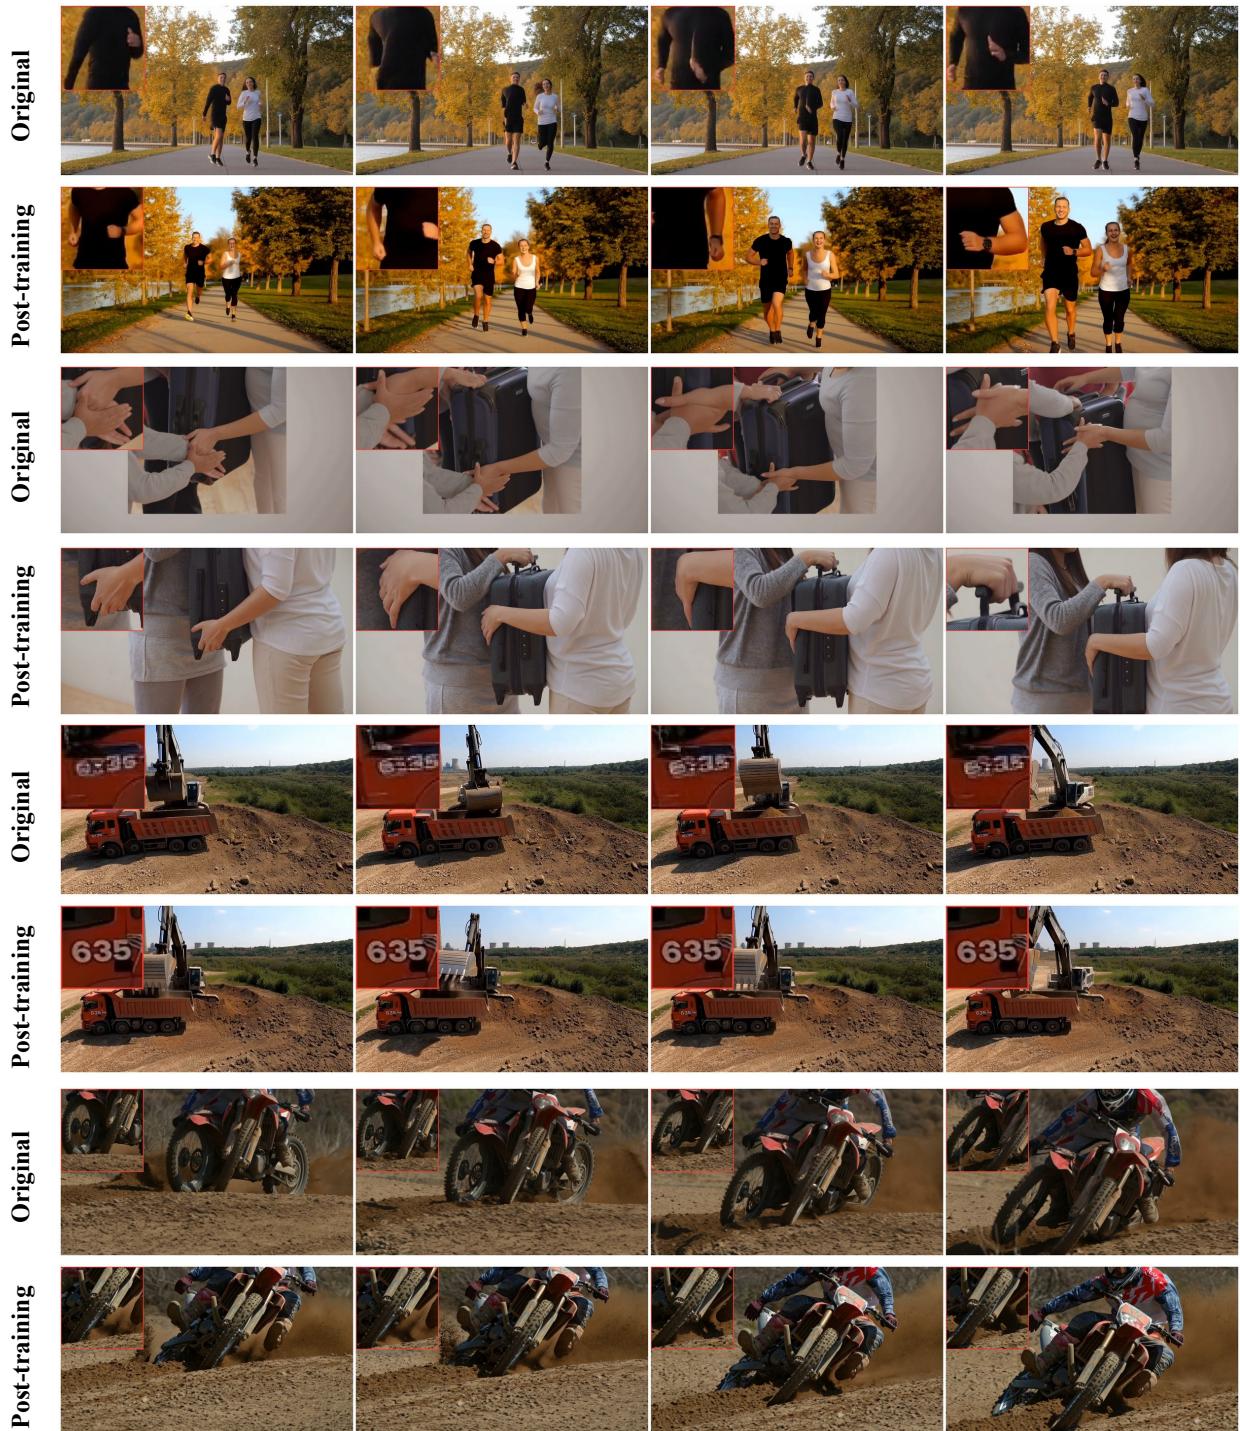
Figureure 13 · Qualitative comparison on embodied scenarios before and after post-traFigure 13. Qualitative comparison on embodied scenarios before and after post-training. The post-training phase significantly enhances physical plausibility by resolving baseline artifacts such as structural distortion of the arm and grasped objects, non-physical penetration, premature object release, and object duplication.这张图/表用于判断 Scaling Mixture-of-Experts Video Pretraining for 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figureure 12 · Qualitative comparison on general video quality before and after post-Figure 12. Qualitative comparison on general video quality before and after post-training, demonstrating marked improvements in several fundamental video generation domains. Post-training effectively resolves critical artifacts including inconsistent hand and limb synthesis, blurred or incorrect text rendering, and structural object deformation.这张图/表用于判断 Scaling Mixture-of-Experts Video Pretraining for 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。