通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-07-12 图像表征 · VFM · JEPA · 视频预训练
arXiv new; ECCV 2026; foundation-model distillation · P2 · 2026-07-12

ZipDepth:它和通用视觉自监督的关系在于:不是 SSL 主方法,但把大 VFM depth 能力蒸馏到 6.1M 参数模型,适合关注表征压缩与迁移的人扫读

中相关;详见方法、贡献和实验边界。

编号2607.08771 优先级P2 类别arXiv new; ECCV 2026; foundation-model distillation 会议arXiv new; ECCV 2026; foundation-model distillation 方法不是 SSL 主方法,但把大 VFM depth 能力蒸馏到 6.1M 参数模型,适合关注表征压缩与迁移的人扫读 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:不是 SSL 主方法,但把大 VFM depth 能力蒸馏到 6.1M 参数模型,适合关注表征压缩与迁移的人扫读。 中相关;详见方法、贡献和实验边界。

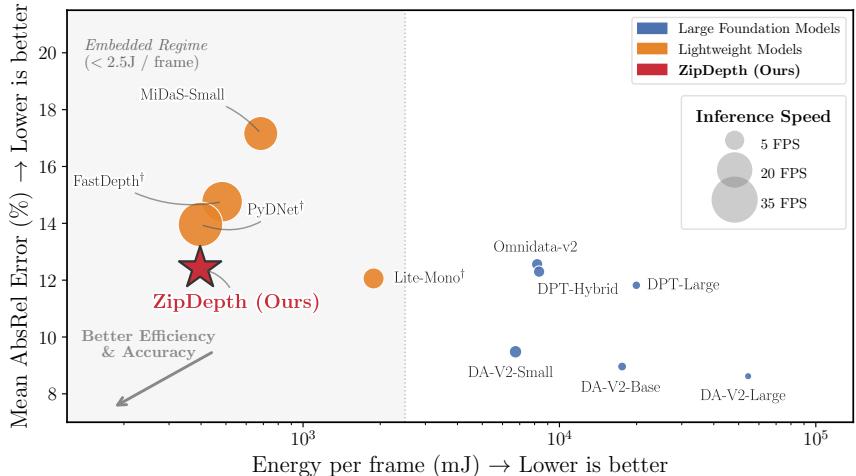
Figureure 2 · : Energy–Accuracy Trade-of
Figureure 2 · : Energy–Accuracy Trade-ofFig. 2: Energy–Accuracy Trade-of. Zero-shot depth models on NVIDIA Jetson Orin NX (15W). Energy per frame (FP32 inference) vs. mean AbsRel (over 5 datasets); bubble size indicates FPS. ZipDepth bridges the gap between lightweight and foundation models, tending toward their accuracy under a < 400 mJ/frame budget. † denotes lightweight baselines retrained on our multi-domain training set for a fair comparison.这张图/表用于判断 ZipDepth 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
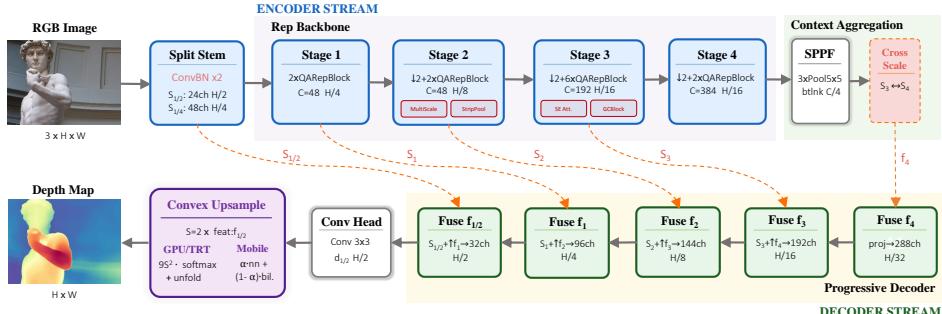
Figureure 3 · : Overview of the ZipDepth architecture
Figureure 3 · : Overview of the ZipDepth architectureFig. 3: Overview of the ZipDepth architecture. The encoder (top, left→right) progressively downsamples the input through four reparameterizable stages; the decoder (bottom, right→left) fuses multi-scale features coarse-to-fine and produces a full-resolution inverse-depth map via hardware-adaptive convex upsampling.这张图概括 ZipDepth 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
核心问题

它和通用视觉自监督的关系在于:不是 SSL 主方法,但把大 VFM depth 能力蒸馏到 6.1M 参数模型,适合关注表征压缩与迁移的人扫读。

方法拆解

不是 SSL 主方法,但把大 VFM depth 能力蒸馏到 6.1M 参数模型,适合关注表征压缩与迁移的人扫读

主要贡献

中相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。