Wat3R:它和通用视觉自监督的关系在于:任务垂直但方法是无标注视频 + teacher-student + cross-view consistency,可迁移到 3D geometry SSL
中相关;详见方法、贡献和实验边界。
Wat3R: Underwater 3D Geometry Learning without Annotations arXiv Fri batch; ECCV 2026; semi/self-supervised 3D geometry 原文链接
编号2607.08772优先级P3类别arXiv Fri batch; ECCV 2026; semi/self-supervised 3D geometry会议arXiv Fri batch; ECCV 2026; semi/self-supervised 3D geometry方法任务垂直但方法是无标注视频 + teacher-student + cross-view consistency,可迁移到 3D geometry SSL来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:任务垂直但方法是无标注视频 + teacher-student + cross-view consistency,可迁移到 3D geometry SSL。 中相关;详见方法、贡献和实验边界。
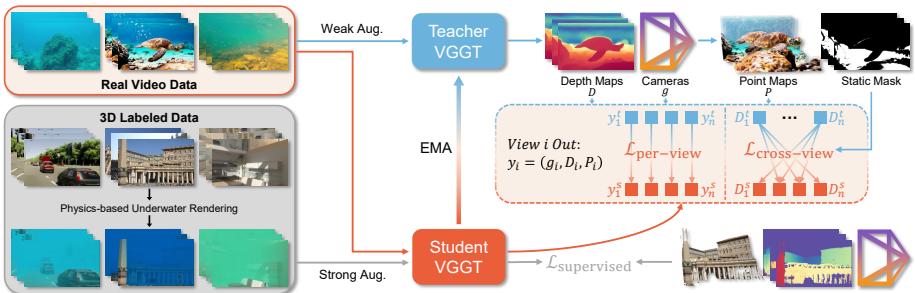
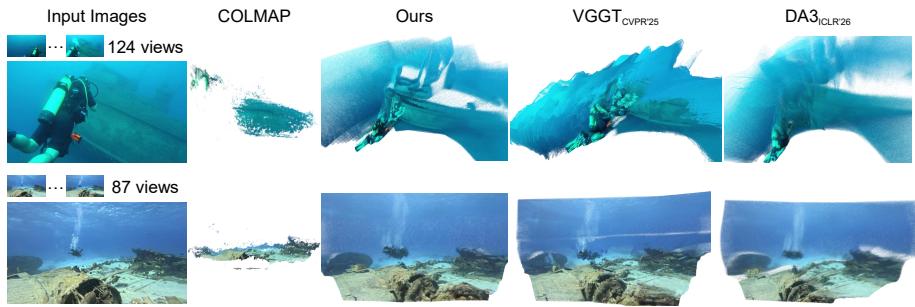
Figureure 3 · : Overview of our Wat3R frameworkFig. 3: Overview of our Wat3R framework. Our pipeline follows a Mean Teacher semi-supervised paradigm, where the teacher network produces pseudo-labels for depth, camera parameters, and point maps to supervise the student network. Training leverages labeled synthetic underwater data together with unlabeled real underwater videos, enabling adaptation without underwater 3D annotations. Additional per-view and cross-view consistency losses enforce multi-view geometric coherence.这张图概括 Wat3R 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。FigFig. A3: Examples of challenging scenes from Water3D. During the construction of the dataset, we use an improved COLMAP [32] pipeline to reconstruct point clouds from raw underwater videos. However, many scenes still lead to unstable or degenerate reconstructions due to scattering efects, low texture, and limited camera motion. For comparison, we also show the results of Wat3R, VGGT [40], and DA3 [22]. While COLMAP fails to produce reliable reconstructions in these cases, our method is able to generate more coherent and geometrically consistent point clouds.这张图概括 Wat3R 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
核心问题
它和通用视觉自监督的关系在于:任务垂直但方法是无标注视频 + teacher-student + cross-view consistency,可迁移到 3D geometry SSL。
方法拆解
任务垂直但方法是无标注视频 + teacher-student + cross-view consistency,可迁移到 3D geometry SSL