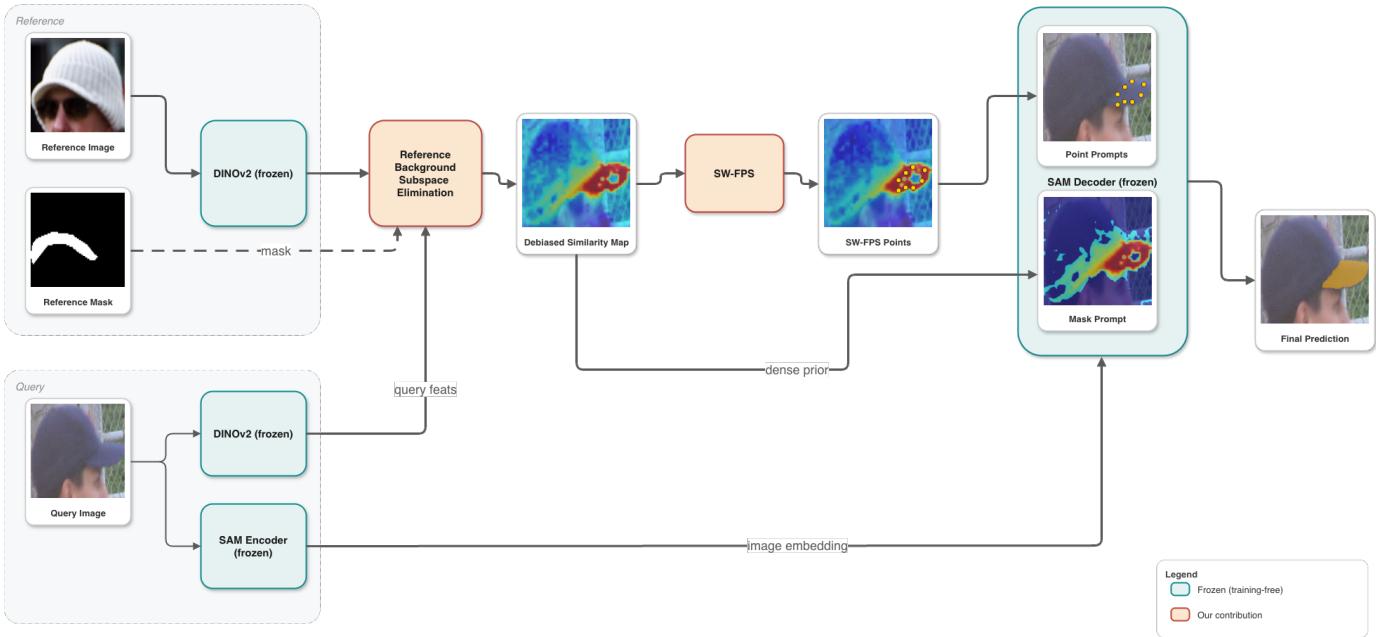
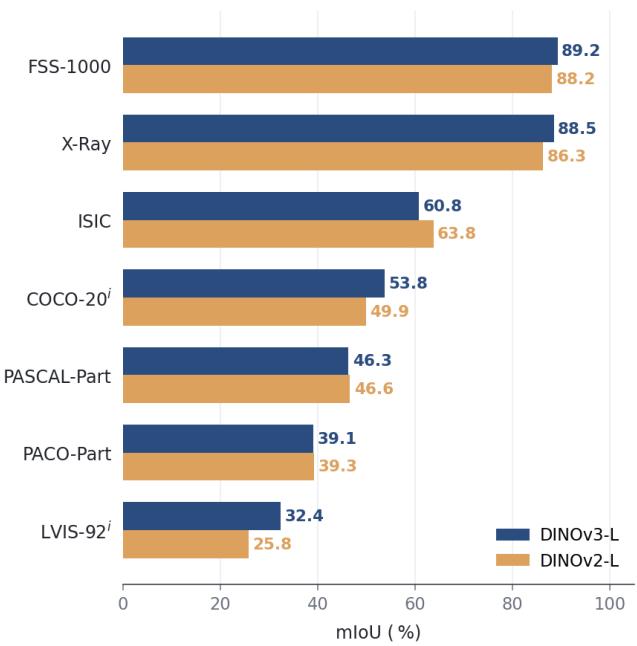
REBASE — training-free one-shot segmentation Figure 2REBASE — training-free one-shot segmentation Figure 2. Overview of REBASE. Given a reference image with its binary mask and a query image, both are encoded by a frozen DINOv2 backbone to extract dense patch features. The reference background subspace is then eliminated, producing a more discriminative cross-image similarity map between the support foreground and query patches. This similarity map is then converted into two complementary conditioning signals for the frozen SAM mask decoder: (i) K spatially diverse point prompts generated via similarity-weighted farthest-point sampling (SW-FPS), and (ii) a dense prior supplied to SAM’s mask-input branch. The entire pipeline is training-free, requiring no parameter updates.这张图概括 REBASE 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figure S1Figure S1. Comparison of DINOv2-L and DINOv3-L backbones. DINOv3-L improves performance on COCO-20<sup>i</sup>, LVIS-92<sup>i</sup>, X-Ray and FSS-1000, while DINOv2-L performs slightly better on ISIC, PASCAL-Part, and PACO-Part. These results indicate that the relative strengths of the two backbones are dataset-dependent.这张图/表用于判断 REBASE 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。