先说结论。它和通用视觉自监督的关系在于:冻结 VGGT 后探测其几何 foundation representation 是否隐式编码 co-visibility。 中高相关;详见方法、贡献和实验边界。
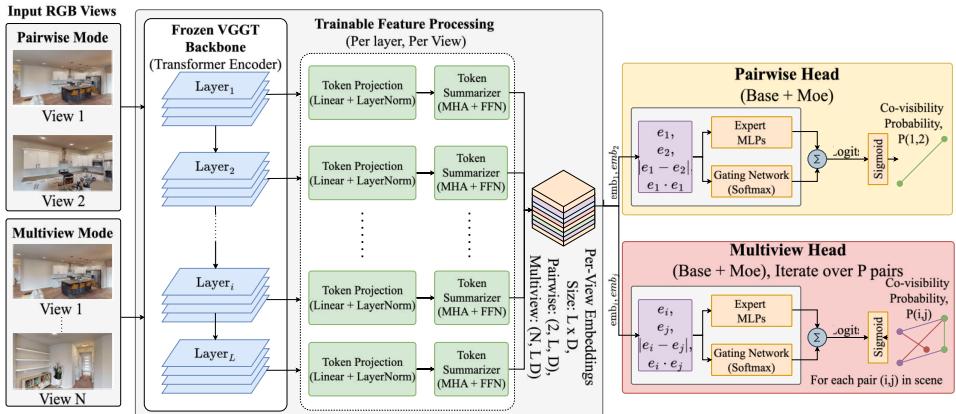
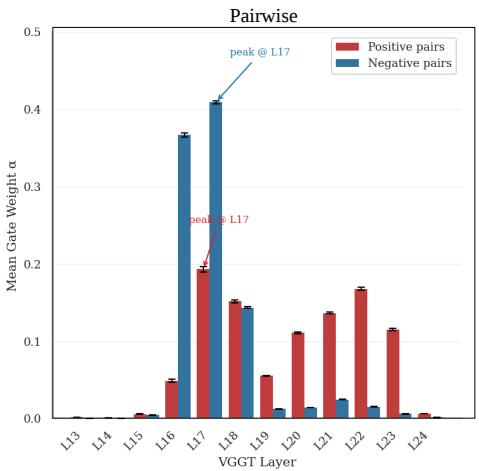
Figureure 2 · : Overview of the Co-VGGT methodFig. 2: Overview of the Co-VGGT method. Input RGB views are processed by the frozen VGGT backbone to extract layer-wise features. These features are projected, summarized, and formed into per-view embeddings. In both pairwise and multiview modes, these embeddings are used to construct pair features, which are then fed into a trainable Mixture-of-Experts (MoE) head to predict co-visibility probabilities, enabling the construction of scene-level visibility graphs. Tensor shapes are annotated for key intermediate representations.这张图概括 What VGGT Knows About Overlap 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 6 · : MoE Gating weightsFig. 6: MoE Gating weights. Average α parameter per-layer vs. layer id. on the multiview (left) and pairwise (right) task. We observe that specific layers are decisive for the final co-visibility analysis.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 What VGGT Knows About Overlap 的方法或实验,请结合正文精读段落一起看。
核心问题
它和通用视觉自监督的关系在于:冻结 VGGT 后探测其几何 foundation representation 是否隐式编码 co-visibility。
方法拆解
冻结 VGGT 后探测其几何 foundation representation 是否隐式编码 co-visibility