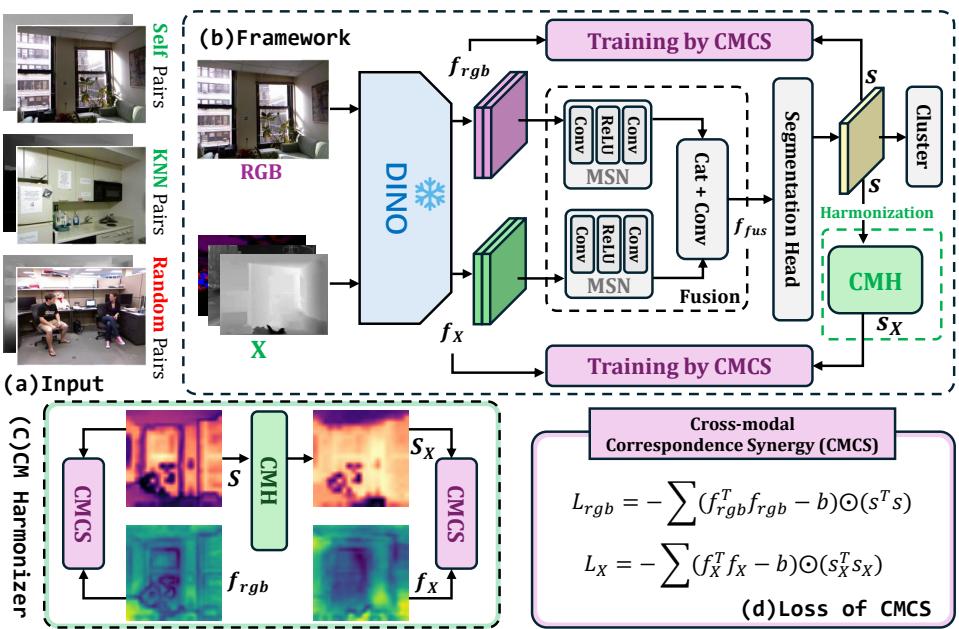
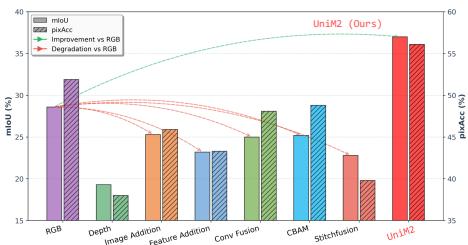
Figureure 2 · : UniM2 Framework OverviewFig. 2: UniM2 Framework Overview. (a) Training inputs for UniM2, (b) The overall architecture of UniM2, (c) The Cross-modal Harmonization process, and (d) the formulation of the CMCS loss. For illustration, (c) and (d) are depicted based on the Self pair scenario to resolve cross-modal structural contradictions.这张图概括 UMSS 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。(b) Performance Comparison Fig(b) Performance Comparison Fig. 1: Analysis of multi-modal integration in unsupervised semantic segmentation. (a) We explore various fusion schemes, including naive Image Addition, Feature Addition, and Conv Fusion, as well as SOTA fusion methods in MSS such as CBAM [67] and StitchFusion [31]. (b) Quantitative results on NYU-Depth-v2 [49] demonstrate that existing advanced fusion strategies in multi-modal segmentation inevitably lead to performance degradation compared to the single RGB baseline in the unsupervised setting, while our UniM2 achieves significant mIoU gains.这张图/表用于判断 UMSS 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。