CoRe: A Comprehensive Framework for Cross-Image Comparative Reasoning in Vision-Language Models arXiv new + ACM MM 2026; cross-image VLM reasoning 原文链接
编号2607.12786优先级P3类别arXiv new + ACM MM 2026; cross-image VLM reasoning会议arXiv new + ACM MM 2026; cross-image VLM reasoning方法构造 cross-image comparative reasoning 数据和 reward,关注 fine-grained attribute grounding来源arXiv / OpenReview
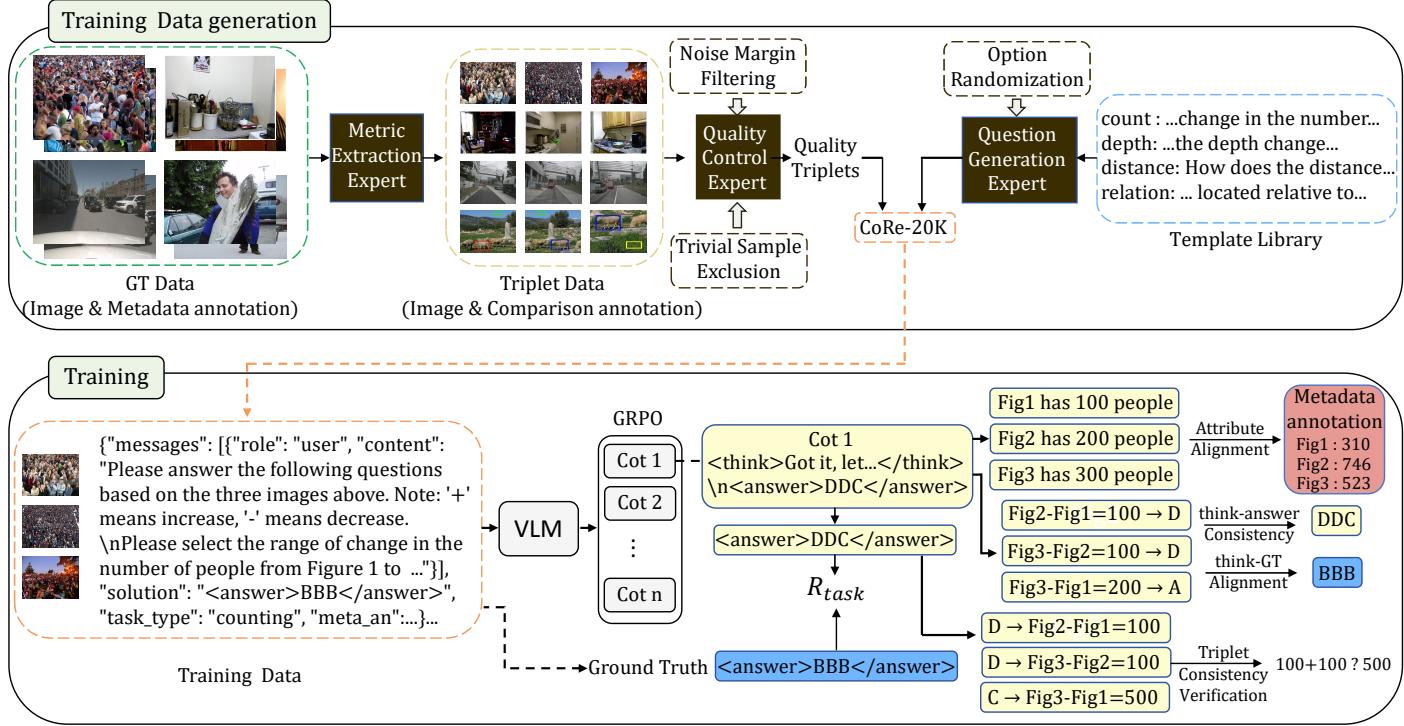
Figureure 3 · : Overview of the CoRe framework.(Top) Training Data Construction: A mFigure 3: Overview of the CoRe framework.(Top) Training Data Construction: A multi-expert pipeline builds CoRe-20K from structured metadata. The Metric Extraction Expert derives per-image metric values from task-specific annotations; the Quality Control Expert filters low-quality triplets via Noise Margin Filtering and Trivial Sample Exclusion; the Question Generation Expert instantiates multiple-choice questions from a Template Library with Option Randomization to eliminate answer-position bias. (Bottom) TriSR-Guided GRPO Training: The VLM generates <sup>??</sup> chain-of-thought responses evaluated by a composite structured reward combining Attribute Alignment, Think–Answer Consistency, Think–GT Alignment, and Triplet Consistency Verification, which are aggregated into a group-normalized advantage to update the policy via GRPO.这张图概括 CoRe 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Gemini-3-Pro: The blinds are located..., The monitor is part of a pointof-sale system...,TGemini-3-Pro: The blinds are located..., The monitor is part of a pointof-sale system...,The depth of the blinds in Figure 1 is significantly greater than the depth of the monitor in Figure 2.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 CoRe 的方法或实验,请结合正文精读段落一起看。