arXiv new; video diffusion analysis · P3 · 2026-07-16
The Seriality Gap in Video:它和通用视觉自监督的关系在于:分析 video diffusion 在长串因果事件上的 seriality gap,有助判断生成式视频模型能否当通用视觉 learner
中相关;详见方法、贡献和实验边界。
The Seriality Gap in Video Diffusion Models arXiv new; video diffusion analysis 原文链接
编号2607.13031优先级P3类别arXiv new; video diffusion analysis会议arXiv new; video diffusion analysis方法分析 video diffusion 在长串因果事件上的 seriality gap,有助判断生成式视频模型能否当通用视觉 learner来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:分析 video diffusion 在长串因果事件上的 seriality gap,有助判断生成式视频模型能否当通用视觉 learner。 中相关;详见方法、贡献和实验边界。
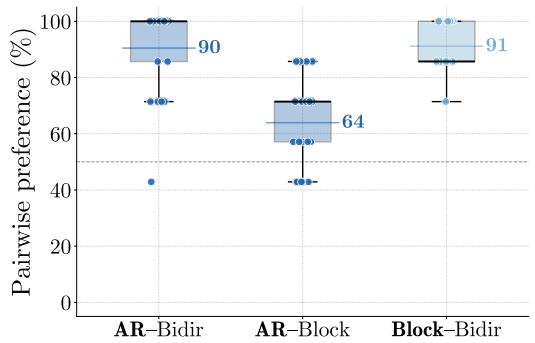
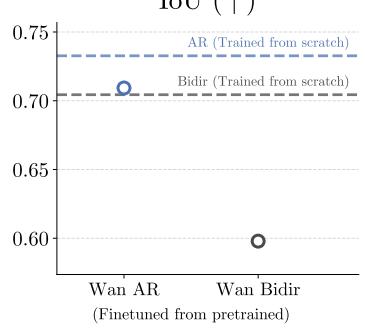
Figureure 11 · : Human preference studyFigure 11: Human preference study. Left: aggregate preference rates by model show that AR and Block-3 generations are preferred substantially more often than bidirectional generations. Right: pairwise preferences show strong human preference for AR over Bidir and Block-3 over Bidir, while AR is only moderately preferred over Block-3. This matches the rollout-error ranking, suggesting that large differences in $\Delta x ^ { ( 5 ) }$ correspond to perceptually salient differences in physical plausibility.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 The Seriality Gap in Video 的方法或实验,请结合正文精读段落一起看。Figureure 10 · : Wan initialization preserves the model ordering but lowers absolute Figure 10: Wan initialization preserves the model ordering but lowers absolute performance. Global trajectory error $\bar { \Delta } x ^ { \mathrm { ( G T ) } }$ , rollout-5 error $\Delta x ^ { ( 5 ) }$ , and IoU for models fine-tuned from Wan2.1-T2V-1.3B. Circles show the fine-tuned models, and dashed lines show the corresponding models trained from scratch. AR retains lower errors and higher IoU than Bidir, but both fine-tuned models underperform their trained-from-scratch counterparts, possibly because of a resolution mismatch and the out-of-distribution hard-sphere task.这张图/表用于判断 The Seriality Gap in Video 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:分析 video diffusion 在长串因果事件上的 seriality gap,有助判断生成式视频模型能否当通用视觉 learner。
方法拆解
分析 video diffusion 在长串因果事件上的 seriality gap,有助判断生成式视频模型能否当通用视觉 learner