通用视觉自监督研究报
A Daily Digest of Visual Self-Supervised Learning
2026-07-17 图像表征 · VFM · JEPA · 视频预训练
arXiv new/cross; ACM MM 2026; video LLM diagnostic · P2 · 2026-07-17

Accuracy Without Grounding:它和通用视觉自监督的关系在于:证明视频 LLM benchmark accuracy 与真实视觉依赖可以分离,提出 Visual Dependency Gap

中高相关;详见方法、贡献和实验边界。

编号2607.13305 优先级P2 类别arXiv new/cross; ACM MM 2026; video LLM diagnostic 会议arXiv new/cross; ACM MM 2026; video LLM diagnostic 方法证明视频 LLM benchmark accuracy 与真实视觉依赖可以分离,提出 Visual Dependency Gap 来源arXiv / OpenReview

先说结论。它和通用视觉自监督的关系在于:证明视频 LLM benchmark accuracy 与真实视觉依赖可以分离,提出 Visual Dependency Gap。 中高相关;详见方法、贡献和实验边界。

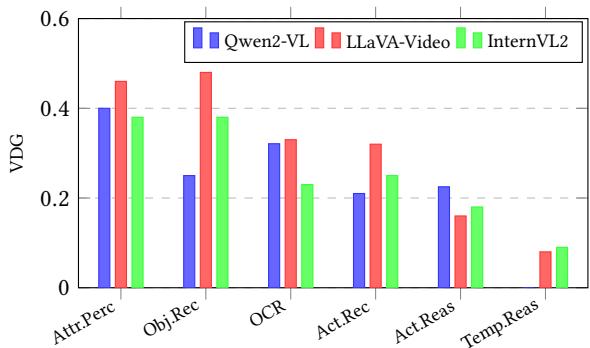
Figureure 2 · : Visual Dependency Gap (VDG) by task type on Video-MME
Figureure 2 · : Visual Dependency Gap (VDG) by task type on Video-MMEFigure 2: Visual Dependency Gap (VDG) by task type on Video-MME. Temporal Reasoning shows VDG <sub>≈</sub> 0 for all three architectures, while Attribute Perception shows consistently high VDG. The ranking is stable across three architecturally distinct models (mean pairwise $r = 0 . 7 8 9$ , individual pairs range from $\textstyle p > 0 . 0 5$ to $ { p } = 0 . 0 0 8$ at $k = 6 ,$ , see text).这张图概括 Accuracy Without Grounding 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
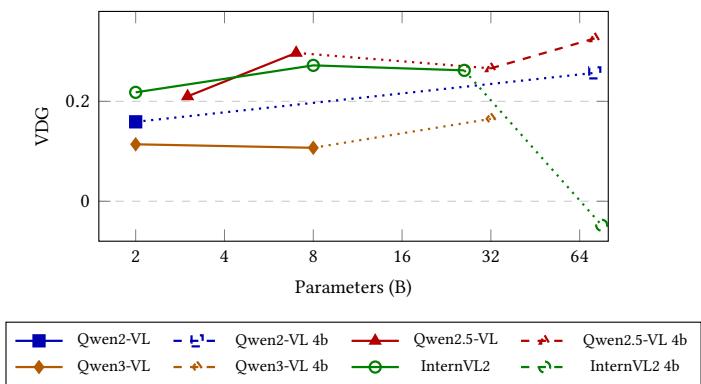
Figureure 3 · : VDG vs
Figureure 3 · : VDG vsFigure 3: VDG vs. model scale across four families. Solid markers = bf16, open/dashed = 4-bit NF4. Qwen2.5-VL shows VDG increasing with scale, while Qwen3-VL shows a generation regression.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Accuracy Without Grounding 的方法或实验,请结合正文精读段落一起看。
核心问题

它和通用视觉自监督的关系在于:证明视频 LLM benchmark accuracy 与真实视觉依赖可以分离,提出 Visual Dependency Gap。

方法拆解

证明视频 LLM benchmark accuracy 与真实视觉依赖可以分离,提出 Visual Dependency Gap

主要贡献

中高相关;详见方法、贡献和实验边界。

实验看点

实验部分建议重点看两类证据:一是作者是否把方法收益和更强数据、更长训练、更大模型区分开;二是跨模型、跨数据或跨任务迁移是否还能保留同样趋势。

局限与读法

这篇论文的结论需要结合任务设置、训练数据规模和消融实验一起看;不要只凭单个指标判断它对通用视觉表征的价值。