先说结论。它和通用视觉自监督的关系在于:用冻结 DINOv3 特征验证跨身份、跨时间的局部区域对应,核心问题是自监督 ViT 是否形成 dense semantic coordinate system。 高相关;详见方法、贡献和实验边界。
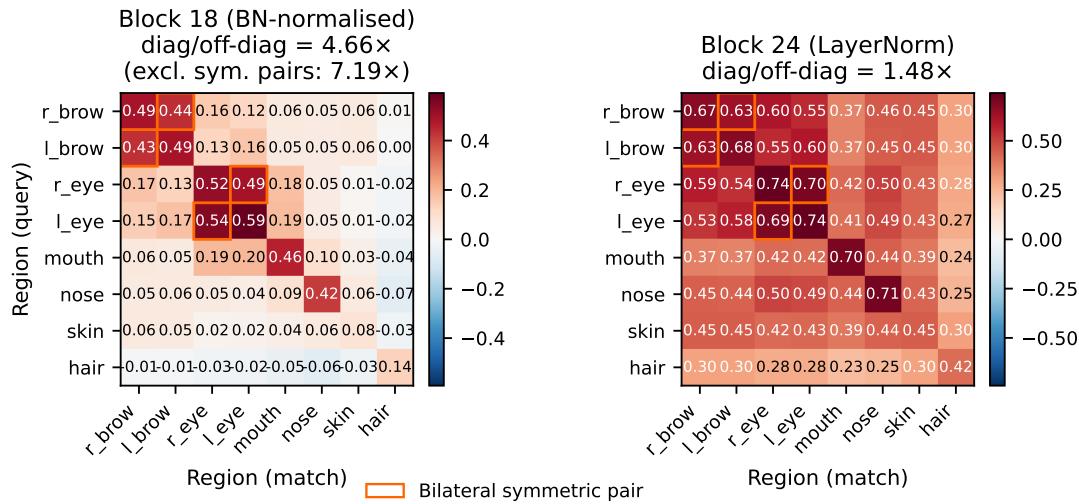
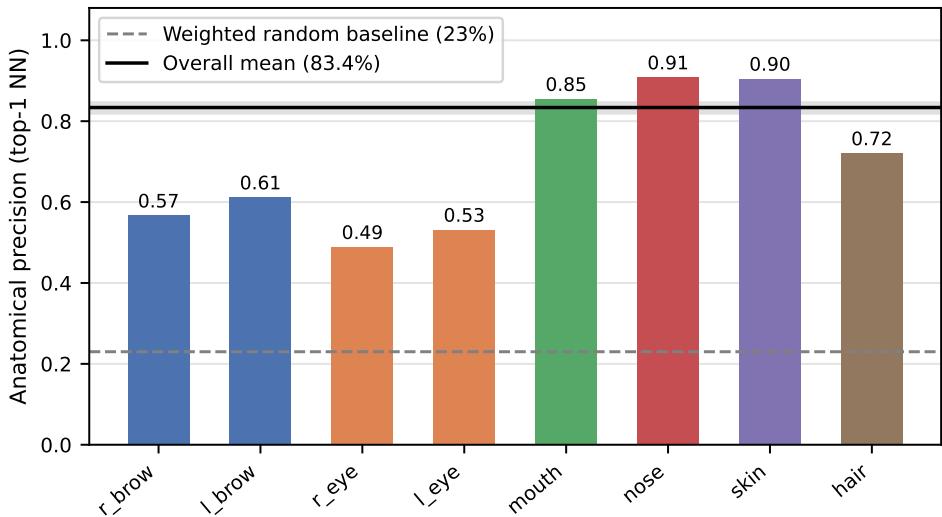
Figureure 1 · : $8 \times 8$ cross-identity region confusion matrix (50 face pairs)Figure 1: $8 \times 8$ cross-identity region confusion matrix (50 face pairs). Block-18 diagonal is 4.93× the off-diagonal (rising to 7.19× excluding the symmetric pairs in orange boxes). Block-24 collapses to 1.48× due to global LayerNorm mixing.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 Emergent Region-Level Facial Correspondence in 的方法或实验,请结合正文精读段落一起看。C2: Cross-Identity Anatomical Precision tok\_b18 200 pairs · unconstrained NN · n\_pairs=2C2: Cross-Identity Anatomical Precision tok\_b18 200 pairs · unconstrained NN · n\_pairs=200 Figure 2: Per-region semantic accuracy for tok\_b18 (200 pairs, unconstrained NN). Dashed: weighted random baseline (23.0%). Solid: overall mean (83.4%). Brow and eye regions achieve 0.49–0.61 against ≤0.4% random chance.这张图/表用于判断 Emergent Region-Level Facial Correspondence in 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。
核心问题
它和通用视觉自监督的关系在于:用冻结 DINOv3 特征验证跨身份、跨时间的局部区域对应,核心问题是自监督 ViT 是否形成 dense semantic coordinate system。
方法拆解
用冻结 DINOv3 特征验证跨身份、跨时间的局部区域对应,核心问题是自监督 ViT 是否形成 dense semantic coordinate system