Uni-AdaVD:它和通用视觉自监督的关系在于:把多模态 attention value space 当作统一干预空间,和视觉生成模型安全及语义方向控制相关
中相关;详见方法、贡献和实验边界。
Uni-AdaVD: Universal Concept Erasure for Visual Generation via Orthogonal Value Decomposition arXiv new; visual generation concept erasure 原文链接
编号2607.14521优先级P3类别arXiv new; visual generation concept erasure会议arXiv new; visual generation concept erasure方法把多模态 attention value space 当作统一干预空间,和视觉生成模型安全及语义方向控制相关来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:把多模态 attention value space 当作统一干预空间,和视觉生成模型安全及语义方向控制相关。 中相关;详见方法、贡献和实验边界。
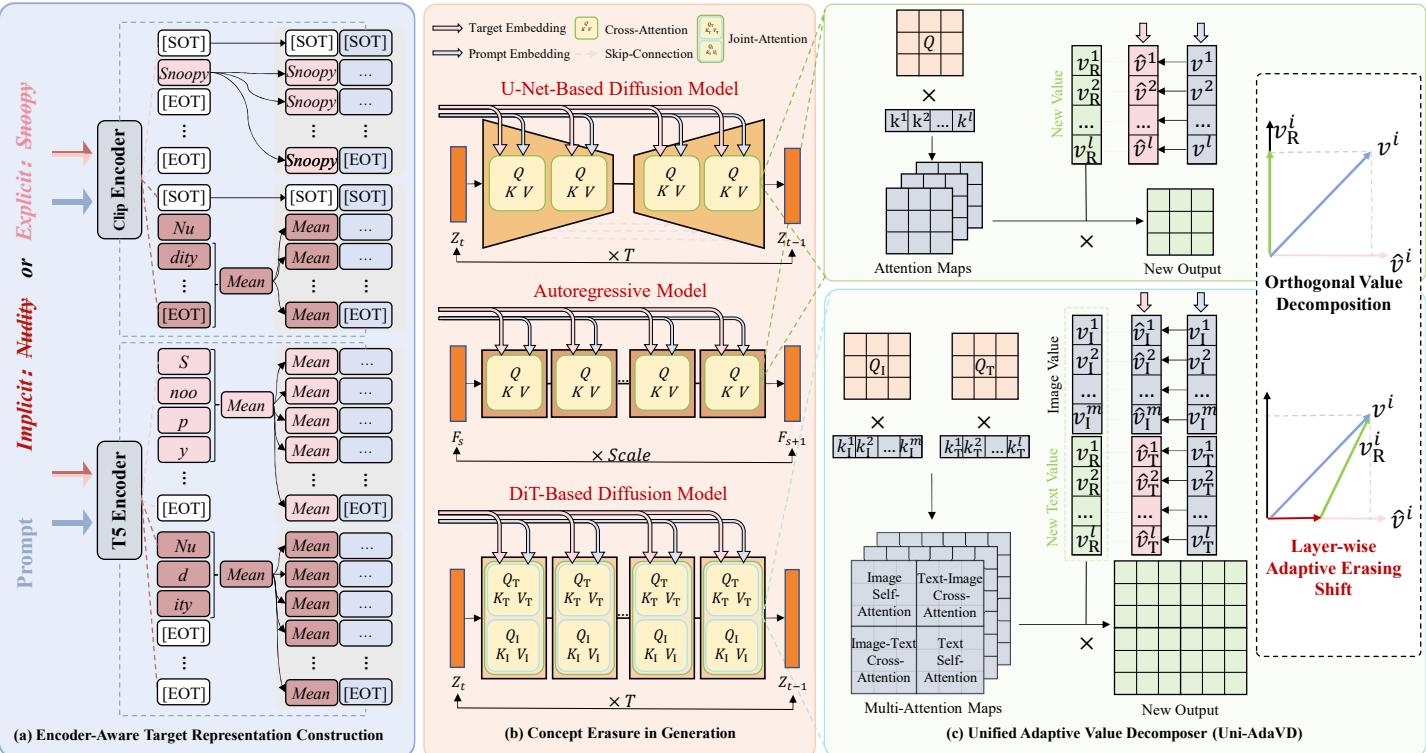
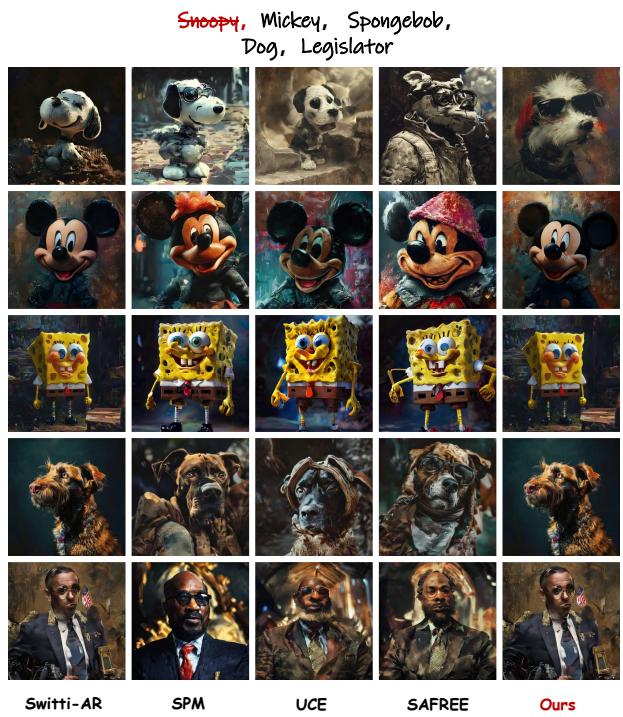
Figureure 2 · Overview of our Uni-AdaVDFig. 2. Overview of our Uni-AdaVD. a. Encoder-aware Target Representation Construction: For T5 [50] encoders, we average the valid tokens excluding padding and end-of-text tokens, tiling the result to the maximum sequence length. For CLIP [51] encoders, explicit concepts use the last subject token, while implicit concepts use the aggregated mean from the last subject to the end-of-text token, with both similarly tiled to the fixed sequence length. b. Concept Erasure in Generation: Demonstrates the integration of our value-space intervention mechanism within the generative pipelines of diverse architectures, including U-Net- and DiT-based diffusion models and AR models. c. Uni-AdaVD: Details the core operations of our framework, which employs Orthogonal Value Decomposition (OVD) to erase target concepts in the value space and utilizes Layerwise Adaptive Erasing Shift (LAES) to adaptively modulate erasure strength for high-fidelity prior preservation.这张图概括 Uni-AdaVD 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。FigFig. S6. Qualitative comparison of instance concept erasure on the Switti-AR architecture. We target the single concept “Snoopy” while assessing the prior preservation of non-target concepts. Uni-AdaVD removes the targeted identity, while largely preserving the semantic and structural integrity of non-target concepts compared to baselines.这张图概括 Uni-AdaVD 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
核心问题
它和通用视觉自监督的关系在于:把多模态 attention value space 当作统一干预空间,和视觉生成模型安全及语义方向控制相关。
方法拆解
把多模态 attention value space 当作统一干预空间,和视觉生成模型安全及语义方向控制相关