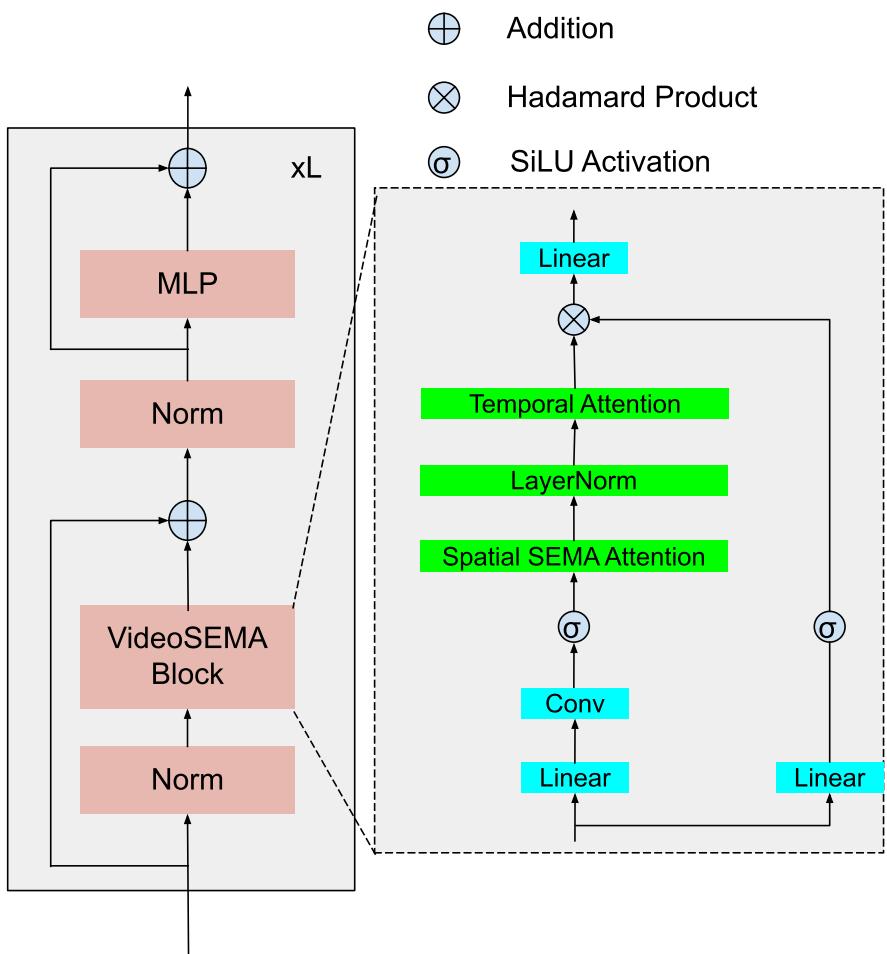
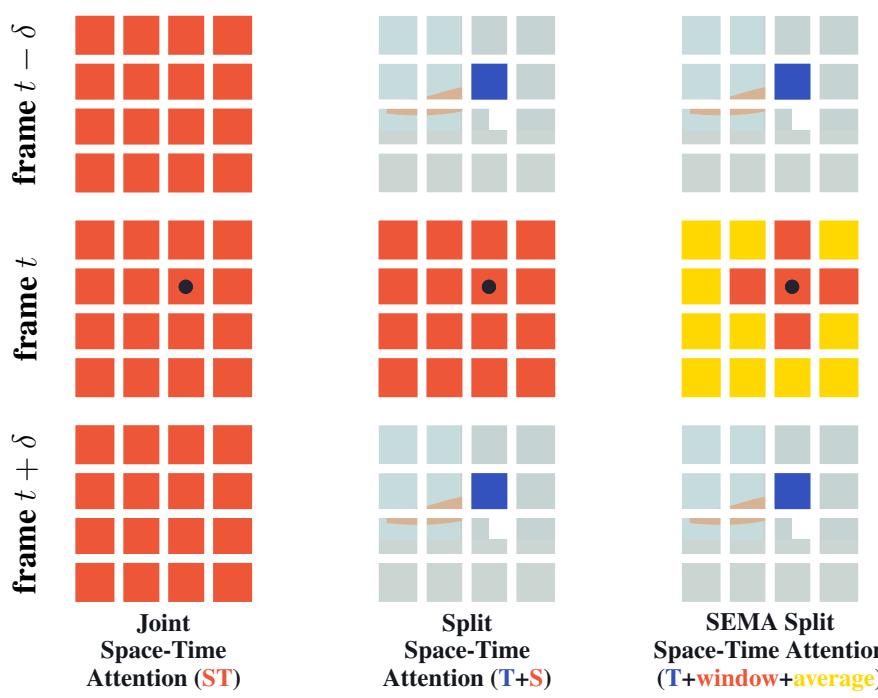
Figureure 1 · : Overview of VideoSEMA macro-structure.Figure 1: Overview of VideoSEMA macro-structure.这张图概括 VideoSEMA 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 2 · : Visualization of space time attention typesFigure 2: Visualization of space time attention types. For illustration, the dark dot denotes the query patch and colored patches show its self-attention space-time neighborhood under each scheme. Patches without color are not used for the self-attention computation of the query patch. Multiple colors within a scheme denote attentions separately applied along different dimensions, e.g., space and time for $( T + S )$ . Note that self-attention is computed for every single patch in the video clip, i.e., every patch serves as a query. Although the attention pattern is shown for only two adjacent frames, it extends in the same fashion to all frames of the clip.这张可视化用来解释 VideoSEMA 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。