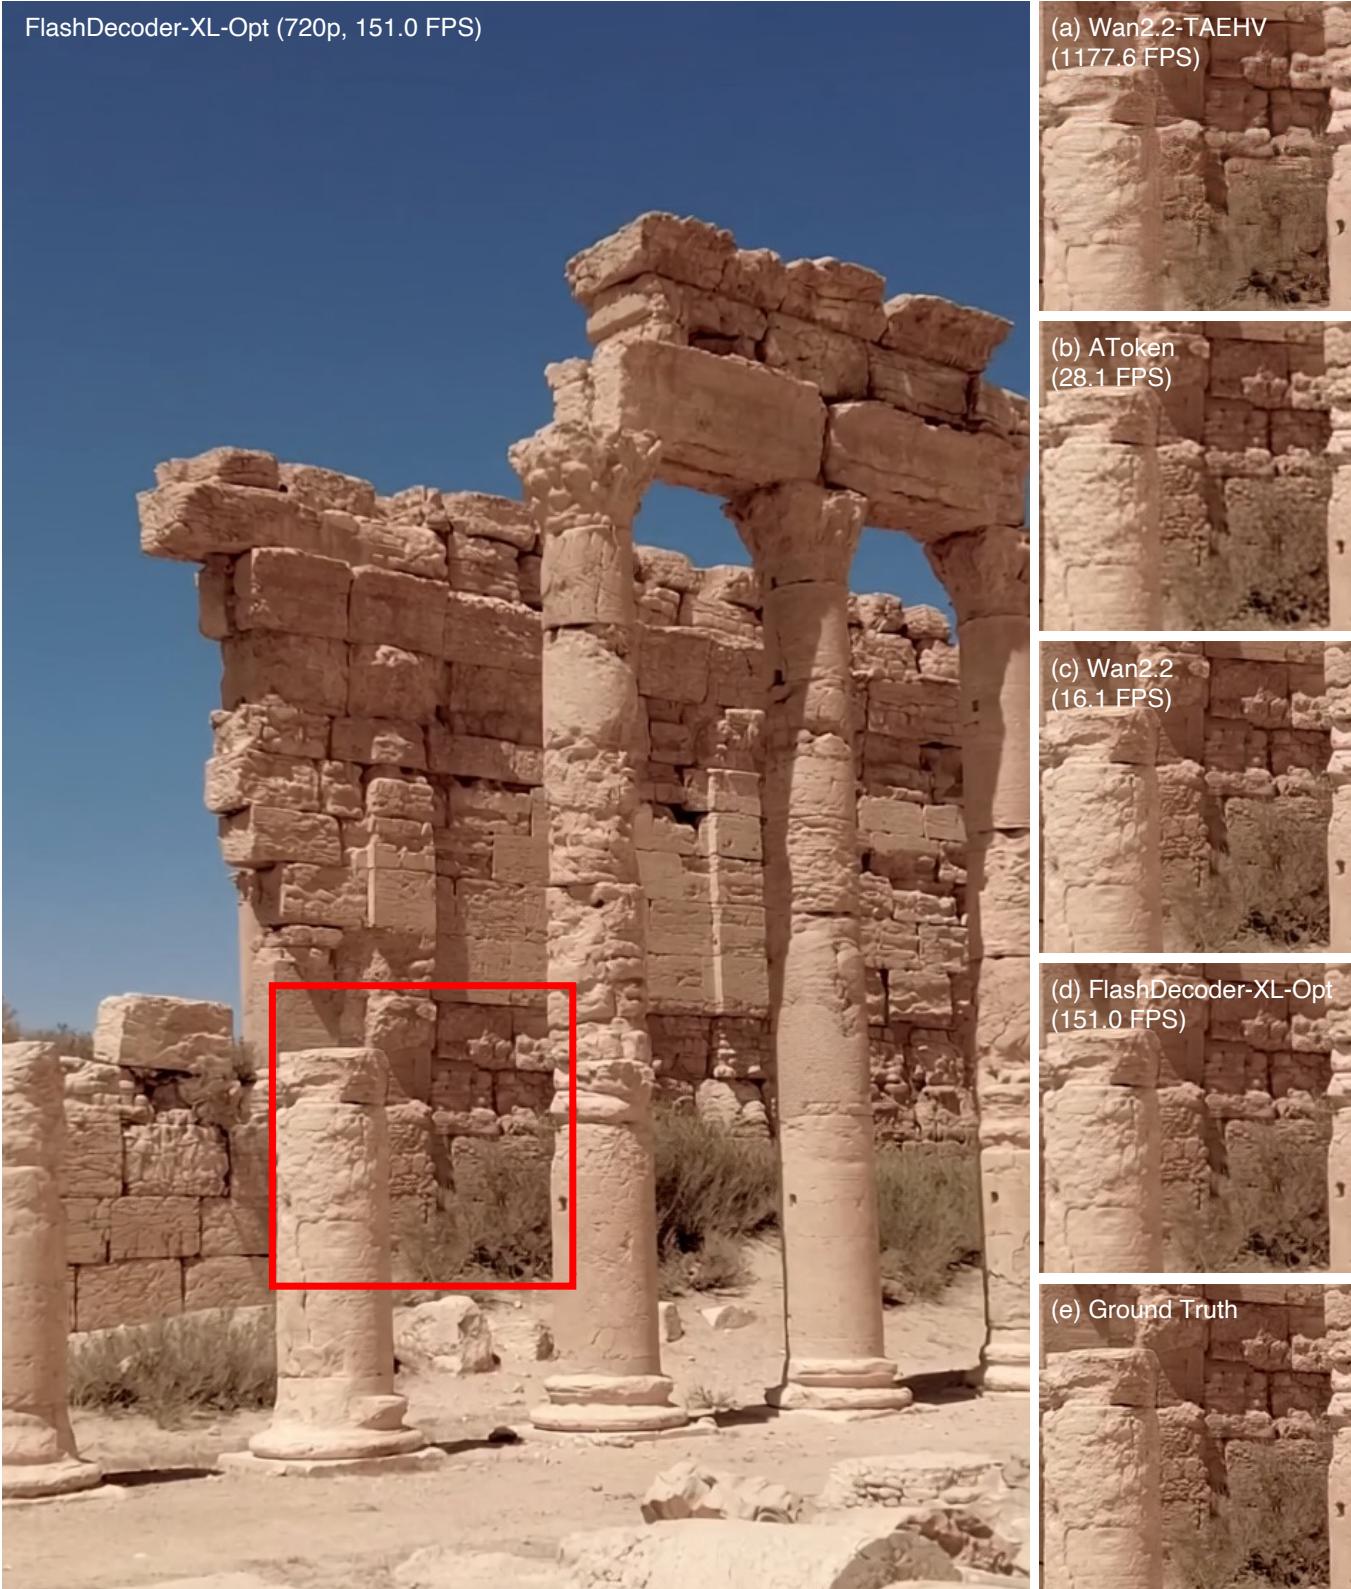
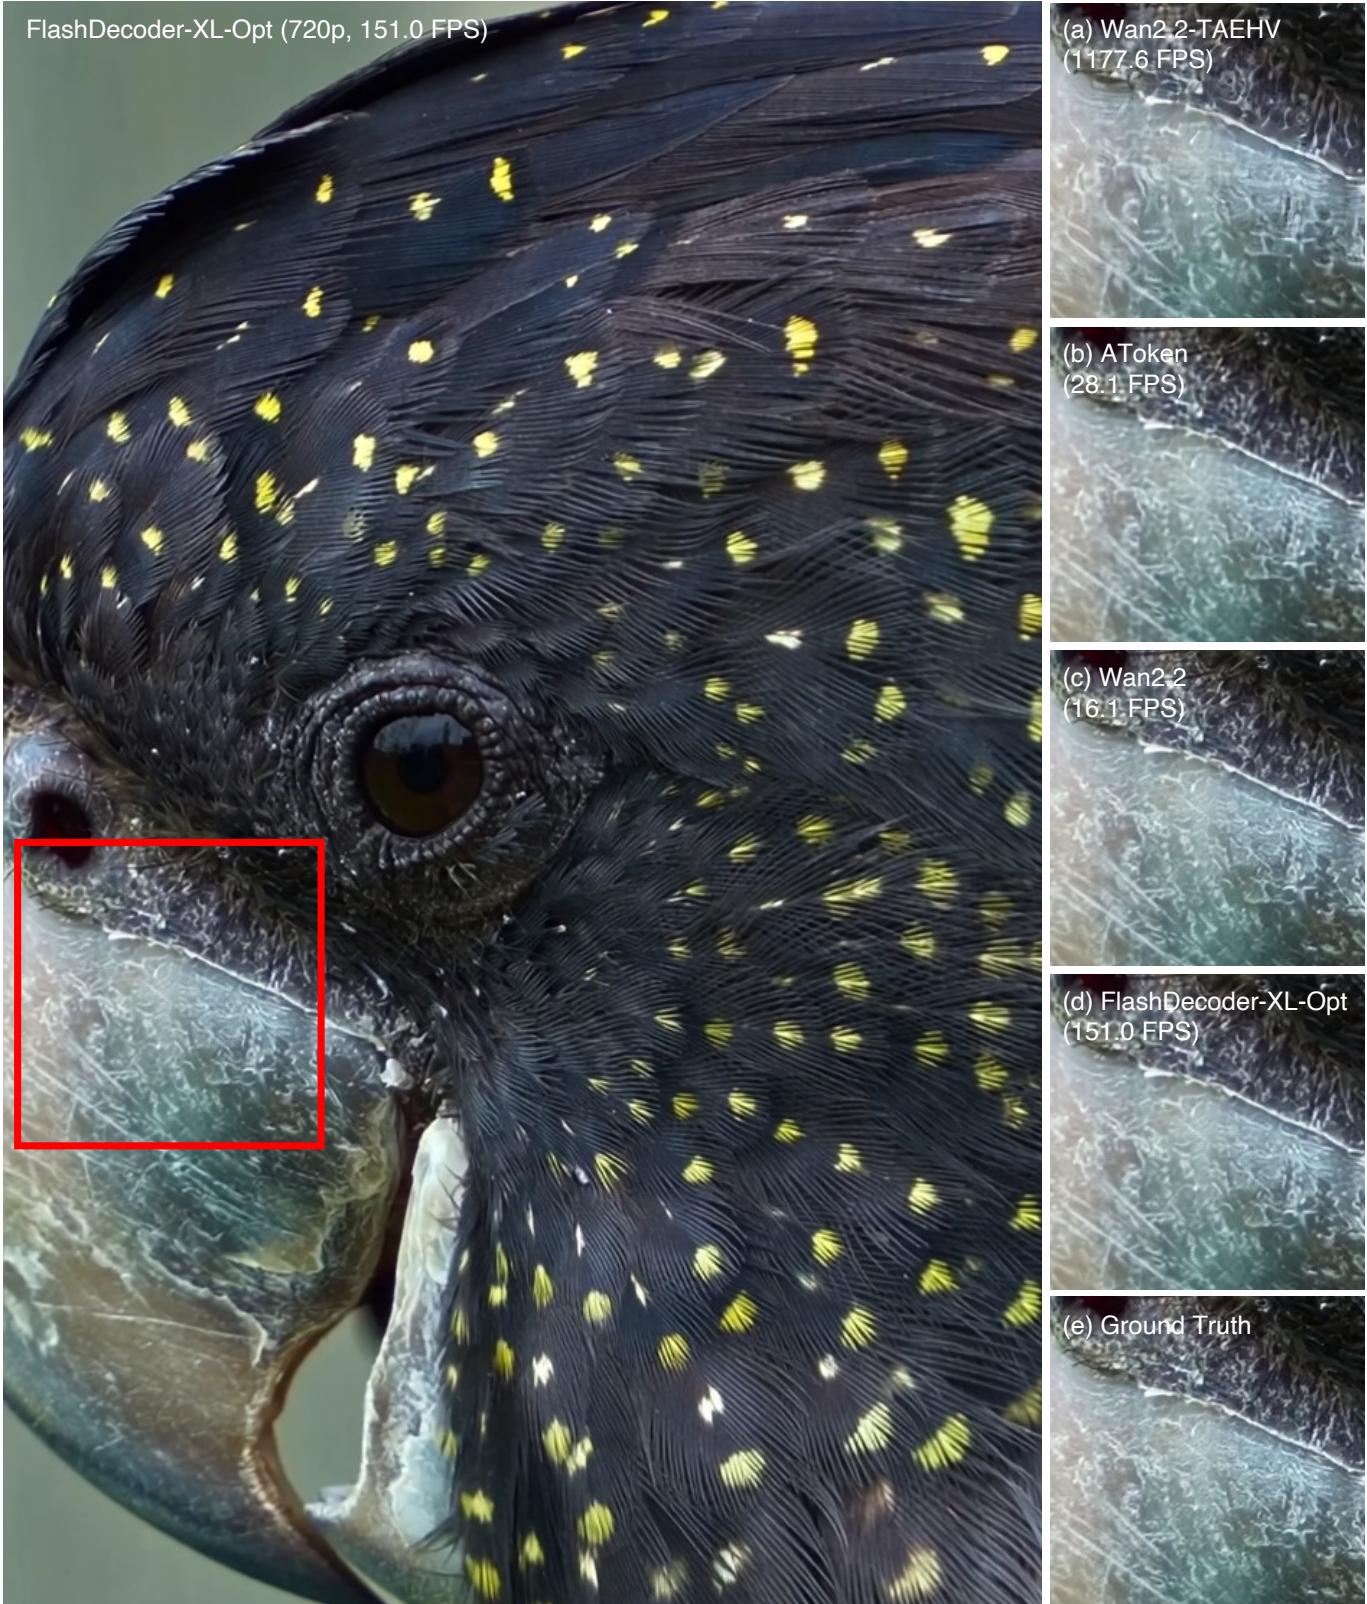
Figureure 2 · Qualitative comparison of 720p reconstruction resultsFigure 2. Qualitative comparison of 720p reconstruction results. We compare reconstructed frames from video decoders with 4× temporal and 16× spatial compression: (a) Wan2.2-TAEHV [3], (b) AToken [37], (c) Wan2.2 [65], (d) our FlashDecoder-XL-Opt, and (e) ground truth. (a) fails to synthesize fine details such as wall textures, while (b) produces blurry reconstructions. (c) and (d) yield visually comparable outputs, yet (d) achieves over 9× higher throughput (151.0 vs. 16.1 FPS). Additional comparisons are provided in the supplementary material.这张图/表用于判断 FlashDecoder 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。Figure AFigure A. Qualitative comparison of 720p reconstruction results. We compare reconstructed frames from video decoders with 4× temporal and 16× spatial compression: (a) Wan2.2-TAEHV [3], (b) AToken [37], (c) Wan2.2 [65], (d) our FlashDecoder-XL-Opt, and (e) ground truth. (a) and (b) produce blurry reconstructions, while (c) and (d) yield visually comparable outputs, yet (d) achieves over 9× higher throughput.这张图/表用于判断 FlashDecoder 的实验收益来自哪里。重点看替换、消融或跨模型设置下趋势是否一致,而不是只看单个最高分。