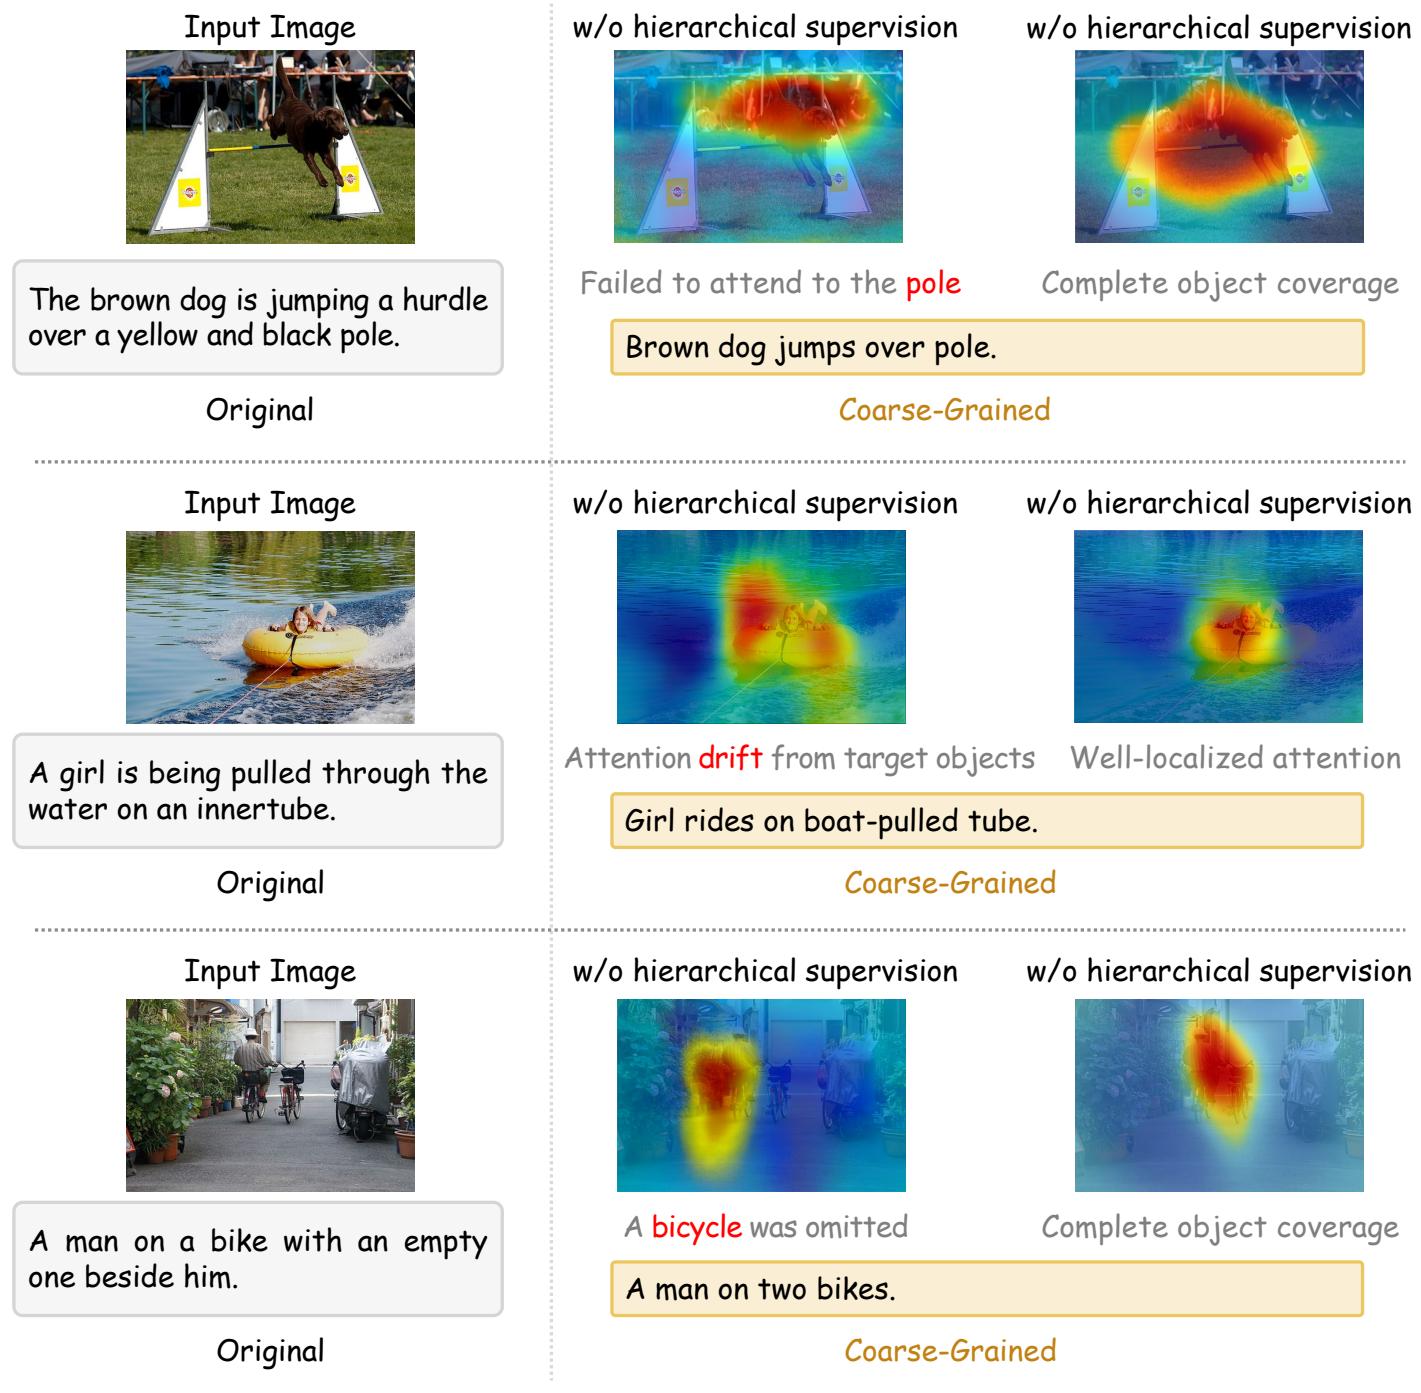
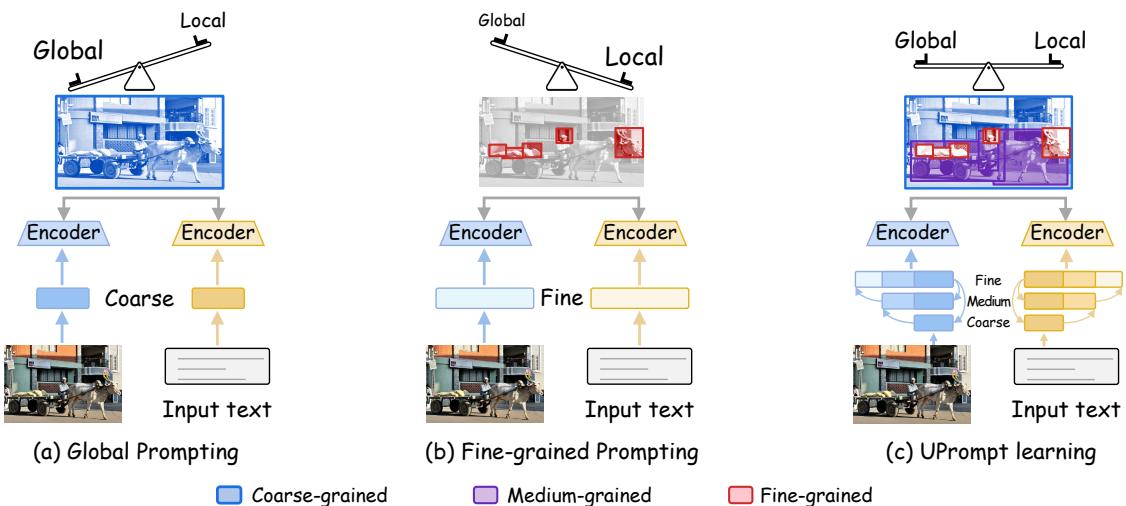
Figureure 11 · : Visual validation of Fine-to-Coarse Hierarchical Supervision (HS)Figure 11: Visual validation of Fine-to-Coarse Hierarchical Supervision (HS). HS prevents semantic drift in coarse-grained representations. Without HS (middle), attention maps show common failures: missing key objects (second bicycle), poor component grounding (pole), or drift to irrelevant backgrounds. With HS (right), fine-level supervision guides coarse models to maintain semantic consistency, producing well-localized attention that accurately reflects textual descriptions.这张可视化用来解释 U-shaped Multi-granularity Learning for Vision-Language 学到的中间表征或对齐关系。重点看它是否支持正文里的机制判断。Figureure 1 · : The granularity trade-of in prompt learningFigure 1: The granularity trade-of in prompt learning. (a) Global prompting captures broad context but lacks fine-grained details, while (b) fine-grained prompting preserves local features but loses global information. (c) UPrompt learning addresses the trade-of through multi-granularity hierarchical modeling, achieving both global understanding and local precision.这张图来自论文 PDF 的结构化抽取。当前用于辅助理解 U-shaped Multi-granularity Learning for Vision-Language 的方法或实验,请结合正文精读段落一起看。