Beyond Single Expert:它和通用视觉自监督的关系在于:动态融合多个视觉 foundation model 先验,说明不同 VFM 对空间/3D 任务的互补性
中相关;详见方法、贡献和实验边界。
Beyond Single Expert: Harmonizing Diverse Visual Priors in MLLMs for Spatial Understanding arXiv new; multi-VFM prior fusion 原文链接
编号2607.15054优先级P2类别arXiv new; multi-VFM prior fusion会议arXiv new; multi-VFM prior fusion方法动态融合多个视觉 foundation model 先验,说明不同 VFM 对空间/3D 任务的互补性来源arXiv / OpenReview
先说结论。它和通用视觉自监督的关系在于:动态融合多个视觉 foundation model 先验,说明不同 VFM 对空间/3D 任务的互补性。 中相关;详见方法、贡献和实验边界。
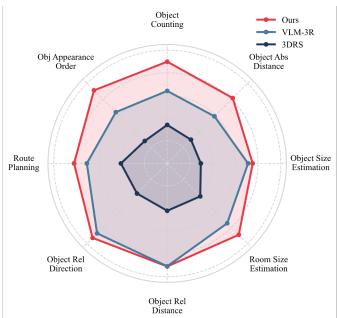
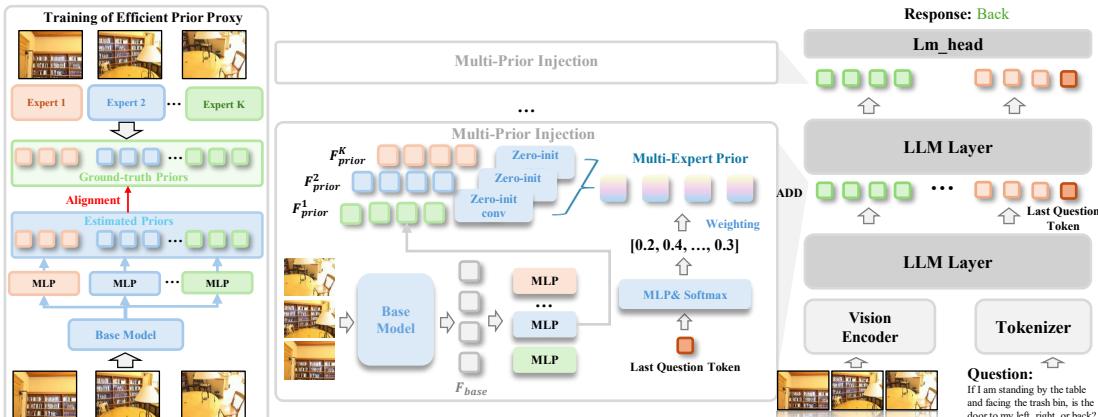
Figureure 1 · : Comparison of Existing Single-Expert Paradigms and Our Multi-Prior FFigure 1: Comparison of Existing Single-Expert Paradigms and Our Multi-Prior Framework. Top-left: Existing paradigms typically rely on a single external encoder (e.g., VGGT) to provide visual priors for MLLMs. Bottom-left: In contrast, our approach integrates diverse knowledge from multiple expert models into the MLLM. Middle and right: Extensive evaluations demonstrate that our method achieves state-of-the-art performance across multiple benchmarks.这张图概括 Beyond Single Expert 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。Figureure 4 · : Overview of the Proposed ViPS FrameworkFigure 4: Overview of the Proposed ViPS Framework. The framework integrates distinct prior knowledge from multiple foundation models via the Efficient Prior Proxy and coordinates them using Dynamic Prior Fusion for comprehensive spatial reasoning.这张图概括 Beyond Single Expert 的整体方法流程。阅读时先看模块之间传递的训练信号,再看作者如何把目标拆成可优化的子问题。
核心问题
它和通用视觉自监督的关系在于:动态融合多个视觉 foundation model 先验,说明不同 VFM 对空间/3D 任务的互补性。
方法拆解
动态融合多个视觉 foundation model 先验,说明不同 VFM 对空间/3D 任务的互补性